Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for Multimodal for the week ending August 7, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
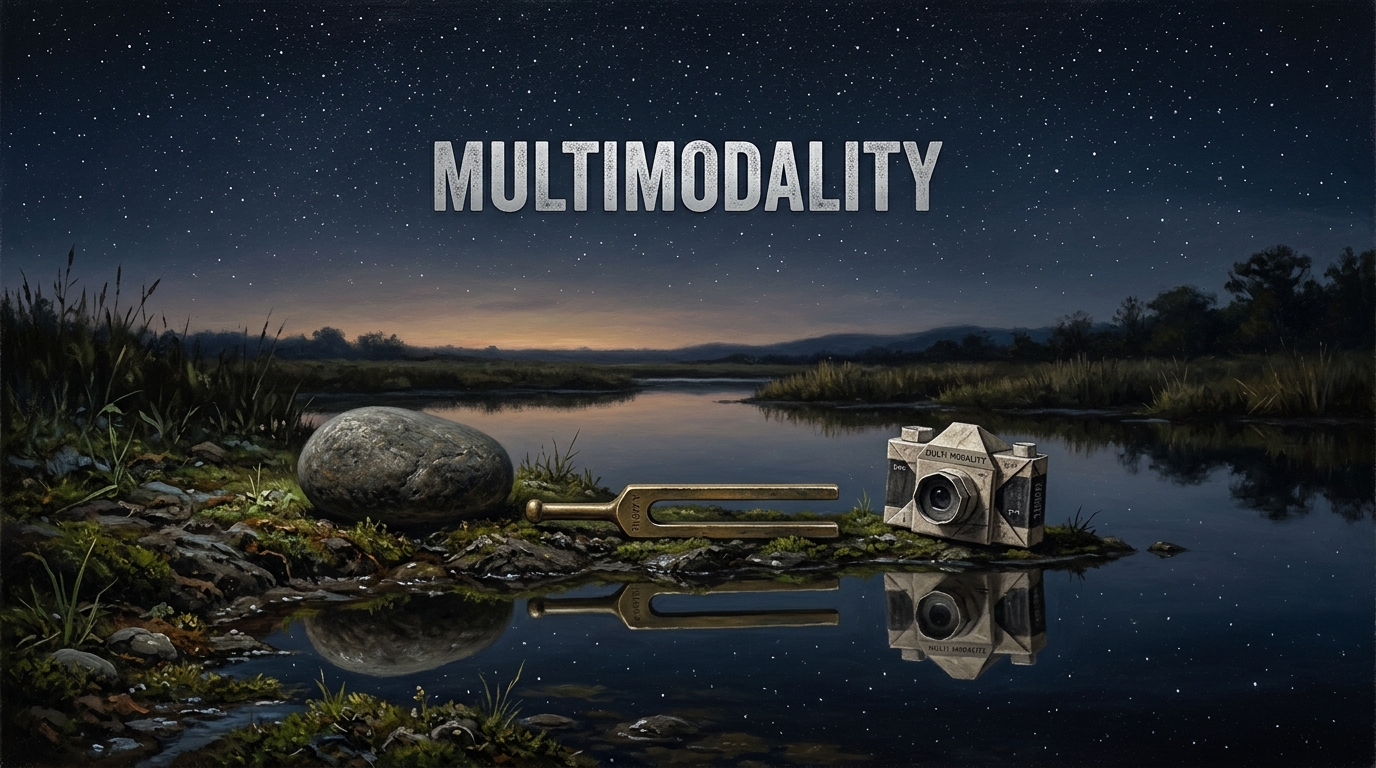
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Gemini 3.1 Flash Image Preview.
Category Cover Image Prompt: A fine-art nocturne of a smooth river stone, a weathered brass tuning fork, and a small folded paper camera resting side by side on the mossy bank of a mirror-still tidal creek, each object half-reflected in the dark glassy water beneath a vast field of silver stars, muted marsh greens and slate grays with a faint warm glow at the far horizon, painterly realism with long-exposure calm, low horizon and generous starlit sky, bold title Multimodality set into the upper negative space.
This Week in Multimodal News
Summary by Claude Sonnet 5.5 based on this week’s links:
- Video generation gets audio: Black Forest Labs launched FLUX 3 Video with native audio, multilingual dialogue, image-to-video and video continuation, and fal said it is available there with up to 20 seconds per generation. MiniMax's H3 is a 33B video model with synchronized stereo audio that reportedly runs on one RTX 5090.
- Realtime voice rebuilt: OpenAI said GPT-Live can listen while it speaks. It rebuilt the voice stack so deeper reasoning and tool use do not interrupt the conversation.
- Vision models and world models: Arena listed Qwen3.8-Max second on Vision Arena at 1,305, just behind Claude Fable 5 (High). Separately, several posts pointed to world models as a growing focus, including a computer-graphics-derived training dataset called CG-World.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to Multimodal
Qwen3.8-Max ranks #2 in Vision Arena scoring 1,305. Second only to Claude Fable 5 (High) which has only a 13pt lead.”
https://x.com/arena/status/2084108711665270942
FLUX 3 Video is here. Serious, fun, creative, real, cinematic, whatever you need it to be. Native audio, Text to Video, Image to Video with multiple frames, video continuation, dialogue in multiple languages. Comes with Draft mode so you can explore ideas fast at a fraction of”
https://x.com/bfl_ai/status/2084693191484469305
FLUX 3 by @bfl_ai is now available on fal. Up to 20s per generation with native audio, multilingual dialogue with strong lipsync, multi-scene shots, and video continuation that carries framing and scene logic forward.”
https://x.com/fal/status/2084694140986777622
GPT-Live is a new architecture and stack for realtime audio:”
https://x.com/gdb/status/2084405421041963356
MiniMax H3: An Open Model Breaking the Boundaries Between Tasks and Modalities – MiniMax Research | MiniMax
https://www.minimax.io/blog/minimax-h3
GPT-Live can listen while it speaks. To make that feel natural at ChatGPT scale, we rebuilt the voice stack from client to model. This new architecture keeps audio flowing continuously, so deeper reasoning and tool use don’t interrupt the conversation.”
https://x.com/OpenAI/status/2084378415818579975
When VLMs process medical images, do they recognize organs and broken bones? Using Silico, I trained a J-Lens and created a visualizer exploring what Qwen-3.5 27B sees in each patch of an image. I found that Qwen can identify things like this harmful cyst on an OCT-scan!”
https://x.com/michaelwhanna/status/2084675176315474268
Got sick of hand-tuning GPU kernels, so we built a compiler. Photon 2.0 compiles Moondream, Qwen 3.5, and Gemma 4 into megakernels: the entire forward pass in one GPU program.”
https://x.com/vikhyatk/status/2084409834523476073
1/ We’re entering the era of agentic commerce, and we believe that world models are the missing engine. Instead of browsing static product pages, agents will let you interact with products inside your own world before making decisions. Today, @DecartAI we’re releasing Anywear👇”
https://x.com/AbermanKfir/status/2084816814593478714
Holy, those insanae releases: MiniMax released a 33B video model that generates synchronized stereo audio and runs on one RTX 5090. H3 combines text, images, video and audio references for generation and editing, with clips up to 15 seconds. ComfyUI’s optimized stack is”
https://x.com/kimmonismus/status/2084229681012711598
VLM backbone or World Model? What’s the right kind of training data? Google DeepMind’s Kanishka Rao on how we might land on the recipe that solves robotics in the next 2-3 years.”
https://x.com/TheHumanoidHub/status/2083067365462528413
Must-read papers of the week ▪️ Wonder: Video World Model Done Better ▪️ DistillAlign: Coordinating Mode Covering and Mode Seeking in Autoregressive Video Distillation ▪️ Parallel Decoding Distillation for Fast Image and Video Generation ▪️ GPT-Red: Automated Red Teaming via”
https://x.com/TheTuringPost/status/2084450502503526618
This is really cool work building off our “Interpreting Physics in Video World Models” paper. People may not realize this yet, but unsupervised latent space simulators are a big deal.”
https://x.com/soniajoseph_/status/2084157222892806197
Useful world models need something different from just more video. New CG-World is a large computer-graphics-derived dataset and protocol that proposes a new approach to training data for world models. ▪️ Its idea is that pixels are observations generated by an underlying”
https://x.com/TheTuringPost/status/2083342704281583668
it’s the summer of World Models”
https://x.com/taiuti/status/2084286971774664922
Axolotl3D: a Unified Framework for Faithful 3D Shape Completion” TL;DR: a multimodal 3D completion model that combines images, visibility masks, camera parameters, and partial point clouds to faithfully reconstruct occluded geometry and maintain multi-view consistency.”
https://x.com/Almorgand/status/2083320823629181152
The Fast Gemma Challenge: our verified-SOTA recipe, in full
https://huggingface.co/blog/FINAL-Bench/fast-gemma
We introduce Maple-Preview, an open-source 20B-A1B ternary-weight reasoning LLM, SOTA in its weight class. It solves IMO-level problems and runs at 200+ tokens/s on a Mac Mini M4, 5-16× faster than efficient models like Gemma 4, Qwen3.5, and gpt-oss.
https://x.com/deepgrove_ai/status/2084727154928189783
How should a single GPU serve a policy to many robots? (📌 open-sourced & ready for π0.5 deployment) A new system from Georgia Tech robotics researchers for serving large vision-language-action models like π0.5 to fleets of 10+ robots from a single GPU or cloud/edge setup! How?”
https://x.com/IlirAliu_/status/2084186514968191157
Day-0 support for Mistral’s Shieldstral-1.0-3B on vLLM! 🛡️ Mistral’s new Shieldstral model is a 3B model serving edge deployments: 🧩 3B params on Ministral-3 base + native Pixtral vision encoder (text, image, text+image) 🎯 One forward pass → 0-1 safety score, threshold it”
https://x.com/vllm_project/status/2084765810883764673
Qwen3.8-Max is the best object detection VLM – satellite images – infrared images – documents – techical drawings – hand-sketched diagrams – crowded scenes – small objects ↓ check out some of those insane examples”
https://x.com/skalskip92/status/2084389468761362463
This is cool: Point your phone at a Japanese menu and dinner is handled. That’s the demo Collov Labs is leading with for the NewEyes launch today. One snap of the menu and it comes back with every dish translated, a generated photo of each one, allergens flagged, a”
https://x.com/kimmonismus/status/2084675007783829976
You shouldn’t need a vision model to know your PDF has checkboxes. LiteParse can now pull structured data directly from your PDFs: form field values, checkbox states, annotations, embedded images, vector graphics, tagged document structure, and word-level bounding boxes, all”
https://x.com/llama_index/status/2084265189772317162
The Call of Duty heartbeat sensor is real. Radio waves were built to carry information. Now AI is learning to read the physical world hidden inside their reflections. I trace the lineage of RF sensing from to the Army-funded Sense Through the Wall program and Biometrics at a”
https://x.com/bilawalsidhu/status/2083322840112382224
AI in robotics gets all the attention right now, but sometimes the most interesting work is very practical. Viet built a small vision system that counts potatoes on a conveyor belt. No giant dataset. No huge model. Just a clear problem and a smart setup. He used Ultralytics’”
https://x.com/IlirAliu_/status/2085063787921690646
[2608.05000] Towards Physics of Multimodal Pretraining: Knowledge Flow, Modality Synergy, Early Unification, and Recipes
https://arxiv.org/abs/2608.05000


Leave a Reply