Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for Moonshot for the week ending August 7, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
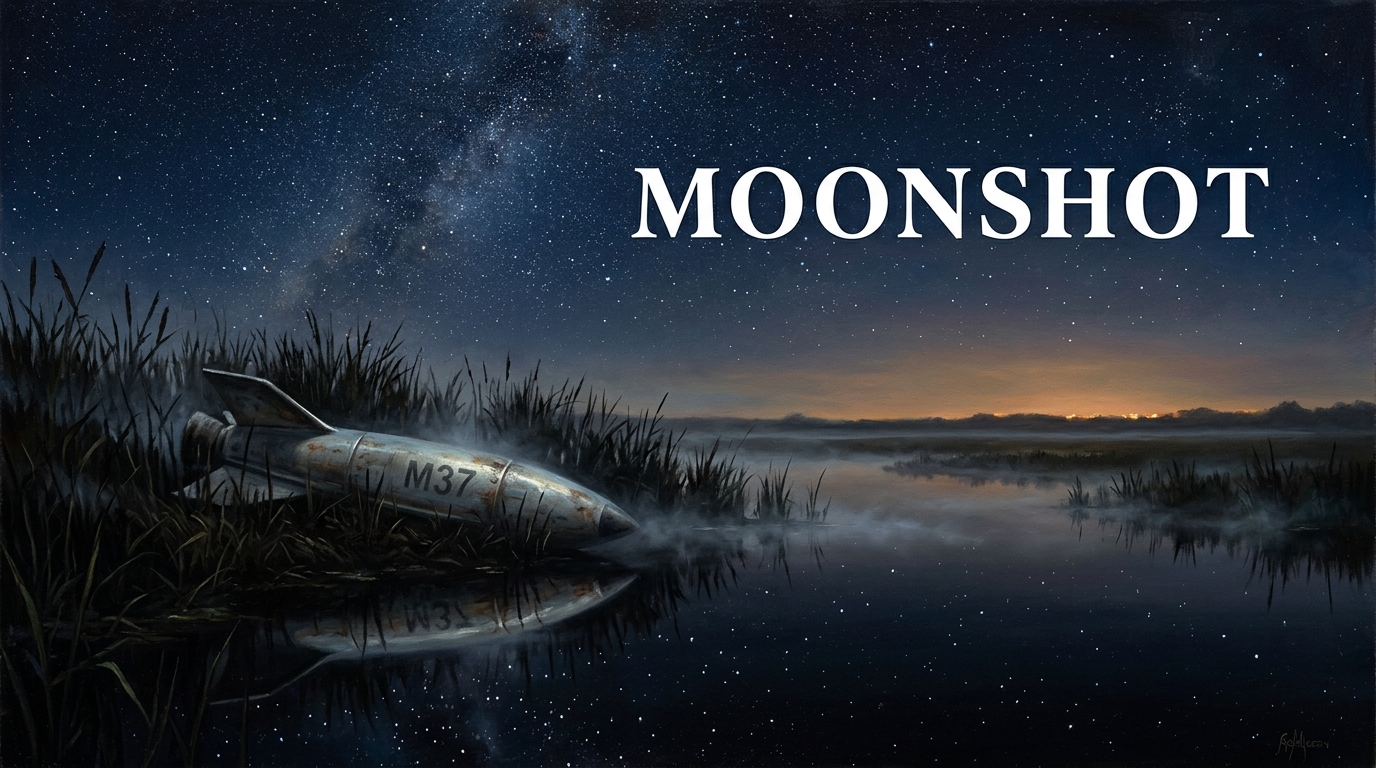
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Gemini 3.1 Flash Image Preview.
Category Cover Image Prompt: A small sleek retired rocket lying at rest among tall reeds at the edge of a mirror-still marsh at night, its silver hull faintly reflecting a dense field of stars that fills the wide indigo sky above and the dark water below, thin mist drifting over the water, low horizon with a single faint warm glow at the far edge, painterly nocturne in the style of American Tonalism and Luminism, bold clean title type reading Moonshot set into the upper night sky with generous negative space.
This Week in Moonshot News
Summary by Claude Sonnet 5.5 based on this week’s links:
- Kimi K3 is everywhere: Kimi K3 spread fast across infrastructure. vLLM, Databricks and Baseten announced hosting or serving support, and GitHub Copilot's rollout was paused briefly during a GitHub Actions incident. Sakana's Japanese-focused Namazu API is built on Kimi.
- Strong on benchmarks, not just popular: Epoch AI called K3 the strongest open-weights model available, with DeepSeek V4 Flash second. Arena put it at #2 on Frontend Code Arena behind Claude Opus 5. Together found a Kimi-first cascade with test-suite verification beat GPT-5.6 Sol alone at lower cost per completed task.
- Check the endpoint, not just the model: Results depend on who serves the model. A CEO-Bench tester said one Kimi K3 provider ranked #1 while another produced looping reasoning and early bankruptcy on every run. Artificial Analysis launched an index measuring how much accuracy each endpoint preserves.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to Moonshot
Muse Spark 1.2 just cracked the top 5 on the Vals Index, at just $0.69 per test. This is 3x cheaper than Kimi and 10x or more cheaper than Fable, Opus, and 5.6 Sol.”
https://x.com/ValsAI/status/2085191736683647055
We’ve been asked why Cline works better with open weights models like DeepSeek than other harnesses and want to share some detail (more in our blog below). Our internal evals show that many open weights models like DeepSeek, GLM, and Kimi are RL trained to spend more tokens”
https://x.com/cline/status/2084359007029141528
New RSIBench-Data (https://t.co/Y6KluCmH7s) result: Kimi K3 + Kimi Code achieves a 27.317% weighted score (aime,gpqa use 0.1, others 0.2) across six benchmarks, ranking #1 among the five model-harness combinations we tested. It scores 50% on SWE-bench Verified and 17% on”
https://x.com/FanqingMengAI/status/2084100049630601673
Baseten is now an official inference provider on @huggingface 🤗 Run Kimi K3, DeepSeek V4 Flash, and GLM-5.2 on Baseten straight from any model page, or with just your HF token in your favorite harness. Get started here:
https://x.com/baseten/status/2085380532263669903
📣 Kimi K3 is now available in GitHub Copilot for @code! Try Kimi Moonshot’s latest open-weight model for agentic coding, now hosted by @FireworksAI_HQ. 📖 Learn more:
https://x.com/code/status/2085424383212790099
🔁 Self-Evolving AI Has Three Layers. Only One Leads to True RSI Self-evolving AI is moving from theory into real engineering workflows. An early Kimi K3 checkpoint reportedly handled much of Moonshot AI’s kernel optimization work. Qwen3.8 recently spent around 16 days building a”
https://x.com/ZhihuFrontier/status/2084525505878073466
GLM-5.3 appears to be coming very soon. It’s time for OpenAI, and especially Anthropic, to step up their game and solidify their lead. China has recently made incredible strides with Kimi k3, Qwen 3.8, DeepSeek 4 Flash (fantastic!), and Minimax h3. The gap is shrinking. The US”
https://x.com/kimmonismus/status/2084240554225770535
Big news: Qwen3.8-Max by @Alibaba_Qwen just landed at #4 on the Frontend Code Arena leaderboard with a score of 1,668! With 1,668 points, Qwen3.8-Max is trailing only Claude Opus 5 (Max) with 1,705 pts and Kimi K3 (Max) with 1,676 pts, on par with Claude Opus 5 (High) with 1669″
https://x.com/arena/status/2084108703729615026
The top three spots in front-end design are now shared between two Chinese and one Western model. Moonshots Kimi, Alibaba’s Qwen, and Anthropic’s Claude. China is no longer lagging behind but competing on equal footing. Crazy.”
https://x.com/kimmonismus/status/2084215318990229972
Qwen 3.8 Max on my shader test. Basic impression after a bunch of experiments is that it is a solid model, but not Kimi K3 level in my experience so far.”
https://x.com/emollick/status/2084124237053219289
1/ Benchmarks should open-source more than tasks and scores: they should open-source trajectories that led to the scores as well, scores alone are deceptive. A good example is AutomationBench, recently used by @AnthropicAI and @Kimi_Moonshot model cards . I inspected several”
https://x.com/Shahules786/status/2084319792815829148
DeepSeek-V4-Flash-0731 debuts with an ECI of 153, comparable to GLM 5.2 and roughly midway between Opus 4.5 and Opus 4.6. It’s the second strongest open-weights model available today, behind only Kimi K3.”
https://x.com/EpochAIResearch/status/2084788991153586600
Announcing the Artificial Analysis Endpoint Accuracy Index, measuring how much of an open weights model’s accuracy each serverless API endpoint preserves. We are initiating coverage with GLM-5.2, gpt-oss-120b and DeepSeek V4 Pro, with Kimi K3 coming soon Providers trade off”
https://x.com/ArtificialAnlys/status/2084702191466725669
We analyzed Kimi K3 and GPT-5.6 Sol on DeepSWE. A Kimi-first cascade with test-suite verification outperformed Sol alone at a lower cost per completed task.”
https://x.com/togethercompute/status/2084730487235379338
While testing Kimi-K3 on CEO-Bench, we found that inference provider impacts results significantly. While @modal’s endpoint led to #1 on leaderboard, another inference provider produced loopy model reasonings and early bankruptcy on all runs. Always evaluate endpoint you use!”
https://x.com/tonychenxyz/status/2084242262188601650
Is memory the moat? | Wafer
https://www.wafer.ai/blog/kimi-k3-mi355x
Sakana Namazu is Sakana AI’s Japanese-focused LLM API. Blog post:
https://t.co/IHqsCgBjoZ Built on Kimi, it’s been fine-tuned on our own datasets for Japanese language, culture, and business contexts, with additional tuning to reduce unnecessary refusals and bias in outputs.”
https://x.com/SakanaAILabs/status/2084279329819963755
vLLM delivers fully verified, accurate, and performant Kimi K3: use @vllm_project to serve K3 on your own infrastructure.”
https://x.com/vllm_project/status/2085498546082722191
Kimi K3 at 239 tokens/s! Databricks is now #1 for Kimi K3 inference speed and latency on Artificial Analysis. A huge 2.8T parameters model, it’s the largest oss model we’ve ever served. We make sure the GPUs go brrr at Databricks.”
https://x.com/Yuchenj_UW/status/2084324515719651559
We have temporarily paused the roll-out of Kimi K3 while we mitigate an incident with GitHub Actions. We will resume the roll-out as soon as possible and update docs with Kimi K3 pricing, which will be $3 per 1M input tokens, $15 per 1M output tokens, and $0.30 per 1M cached”
https://x.com/github/status/2085468737000653159


Leave a Reply