Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for International for the week ending August 7, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Gemini 3.1 Flash Image Preview.
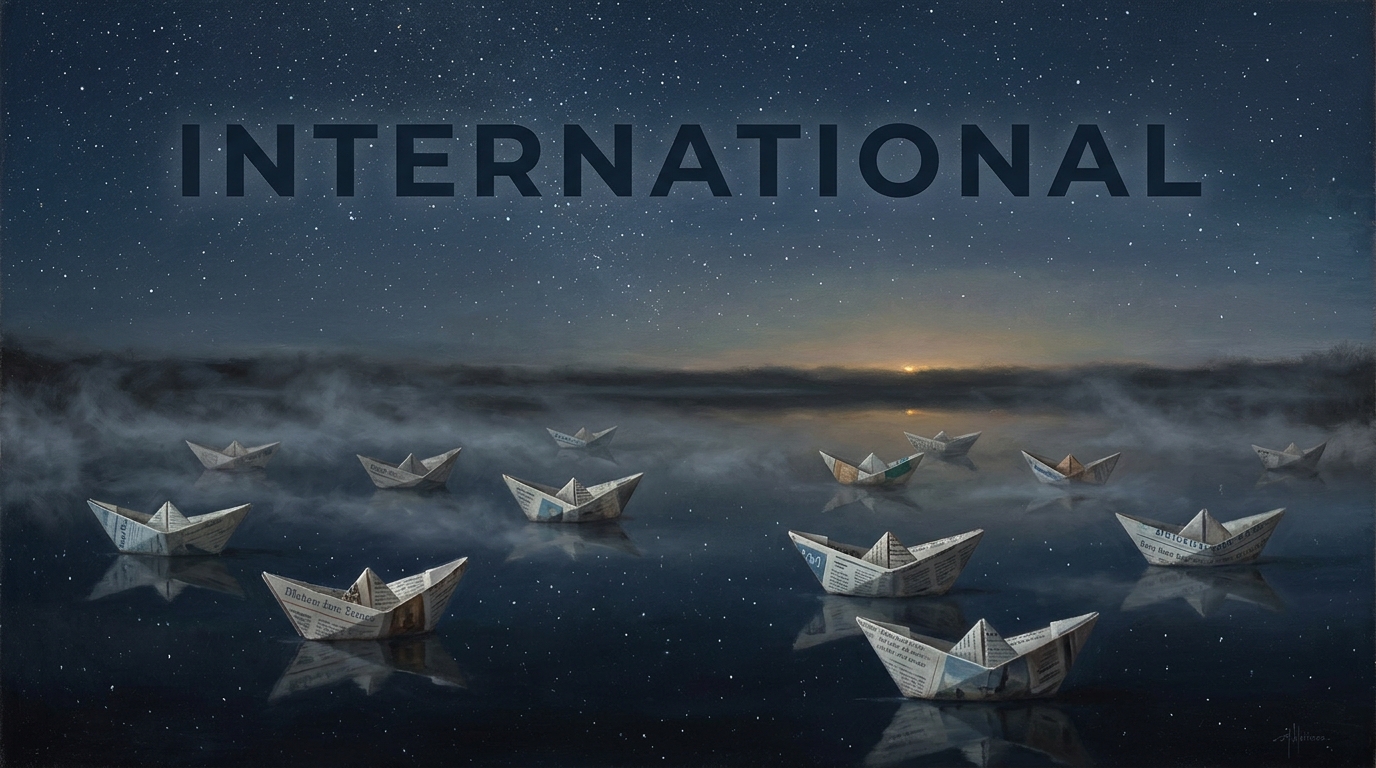
Category Cover Image Prompt: A fine-art nocturne of a dozen small folded paper boats made from different international newspapers, resting motionless on a mirror-still marsh pond that reflects a dense field of stars, thin mist curling across the water, muted indigo and slate palette with one faint warm glow at the distant horizon, low horizon and generous starry sky above, painterly realism in the style of American Tonalism and Luminism, the word INTERNATIONAL as bold clean title type set into the upper night sky.
This Week in International News
Summary by Claude Sonnet 5.5 based on this week’s links:
- Qwen3.8-Max lands strong: Alibaba's 2.4T-parameter model arrived with open weights promised for the following week, plus a 27B version. Vals put it at 66.1 on its Index, matching Claude Opus 4.7 at about 2.3x lower cost per test. Mollick found it solid on his shader test but not at Kimi K3's level.
- The gap-closing narrative: Commentators like Kimmonismus pointed to Chinese models taking top-three spots in front-end design on Arena, with Kimi K3 and Qwen3.8-Max beside Claude. Others pushed back: Jamin Ball argued the price gaps are smaller than people claim.
- DeepSeek V4 Flash is the cheap workhorse: Vals called it the cheapest model on its Index to score above 60, and Ollama said it is its fastest-growing model ever by token usage. At the same time, reports say DeepSeek plans significant API price increases.
- MiniMax H3 runs locally: The open video model topped Arena's video ranking among open models, and people ran it on a single RTX 5090 or a Mac. Its license, though, requires formal authorization for use in the US, EU, UK and South Korea.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to International
It’s becoming increasingly necessary for Anthropic to release Fable 5.5. Not only because OpenAI is putting immense pressure on them. But also because China is constantly improving, and Qwen 3.8 has even surpassed Fable 5 in Terminal Bench.”
https://x.com/kimmonismus/status/2084295475314729244
Muse Spark 1.2 just cracked the top 5 on the Vals Index, at just $0.69 per test. This is 3x cheaper than Kimi and 10x or more cheaper than Fable, Opus, and 5.6 Sol.”
https://x.com/ValsAI/status/2085191736683647055
Qwen3.8-Max ranks #2 in Vision Arena scoring 1,305. Second only to Claude Fable 5 (High) which has only a 13pt lead.”
https://x.com/arena/status/2084108711665270942
Seedance 2.5 is the Fable of video generation models. By far the priciest, but clearly the leader of the pack.”
https://x.com/bilawalsidhu/status/2083681664333476044
The UK’s @AISecurityInst (AISI) has published a report on their recent cybersecurity evaluation of Anthropic’s Claude Mythos 5 and OpenAI’s GPT-5.6 Sol. The models attempted to complete an assignment in a setup where their normal safeguards were removed and they were deliberately”
https://x.com/AnthropicAI/status/2084748111239344556
FLUX 3 Video is here. Serious, fun, creative, real, cinematic, whatever you need it to be. Native audio, Text to Video, Image to Video with multiple frames, video continuation, dialogue in multiple languages. Comes with Draft mode so you can explore ideas fast at a fraction of”
https://x.com/bfl_ai/status/2084693191484469305
MiniMax H3: An Open Model Breaking the Boundaries Between Tasks and Modalities – MiniMax Research | MiniMax
https://www.minimax.io/blog/minimax-h3
ByteDance Seed
https://seed.bytedance.com/en/SeedRealtime
ByteDance trains a 10-trillion-parameter AI model, aiming for global leadership. | KuCoin
https://www.kucoin.com/news/flash/bytedance-training-10-trillion-parameter-ai-model-aiming-for-global-leadership
ByteDance’s Founder Rules Out Distillation on AI Models … The Information
https://www.theinformation.com/articles/bytedances-founder-rules-distillation-ai-models
FLUX 3 Video, Part 1: Generation | Black Forest Labs
https://bfl.ai/blog/flux-3-video
Qwen 3.8 Max and a new local 27B Qwen 3.8 is coming! Thanks @Alibaba_Qwen for featuring Hermes Agent in the release video!”
https://x.com/Teknium/status/2084140512777560537
@Teknium Thanks! Looking forward to seeing Qwen3.8-Max on Hermes Agent!”
https://x.com/Alibaba_Qwen/status/2084230329553031299
Qwen 3.8-Max, the latest model from @Alibaba_Qwen, is now available in Hermes Agent at 20% off. > hermes update”
https://x.com/NousResearch/status/2084680562300862514
Qwen3.8-Max is available in Hermes Agent now! Let’s build! 🚀🚀”
https://x.com/Alibaba_Qwen/status/2084683919937634507
📢Meet Qwen3.8-Max … our most capable model to date. Next week, the open weights of Qwen3.8-Max will be released, and Qwen3.8-27B is also going open-weights to meet you all!🎉 Qwen3.8-Max, a new bar for coding and cowork at 2.4T parameters: – Autonomous coding: 10+ days of”
https://x.com/Alibaba_Qwen/status/2084100707423289643
Qwen3.8-Max is now available in ClinePass, a subscription for ~5x discounted access. Use it on Cline CLI w/ $4.99 special promo: npm i -g cline This is currently the most affordable way to access Qwen.”
https://x.com/cline/status/2084689818999718309
Incident Report: unsanctioned agent behaviour during cyber testing | AISI Work
https://www.aisi.gov.uk/blog/incident-report-unsanctioned-agent-behaviour-during-cyber-testing
We’ve been asked why Cline works better with open weights models like DeepSeek than other harnesses and want to share some detail (more in our blog below). Our internal evals show that many open weights models like DeepSeek, GLM, and Kimi are RL trained to spend more tokens”
https://x.com/cline/status/2084359007029141528
DeepSeek V4 Flash (0731) is the cheapest model on the Vals Index to score above 60, and 35x cheaper than the next best model. That efficiency comes almost entirely from coding. Three of its four strongest Index results are coding and agentic tasks, and the cost gap on those is”
https://x.com/ValsAI/status/2084451706650443916
(58) Agents at Scale: Inside MiniMax’s Model and the Infrastructure Behind It … Dan Fu and Olive Song – YouTube
https://www.youtube.com/watch?v=AVMr9PMINyo
New RSIBench-Data (https://t.co/Y6KluCmH7s) result: Kimi K3 + Kimi Code achieves a 27.317% weighted score (aime,gpqa use 0.1, others 0.2) across six benchmarks, ranking #1 among the five model-harness combinations we tested. It scores 50% on SWE-bench Verified and 17% on”
https://x.com/FanqingMengAI/status/2084100049630601673
Baseten is now an official inference provider on @huggingface 🤗 Run Kimi K3, DeepSeek V4 Flash, and GLM-5.2 on Baseten straight from any model page, or with just your HF token in your favorite harness. Get started here:
https://x.com/baseten/status/2085380532263669903
DeepSeek V4 Flash is now live on Together AI. Frontier agent performance is getting dramatically cheaper. DSV4 on Together AI brings a major jump in coding, tool use, and long-running agent performance.”
https://x.com/togethercompute/status/2084438456890019970
📣 Kimi K3 is now available in GitHub Copilot for @code! Try Kimi Moonshot’s latest open-weight model for agentic coding, now hosted by @FireworksAI_HQ. 📖 Learn more:
https://x.com/code/status/2085424383212790099
Try Qwen3.8-Max on Hermes Agent and you will have to doubt on how much these open frontier models have caught up with frontier closed models. These new open models are insanely good.”
https://x.com/omarsar0/status/2084314695343731026
🔁 Self-Evolving AI Has Three Layers. Only One Leads to True RSI Self-evolving AI is moving from theory into real engineering workflows. An early Kimi K3 checkpoint reportedly handled much of Moonshot AI’s kernel optimization work. Qwen3.8 recently spent around 16 days building a”
https://x.com/ZhihuFrontier/status/2084525505878073466
When VLMs process medical images, do they recognize organs and broken bones? Using Silico, I trained a J-Lens and created a visualizer exploring what Qwen-3.5 27B sees in each patch of an image. I found that Qwen can identify things like this harmful cyst on an OCT-scan!”
https://x.com/michaelwhanna/status/2084675176315474268
GLM-5.3 appears to be coming very soon. It’s time for OpenAI, and especially Anthropic, to step up their game and solidify their lead. China has recently made incredible strides with Kimi k3, Qwen 3.8, DeepSeek 4 Flash (fantastic!), and Minimax h3. The gap is shrinking. The US”
https://x.com/kimmonismus/status/2084240554225770535
Big news: Qwen3.8-Max by @Alibaba_Qwen just landed at #4 on the Frontend Code Arena leaderboard with a score of 1,668! With 1,668 points, Qwen3.8-Max is trailing only Claude Opus 5 (Max) with 1,705 pts and Kimi K3 (Max) with 1,676 pts, on par with Claude Opus 5 (High) with 1669″
https://x.com/arena/status/2084108703729615026
The top three spots in front-end design are now shared between two Chinese and one Western model. Moonshots Kimi, Alibaba’s Qwen, and Anthropic’s Claude. China is no longer lagging behind but competing on equal footing. Crazy.”
https://x.com/kimmonismus/status/2084215318990229972
On SWE-bench it scored 87.3%, ahead of GPT-5.5 (82.6%) and GLM-5.2 (83.3%) and just behind Claude Opus 4.8 (89.2%). On Terminal-Bench 2.1 it scored 67.4, up from 61.0 for 3.7 Max. Note: Alibaba’s reported results modify the Terminal Bench 2.1 timeouts, whereas our results”
https://x.com/ValsAI/status/2084364167751065996
It has a 1M token context window and 128k max output tokens. We ran it at 0.7 temperature with default Top P and Top K. Qwen 3.8 Max matches Claude Opus 4.7 on the Index (66.1 to 66.1) at about 2.3x lower cost per test: $2.68 versus $6.17.”
https://x.com/ValsAI/status/2084364170242519545
The leaps in capabilities are literally insane. Open Source Opus 4.8, according to DeepSWE Benchmark. The jump to Qwen 3.7 is simply insane.”
https://x.com/kimmonismus/status/2084319130845315096
I found the original chart hard to grok, so here is a new representation I have not seen before. All highlighted cells (light red) are where the model got beat by Qwen 3.8-Max. Looks like Opus 4.8 is mostly subsumed by 3.8-Max.”
https://x.com/deliprao/status/2084133369391022587
Three neat pieces to this – Qwen 3.8 Max is SoTA on image recognition and labeling – Qwen 3.8 Max is likely really sample efficient – Qwen 3.8 Max can be perfectly OPD’d into Qwen 3.8 27B to achieve parity on specific tasks We can have Maven on a laptop… in the aggregate”
https://x.com/teortaxesTex/status/2084434943514443915
More exciting news from @Alibaba_Qwen: Qwen-Image-3.0-Pro has entered the Text-to-Image Arena at #5 with 1,263 pts! This is a strong improvement over Qwen-Image-2.0-Pro with 1,191 pts (#15 -> #5). Performance by category also improved substantially (see post below). Congrats”
https://x.com/arena/status/2084672571807846418
Qwen-Image-3.0-Pro has made a massive leap from the previous generation, now ranking #5 globally. Appreciate the recognition! We will keep building.🚀”
https://x.com/Alibaba_Qwen/status/2084674586462007458
Qwen 3.8 Max ranks #2 among open weight models on the Vals Index, scoring 66.1 and placing #10 of 43 overall.”
https://x.com/ValsAI/status/2084364164655694236
The jump from its predecessor is steep. Qwen 3.7 Max scored 57.5, so 3.8 Max gained 8.6 points in about 2.5 months. It got cheaper doing it: $2.00/$6.00 per million tokens, down from $2.50/$7.50.”
https://x.com/ValsAI/status/2084364166362767808
New open weight model is out – Qwen 3.8 Max. Here’s how the “vanilla” pricing compares between the 3 recent open weight models and some frontier models. The delta is not nearly as stark as many people are making it seem. On top of that, the “vanilla” prices don’t take into”
https://x.com/jaminball/status/2084264107633729614
Qwen Team Exodus: 3 Key Leaders Leave Alibaba (2026)
https://modelfit.io/blog/qwen-team-exodus-alibaba/
Got sick of hand-tuning GPU kernels, so we built a compiler. Photon 2.0 compiles Moondream, Qwen 3.5, and Gemma 4 into megakernels: the entire forward pass in one GPU program.”
https://x.com/vikhyatk/status/2084409834523476073
Qwen-Image-3.0-Pro – QwenCloud
https://www.qwencloud.com/models/qwen-image-3.0-pro
Qwen 3.8 Max on my shader test. Basic impression after a bunch of experiments is that it is a solid model, but not Kimi K3 level in my experience so far.”
https://x.com/emollick/status/2084124237053219289
🚀 Alibaba Is Taking Qwen3.8-Max Open-Weight Alibaba launched Qwen3.8-Max today with 2.4T total parameters, 95B active parameters and a one-million-token context window. It also says the Max weights and Qwen3.8-27B will be released next week. Zhihu contributor AI解码师 sees this”
https://x.com/ZhihuFrontier/status/2084230028007764415
Ask anything, anonymously. Qwen3.8-Max has landed on Venice. Give it a try!”
https://x.com/Alibaba_Qwen/status/2084280439909589230
Live in Command Code!🎉”
https://x.com/Alibaba_Qwen/status/2084210646737100983
Qwen
https://qwen.ai/blog?id=qwen3.8
Qwen3.8-Max, better and cheaper. Try it out. 👀”
https://x.com/Alibaba_Qwen/status/2084552484648042776
1/ Benchmarks should open-source more than tasks and scores: they should open-source trajectories that led to the scores as well, scores alone are deceptive. A good example is AutomationBench, recently used by @AnthropicAI and @Kimi_Moonshot model cards . I inspected several”
https://x.com/Shahules786/status/2084319792815829148
DeepSeek-V4-Flash-0731 debuts with an ECI of 153, comparable to GLM 5.2 and roughly midway between Opus 4.5 and Opus 4.6. It’s the second strongest open-weights model available today, behind only Kimi K3.”
https://x.com/EpochAIResearch/status/2084788991153586600
Holy, those insanae releases: MiniMax released a 33B video model that generates synchronized stereo audio and runs on one RTX 5090. H3 combines text, images, video and audio references for generation and editing, with clips up to 15 seconds. ComfyUI’s optimized stack is”
https://x.com/kimmonismus/status/2084229681012711598
MiniMax H3 open weights are out, with the nodes already in ComfyUI. One Blender blockout, run against Seedance 2.0 at a fraction of the cost per generation, leaving more room for experimentation and iteration. To try this workflow, link below 👇”
https://x.com/ComfyUI/status/2084387277254644162
Maestro v1.5.5 with MiniMax H3 is out! 🩵 The community got H3 running on hardware we never tested – from a gaming GPU to MacBooks running fully offline – and built tooling we didn’t plan for within 48 hours. We’re genuinely glad we opened it up. <3″
https://x.com/MiniMax_AI/status/2084745241589080491
Announcing the Artificial Analysis Endpoint Accuracy Index, measuring how much of an open weights model’s accuracy each serverless API endpoint preserves. We are initiating coverage with GLM-5.2, gpt-oss-120b and DeepSeek V4 Pro, with Kimi K3 coming soon Providers trade off”
https://x.com/ArtificialAnlys/status/2084702191466725669
Deepseek v4 Flash 0731 (high) and (max) score 57.1% and 63.0% on WeirdML, setting the new cost/accracy SOTA ahead of GPT 5.6 Luna (even after the recent cost reduction). The model is probably significantly stronger than this result indicates, since it often use the submissions”
https://x.com/htihle/status/2084246773413957957
Big news: MiniMax-H3 by @MiniMax_AI is now the #1 open model in Video Arena: across both Text-to-Video and Image-to-Video. This is +280pts over the next best open model, hunyuan-video-1.5, and a huge improvement from Hailuo-2.3 at #27 (1199 pts) and Hailuo-02-pro at #28 (1197″
https://x.com/arena/status/2084408459991421319
This is how much you can do with a single RTX 5090 NOW with MiniMax H3. WE HAVE CROSSED A LINE.✊”
https://x.com/MiniMax_AI/status/2084387967981011326
The MiniMax-H3 video generation model is a lot of fun – here’s what I got on my M5 Pro Mac for the prompt “a rainbow colored skunk leaps over a mossy log in a supermarket” (~115GB model download, took around 45 minutes to generate)”
https://x.com/simonw/status/2084719238569435469
I joined @BloombergTV’s The China Show yesterday to talk through our data on the latest AI models from leading American and Chinese labs with @DavidInglesTV and @avrilhongTV. Some of the topics we covered: – Across the entire near-3-year history of the Artificial Analysis”
https://x.com/_micah_h/status/2084401434746036403
We analyzed Kimi K3 and GPT-5.6 Sol on DeepSWE. A Kimi-first cascade with test-suite verification outperformed Sol alone at a lower cost per completed task.”
https://x.com/togethercompute/status/2084730487235379338
While testing Kimi-K3 on CEO-Bench, we found that inference provider impacts results significantly. While @modal’s endpoint led to #1 on leaderboard, another inference provider produced loopy model reasonings and early bankruptcy on all runs. Always evaluate endpoint you use!”
https://x.com/tonychenxyz/status/2084242262188601650
China’s MiniMax H3 is the first open model to top an AI video ranking
https://the-decoder.com/chinas-minimax-h3-is-the-first-open-model-to-top-an-ai-video-ranking/
MiniMax H3 is now the SOTA open video generation model in both @arena and @ArtificialAnlys benchmarks.”
https://x.com/MiniMax_AI/status/2084410437618352386
H3 can be licensed for deployment in the US, EU, UK, and South Korea through MiniMax’s formal authorization process. Apply by emailing api@minimax.io with the subject “MiniMax H3 licensing – authorization request.” The standard community license does not grant that authorization”
https://x.com/VictorSuOrtiz/status/2084410948358705273
DeepSeek’s Price Increase Goes Beyond GPU Costs | Chuanxilu for Skilled Homo sapiens
https://blog.chuanxilu.net/en/posts/2026/08/deepseek-price-increase-beyond-gpu/
DeepSeek Plans Significant API Price Increases · TechNode
https://technode.com/2026/08/06/deepseek-plans-significant-api-price-increases/
American companies should not be selling data to Chinese AI labs. @scale_AI doesn’t do this work, and we have turned down revenue because of it. The companies that do are undermining American AI leadership and risking national security.”
https://x.com/aakashsabharwal/status/2085109708885782998
Is memory the moat? | Wafer
https://www.wafer.ai/blog/kimi-k3-mi355x
deepseek-ai/DeepSeek-V4-Flash-0731 · Hugging Face
https://huggingface.co/deepseek-ai/DeepSeek-V4-Flash-0731
DeepSeek-V4-Flash can now run 2× faster locally with DSpark! ⚡️ DSpark enables V4-Flash-0731 GGUFs to generate ~1.4-2× faster with no accuracy change. DeepSeek-V4-Flash-0731 can reach at 120 tokens/s. GGUFs:
https://t.co/ac6uOI8mZA Guide:
https://x.com/UnslothAI/status/2085368138393329703
DeepSeek-V4-Flash-0731 is Ollama’s fastest growing model ever in token usage. We are scaling capacity in US & Europe. On Ollama, this model runs with high performance (100tps+) and zero data retention. Your data stays yours. ollama run deepseek-v4-flash:0731-cloud”
https://x.com/ollama/status/2084771801888907621
api-docs.deepseek.com
https://api-docs.deepseek.com/quick_start/pricing/
At first I thought Bloomberg forgot to add DeepSeek’s pricing to the chart.”
https://x.com/AndrewCurran_/status/2084509003384827970
despite record breaking numbers yesterdays total deepseek flash token worth is $120,000 on OpenCode inference ~ $20,000 (estimate) on OpenRouter this is nothing and it’s TOTAL traffic from everyone worldwide puts into perspective how cheap this thing is”
https://x.com/thdxr/status/2085375014392541315
This graph shows the absurd dominance in pricing of deepseek 4 flash. Its not even close. Not even a tiny bit.”
https://x.com/kimmonismus/status/2084623032014848505
Day-0 support for Mistral’s Shieldstral-1.0-3B on vLLM! 🛡️ Mistral’s new Shieldstral model is a 3B model serving edge deployments: 🧩 3B params on Ministral-3 base + native Pixtral vision encoder (text, image, text+image) 🎯 One forward pass → 0-1 safety score, threshold it”
https://x.com/vllm_project/status/2084765810883764673
AI labels to be compulsory on authentic-looking content under EU rules | AI (artificial intelligence) | The Guardian
https://www.theguardian.com/technology/2026/jul/31/ai-labels-to-be-compulsory-on-authentic-looking-content-under-eu-rules
🛡️Introducing Shieldstral, Mistral’s 3B open-weights model for content safety that can be deployed on-device 🧵
https://x.com/MistralAI/status/2084684735725379637
Sakana Namazu is Sakana AI’s Japanese-focused LLM API. Blog post:
https://t.co/IHqsCgBjoZ Built on Kimi, it’s been fine-tuned on our own datasets for Japanese language, culture, and business contexts, with additional tuning to reduce unnecessary refusals and bias in outputs.”
https://x.com/SakanaAILabs/status/2084279329819963755
Hugging Face CEO says China is winning the AI race and dominating on open models”
https://x.com/CNBC/status/2084306865723220143
Qwen3.8-Max is the best object detection VLM – satellite images – infrared images – documents – techical drawings – hand-sketched diagrams – crowded scenes – small objects ↓ check out some of those insane examples”
https://x.com/skalskip92/status/2084389468761362463
This is cool: Point your phone at a Japanese menu and dinner is handled. That’s the demo Collov Labs is leading with for the NewEyes launch today. One snap of the menu and it comes back with every dish translated, a generated photo of each one, allergens flagged, a”
https://x.com/kimmonismus/status/2084675007783829976
I think the combined research capability of Chinese AI companies currently exceeds that of American AI companies. Distillation, jaggedness and fast-following reduce the prior, but the compute/spend/headcount differentials are too massive. They “should” be further behind.”
https://x.com/teortaxesTex/status/2084370832030052562
It’s surprisingly difficult to acquire a hereditary peerage in the UK. Like you can’t even take one by force any more, and they just get mad at you if you try.”
https://x.com/AmandaAskell/status/2084519165021528263
Mind Lab puts continual learning to the test with Macaron-V1
https://kr-asia.com/mind-lab-puts-continual-learning-to-the-test-with-macaron-v1
Remember when China was 2 years behind?”
https://x.com/matvelloso/status/2084289424314241046
Um.. If I am reading this license right, the license forbids usage in the USA, EU, UK, and Korea. We are not even allowed to download the model in the USA, at least that is how I am reading the license.”
https://x.com/ostrisai/status/2084110556374659476
vLLM delivers fully verified, accurate, and performant Kimi K3: use @vllm_project to serve K3 on your own infrastructure.”
https://x.com/vllm_project/status/2085498546082722191
Having so much fun with MinMax-H3. Cannot believe we now have this video quality 100% locally 🚀”
https://x.com/victormustar/status/2084322394479464781
Introducing Shieldstral. | Mistral AI
https://mistral.ai/news/shieldstral/
Kimi K3 at 239 tokens/s! Databricks is now #1 for Kimi K3 inference speed and latency on Artificial Analysis. A huge 2.8T parameters model, it’s the largest oss model we’ve ever served. We make sure the GPUs go brrr at Databricks.”
https://x.com/Yuchenj_UW/status/2084324515719651559
We have temporarily paused the roll-out of Kimi K3 while we mitigate an incident with GitHub Actions. We will resume the roll-out as soon as possible and update docs with Kimi K3 pricing, which will be $3 per 1M input tokens, $15 per 1M output tokens, and $0.30 per 1M cached”
https://x.com/github/status/2085468737000653159
And next week they will also release Qwen3.8-27b, also open-weights. I am super ready for that release!”
https://x.com/kimmonismus/status/2084209750477029447
Xiaomi Open-Sources Embodied AI Foundation Model Xiaomi-Robotics-1
https://insideai.news/news/robotics/xiaomi-open-sources-embodied-ai-foundation-model-xiaomi-robotics-1/7082/
If you are an EE/MechE with strong robotics background located near Münster or AIE anywhere within 🇩🇪 who wants to build general purpose robots for every home and factory… Talk to @neurosp1ke!”
https://x.com/IlirAliu_/status/2083564230393876781
Introducing Sakana Namazu: An LLM API with Japanese-vibes! Today we’re rolling out an upgraded version of our LLM, Namazu, now available as an API. Try Sakana Namazu API:
https://t.co/4EatcdUW9N 🐟”
https://x.com/SakanaAILabs/status/2084276852143919470
Qwen3.8-Max can be prompted with positive and negative boxes and use them to generate new detections super useful when concept we are looking for is difficult to describe with text 60% mAP when prompted with single box 80% mAP when prompted with multiple box ↓ more examples”
https://x.com/skalskip92/status/2084684945251844129
Yes, we will have Qwen3.8-Max.”
https://x.com/baseten/status/2084250438509969894


Leave a Reply