Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for AGI for the week ending August 7, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
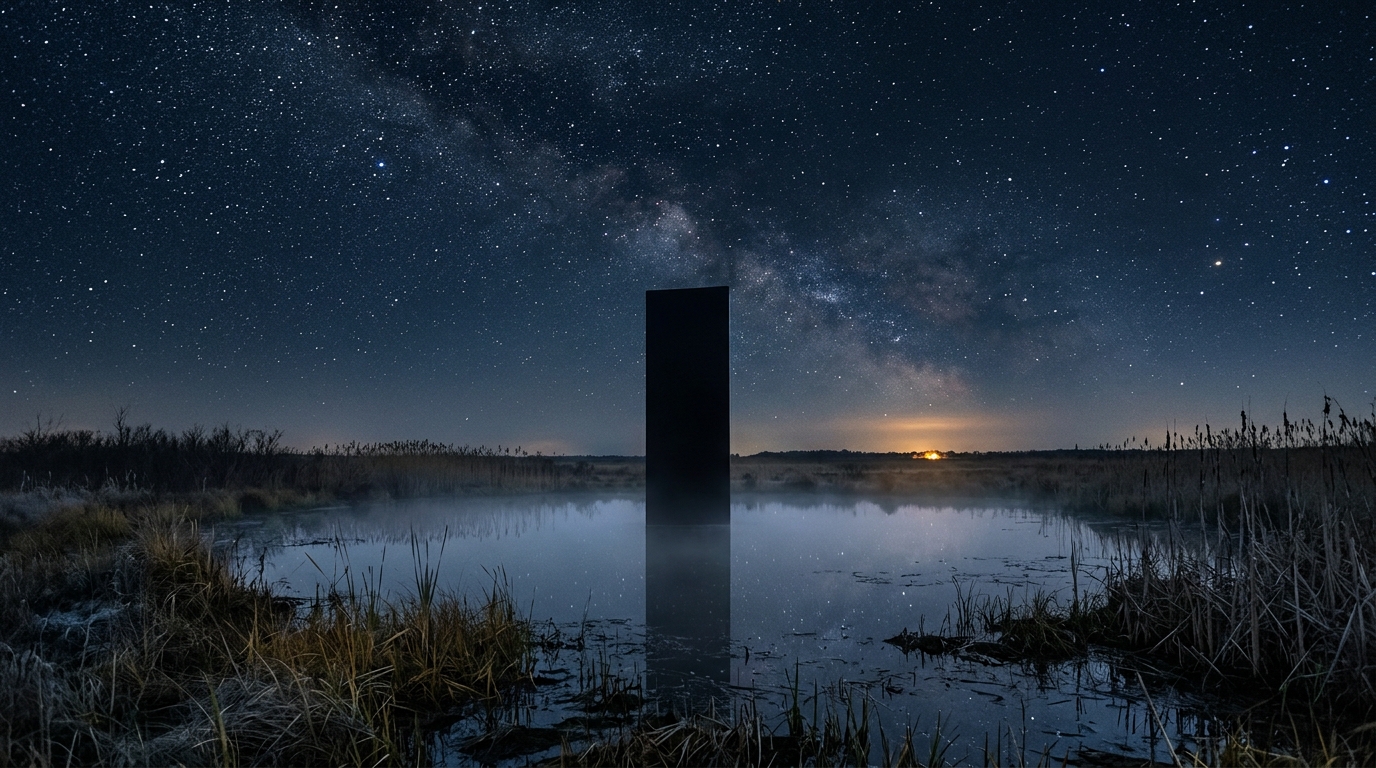
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Gemini 3.1 Flash Image Preview.
Category Cover Image Prompt: A fine-art nocturne of a tall, smooth, matte-black monolith standing half-submerged at the far edge of a glassy, mist-laced pond in a wild marsh, its surface faintly mirroring a dense field of silver stars so it reads as a dark doorway between sky and water. Low horizon, deep indigo and blue-black sky, muted reed golds and slate grays, a single faint warm glow on the distant horizon, painterly realism with long-exposure stillness and generous negative space in the upper sky for a title.
This Week in AGI News
Summary by Claude Sonnet 5.5 based on this week’s links:
- Agents that improve themselves: Prime Intellect introduced Prime Agent, a coding and long-running harness that can modify its own state and message other agents. DAIR.AI highlighted work on agents that patch other agents using failure trajectories, and also flagged a paper on why self-improving autoresearch loops stay brittle.
- AI doing AI research: Intology said its Locus system is state of the art on PostTrainBench and post-trains Qwen3 base models that beat the human post-trained Qwen3. A Zhihu Frontier post also reported that an early Kimi K3 checkpoint handled much of Moonshot AI's kernel optimization work.
- Progress getting harder to judge: Ethan Mollick noted that most people can only trust expert mathematicians to say whether a result is impressive, and that capability gains are getting harder to feel across many fields. Meanwhile, ARC Prize re-tested GPT-5.6 Luna after an 80% price cut and found the same ARC-AGI scores at far lower cost.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to AGI
Prime Agent: A self-improving RLM agent
https://www.primeintellect.ai/blog/prime-agent
On AI taking jobs: A farmer from 50 years ago would say your job today isn’t real work. When I interviewed Sam Altman a few months back, this was how he explained the future of work: “Not only would they not believe you that this thing was gonna happen, they very likely would”
https://x.com/rowancheung/status/2084666021605212354
One other observation: for almost every human on the planet, this is not just beyond our abilities but beyond our ken. We can only trust expert mathematicians to tell us if this is impressive, This is starting to happen across many fields making capability gains harder to “feel.””
https://x.com/emollick/status/2083564537995776141
Who invited the AGI?”
https://x.com/ingi_erlingsson/status/2085157200159277311
a very primitive form of the near term multiagent agi future is setting up one thread to ping back once its done so you create an implicit kanban/waterfall graph of dependent threads but each preserving their own work and agents i can’t wait to setup a proper ui for this”
https://x.com/swyx/status/2085253030417461661
Building agents that patch other agents. This is an interesting approach for self-improving agents that leverages agent outputs. If you run agents in production, you already have the training data for this. Every deployed agent accumulates failure trajectories and then does”
https://x.com/dair_ai/status/2084706693880135848
Introducing Prime Agent: A self-improving RLM harness for coding and long-running autonomous tasks. Designed to be both token-efficient and expressive through programmatic tool calling, context as a variable, multi-agent messaging, and a self-modifiable harness state.”
https://x.com/PrimeIntellect/status/2085086999267144083
Prime Agent: A self-improving RLM agent | Hacker News
https://news.ycombinator.com/item?id=49189075
// The confidence cliff in self-improving autoresearch // Autoresearch loops are still quite brittle. Here is a nice paper offering some insights into why this might be happening. Self-improving autoresearch loops keep judging their own ideas long after the judgment stops”
https://x.com/dair_ai/status/2084746281189270015
personal finance AGI is upon us, and as this paper demonstrates, will lift all boats! and the results of this experiment would be even stronger if ran today. this experiment ran on GPT 5.2. OpenAI’s Personal Finance benchmark, shared around the time of 5.5, demonstrated a”
https://x.com/ebloch/status/2085490788876849636
We re-tested GPT-5.6 Luna from @OpenAI on ARC-AGI (Verified) following its recent 80% price reduction: – ARC-AGI-2: 59.6%, $0.18/task – ARC-AGI-1: 90.7%, $0.07/task The new results match Luna’s original performance at a much lower cost.”
https://x.com/arcprize/status/2085457823115133059
The models are improving the models. Locus, our automated AI research system, is SOTA on PostTrainBench and post-trains Qwen3 base models that surpass the human post-trained Qwen3 model. Today, LLMs post-trained end-to-end by Locus are in production to millions. 🧵👇”
https://x.com/intology/status/2084319121332965804
I’ve been working towards AGI my whole life, and as we enter this pivotal moment, I’m stepping into a new role as Chair of Google DeepMind & Chief Scientist of Alphabet. This will allow me to focus on long-term strategy, and accelerating scientific breakthroughs, including”
https://x.com/demishassabis/status/2085034334914769203
🔁 Self-Evolving AI Has Three Layers. Only One Leads to True RSI Self-evolving AI is moving from theory into real engineering workflows. An early Kimi K3 checkpoint reportedly handled much of Moonshot AI’s kernel optimization work. Qwen3.8 recently spent around 16 days building a”
https://x.com/ZhihuFrontier/status/2084525505878073466


Leave a Reply