Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for Qwen for the week ending August 28, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
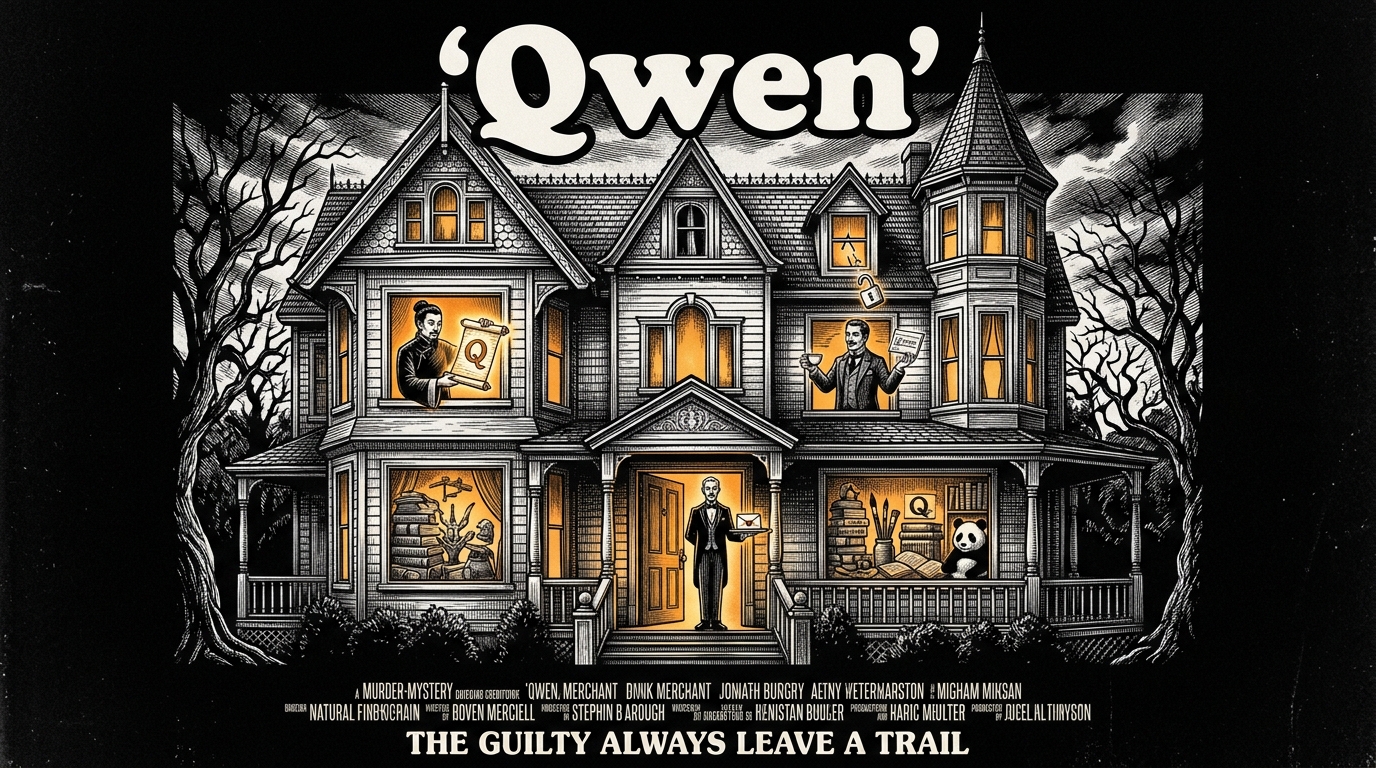
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Nano Banana 2.1.
Category Cover Image Prompt: A 16:9 mid-1980s murder-mystery movie poster of a broad three-story Victorian mansion rendered in high-contrast black-and-white pen-and-ink engraving on pure black, with the fat rounded white title 'Qwen' set above the roofline like a movie title; warm amber windows reveal costumed suspects in theatrical poses, a scholar in Tang-inspired evening wear holding a glowing scroll stamped with a stylized Q, a dapper merchant with a tea cup and an open-source license, still-life windows crowded with stacked model checkpoints, calligraphy brushes, multilingual dictionaries and a panda silhouette, and one window with a small open padlock caught mid-fall. In the open front door stands the same slim upright silver-haired butler in his sixties with a pencil mustache, black tailcoat and white gloves, holding a silver tray with a single envelope sealed with a wax brush-stroke Q, campy spooky theatrical lighting, crisp engraved linework.
This Week in Qwen News
Summary by Claude Sonnet 5.5 based on this week’s links:
- 27B holds its own: Arena reported Qwen3.8-27B at #9 in Code Arena WebDev, the only model of its size in the top 10 and six ranks behind Qwen3.8-Max. Carnice-V3-27b, an open fine-tune built on it, is pitched as fitting on a 3090-class GPU.
- New Flash Next release: Qwen 3.8 Flash Next arrived the same day as GLM 5.3 Flash, and Jeff Boudier of Hugging Face noted both can be deployed on-prem on Dell hardware. A Next Web headline says its architecture previews Qwen4, using 6B of 125B parameters per token.
- The cost of running agents: Benjamin Marie logged DeepSWE runs on Qwen3.8 27B with mini-swe-agent: about 919M input tokens across 10,580 agent turns, and 58% of output tokens went to reasoning.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to Qwen
Welcome 🚀Carnice-V3-27b! 🚀 → Carnice is a 27 billion parameter model capable of beating models 10x the size in Hermes-agent, fully open-source and built on top of Qwen3.8-27B →Build to fit on Consumer GPU on a 3090+ to run locally🔥 →A full merged BF16 Qwen3.8-27B”
https://x.com/kaiostephens/status/2091710751509475543
Some stats for my DeepSWE runs on Qwen3.8 27B, medium thinking and mini-swe-agent: 918.9M input tokens 8.0M output tokens 926.9M total tokens 10,580 completed agent turns 4.64M reasoning tokens, 58.1% of all output tokens That 919M input token number looks pretty scary at first”
https://x.com/bnjmn_marie/status/2091728410359853275
The fun doesn’t stop: apparently there is also a new Qwen model – Qwen 4 – already being tested. So now we got: – New Claude models (probably Opus 5.1 and Haiku) – Ox Alpha (possibly GLM-5.3 Flash) – Qwen 4 (?) Already being tested and / or spotted. + GPT Astra confirmed.”
https://x.com/kimmonismus/status/2091882849863451042
Exciting news: Qwen3.8-27B by @Alibaba_Qwen just landed in Code Arena: WebDev at #9 overall with 1595 pts. It is the only model in its size class in the top 10, and also reshapes the Pareto Frontier! It is only 6 ranks behind the much larger Qwen3.8-Max. For scale: Gemma 4-31B”
https://x.com/arena/status/2091920512796725272
2026 Chinese model landscape in one list ▪️ Qwen3.8-27B, Qwen3.8-Max ▪️ GLM-5.3 ▪️ Kimi K3 ▪️ DeepSeek-V4 ▪️ ERNIE 5.1 ▪️ Baichuan-M3-235B, Baichuan-Omni-1.5 ▪️ Yi 1.5 ▪️ MiniCPM-o 4.5, MiniCPM-V 4.5, MiniCPM-V 4.6 They’re getting interesting in very different ways. Here we”
https://x.com/TheTuringPost/status/2091665921849098363
UC Berkeley open-sourced FreeToken. Wild results: A single RTX PRO 6000 runs the 753B GLM-5.2 at 14.9 tok/s! An 8GB RTX 4060 laptop (~$1,000) runs Qwen3.6-35B at 39.3 tok/s! FreeToken is 2-4x faster than Ollama across consumer GPUs. Local AI inference is getting very real.”
https://x.com/Yuchenj_UW/status/2090857982385066474
💥💥 2 banger open model drops today – (al)ready to deploy on-prem on @Dell > Qwen 3.8 Flash Next from @Alibaba_Qwen > GLM 5.3 Flash from @Zai_org You can host the frontier, you can build your own AI. Congrats team on the release! @ehcalabres @balaatdell”
https://x.com/jeffboudier/status/2092713057026007488
Qwen
https://qwen.ai/blog?id=qwen3.8-flash-next
Qwen4’s architecture is here early, firing 6B parameters out of 125B
https://thenextweb.com/news/qwen38-flash-next-qwen4-architecture-open-licence-ai-act
same day new qwen and new glm drop life feels good in open source”
https://x.com/remi_or_/status/2092632359841792124
Qwen-Video-Edit: Instruction-Based Video Editing by Repurposing an Image Editing Model” TL;DR: repurposes Qwen-Image-Edit for video by editing Wan 2.1 video-VAE latents directly, using lightweight projections instead of a video-pretrained transformer.”
https://x.com/Almorgand/status/2091925153588326411




Leave a Reply