Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for Locally Run for the week ending August 28, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Nano Banana 2.1.
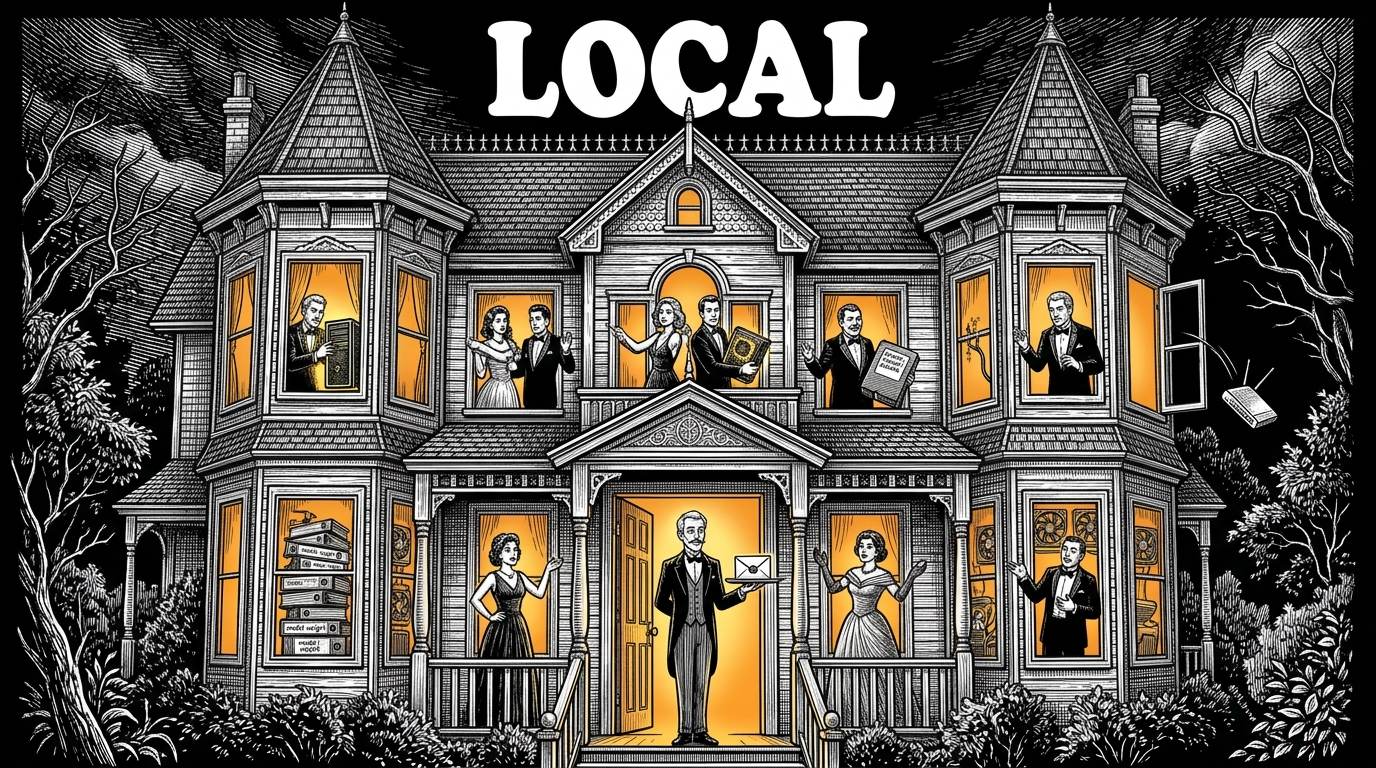
Category Cover Image Prompt: A 16:9 mid-1980s murder-mystery comedy movie poster of a wide three-story Victorian mansion in stark black-and-white pen-and-ink engraving on pure black, titled 'Local' in fat rounded extra-heavy white sans-serif letters above the roofline; warm amber windows reveal costumed suspects in evening wear posing with a glowing desktop GPU tower, a hand-labeled external hard drive, and a severed ethernet cable, plus still-life windows crowded with stacked model weight binders, cooling fans, and a lone unplugged router falling mid-air. At the open center door stands the same slim upright silver-haired butler in his sixties with pencil mustache, raised eyebrow, black tailcoat, gray waistcoat, white gloves, holding a silver tray with a single envelope sealed with a tiny house-and-chip wax emblem, symmetrical composition, campy spooky theatrical lighting, dense crosshatching, no other text.
This Week in Locally Run News
Summary by Claude Sonnet 5.5 based on this week’s links:
- Local agents get packaged: Perplexity and NVIDIA launched Portable Computer, a local-first agent stack for DGX Spark with one-click local inference setup. VentureBeat's headline framed it as a fully local agent with zero token costs.
- Big open models shrink to fit: Unsloth said GLM-5.3-Flash can run at 3-bit on 128GB of RAM, and Daniel Han said it keeps 93% accuracy at 4-bit on a 256GB Mac or two DGX Sparks. At the smaller end, Carnice-V3-27b is pitched for a 3090-class consumer GPU.
- Measuring phone-sized models: Liquid AI released Pipette with Artificial Analysis to benchmark small models on-device, and Artificial Analysis announced testing on the iPhone 17 Pro. The point is that cloud-focused benchmarks don't capture how models behave on phones.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to Locally Run
Meet Portable Computer, Perplexity’s new local-first agent stack on NVIDIA DGX Spark. When running locally, Portable Computer offers one-click local inference setup and an optimized agentic experience for DGX Spark. Learn more and get started today:
https://x.com/nvidia/status/2092269109086126575
Perplexity partners with Nvidia to launch Portable Computer, a fully local AI agent with zero token costs | VentureBeat
https://venturebeat.com/infrastructure/perplexity-partners-with-nvidia-to-launch-portable-computer-a-fully-local-ai-agent-with-zero-token-costs
Which model should you run on the iPhone 17 Pro? Announcing our new intelligence and inference testing for small models on mobile devices: independent measurement of how capable small models are in typical on-device tasks, and how they perform on popular phones – in partnership”
https://x.com/ArtificialAnlys/status/2091922042459406560
Introducing Pipette: A benchmarking suite for on-device intelligence | Blog | Liquid AI
https://www.liquid.ai/blog/pipette-on-device-ai-benchmarking-by-liquid-ai
Introducing Portable Computer
https://www.perplexity.ai/hub/blog/introducing-portable-computer-for-local-first-ai
Welcome 🚀Carnice-V3-27b! 🚀 → Carnice is a 27 billion parameter model capable of beating models 10x the size in Hermes-agent, fully open-source and built on top of Qwen3.8-27B →Build to fit on Consumer GPU on a 3090+ to run locally🔥 →A full merged BF16 Qwen3.8-27B”
https://x.com/kaiostephens/status/2091710751509475543
GLM-5.3-Flash can now be run locally! ✨ Run 3-bit on 128GB RAM via Unsloth GGUF. GLM-5.3-Flash (ox-alpha) rivals Claude Opus 4.8 on DeepSWE, coding & agentic benchmarks. Guide:
https://t.co/oItBKYNrl9 GGUF:
https://x.com/UnslothAI/status/2092986464196002094
What comes next for MCP? The team shared a public roadmap for the next 6-12 months 🎉 – Long-running workloads with streaming, server push, and mid-flight steering – HTTP as protocol for local servers over stdio (means more unfication) – Progressive discovery for large catalogs”
https://x.com/_philschmid/status/2091887849683513533
llama.cpp docs now have a new home, shipped with ❤️ upcoming: speculative decoding in detail, quantization (k-quant, i-quant), coding agents what do you want to see next? 🤗 📖
https://t.co/g96cTPR24g @llama_cpp”
https://x.com/mervenoyann/status/2091892738832703781
You can use Grok Bot for more personal use-cases too! I use grok bot to: – count calories of meals – plan my upcoming trips (hotels + flights) – buy fruit from bay area local farms – organize and respond to emails It’s been fun to have a personal assistant!”
https://x.com/ZhaiAndrew/status/2092732745495748881
Exciting news: Qwen3.8-27B by @Alibaba_Qwen just landed in Code Arena: WebDev at #9 overall with 1595 pts. It is the only model in its size class in the top 10, and also reshapes the Pareto Frontier! It is only 6 ranks behind the much larger Qwen3.8-Max. For scale: Gemma 4-31B”
https://x.com/arena/status/2091920512796725272
UC Berkeley open-sourced FreeToken. Wild results: A single RTX PRO 6000 runs the 753B GLM-5.2 at 14.9 tok/s! An 8GB RTX 4060 laptop (~$1,000) runs Qwen3.6-35B at 39.3 tok/s! FreeToken is 2-4x faster than Ollama across consumer GPUs. Local AI inference is getting very real.”
https://x.com/Yuchenj_UW/status/2090857982385066474
💥💥 2 banger open model drops today – (al)ready to deploy on-prem on @Dell > Qwen 3.8 Flash Next from @Alibaba_Qwen > GLM 5.3 Flash from @Zai_org You can host the frontier, you can build your own AI. Congrats team on the release! @ehcalabres @balaatdell”
https://x.com/jeffboudier/status/2092713057026007488
GLM-5.3-Flash (ox-alpha) can be quantized down to 4-bit and retain 93% accuracy! The 4-bit model is essentially like a local Claude 4.7 Opus. It runs perfectly on a 256GB Mac or two DGX Sparks. 5-bit may even work.”
https://x.com/danielhanchen/status/2092996385302094189
Sopro V2: private, fast, on-device text-to-speech · Halo Research
https://research.haloneuro.ai/posts/sopro-v2
Today we release Pipette, a model evaluation suite for on-device intelligence, in partnership with @ArtificialAnlys Most benchmarking platforms are optimized to measure core capabilities and speed profile of foundation models served in the cloud. Pipette gives the field a”
https://x.com/liquidai/status/2091906366428598284
Inference on steroid: NVIDIA’s Groq 3 LPX is now in full production, adding a dedicated token-generation accelerator to the Vera Rubin platform. NVIDIA says it reached 3,400 output tokens per second running Gemma 4 31B with a 100,000-token context in Artificial Analysis”
https://x.com/kimmonismus/status/2091926070085759448
Kimi K3 is now available on all Pro and Max subscriptions via included usage. More models coming soon 🫡”
https://x.com/ollama/status/2090906360808411568
we, fortunately, saw this coming a few years back and bought our own gpus and self hosted them (in my shed). We’ve saved close to 10x the rental cost over time. now, the downside is that I got woken up at 2am because the AC filter needed changing and the room got too hot. But”
https://x.com/andrew_n_carr/status/2090864978152882311
Welcome @ATT to open models!”
https://x.com/ollama/status/2090601698402447748




Leave a Reply