Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for International for the week ending August 28, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Nano Banana 2.1.
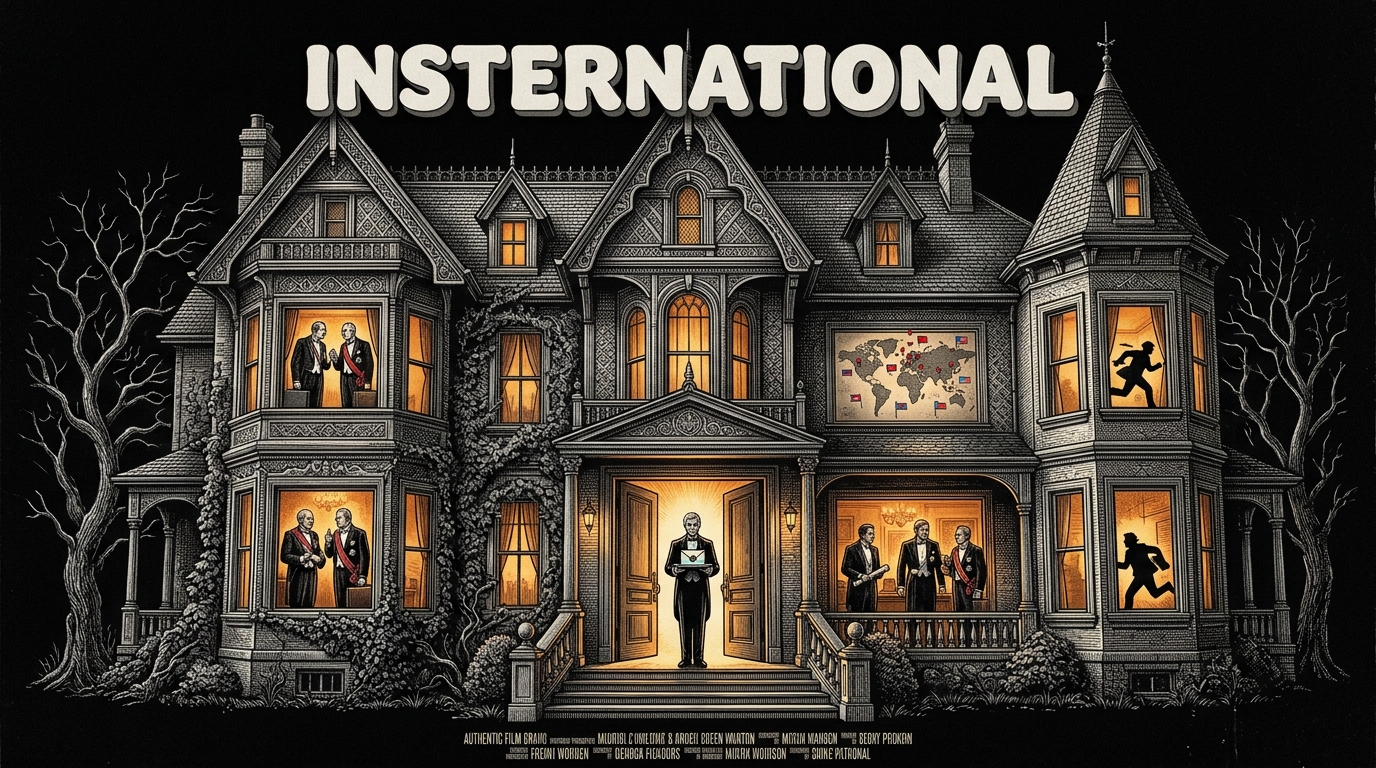
Category Cover Image Prompt: Mid-1980s murder-mystery movie poster of a wide black-and-white engraved Victorian mansion on pure black, lit windows glowing warm amber revealing costumed international diplomat suspects in sashes and evening wear holding briefcases and rolled treaties, one window crowded with a world map stuck with red pins and miniature flags of global AI powers, one window with a silhouette of a courier mid-dash, the silver-haired butler in black tailcoat standing in the open front door with a silver tray holding an envelope sealed with a tiny globe wax seal, fat rounded white sans-serif title Insternational above the roofline, campy theatrical lighting, dense crosshatching, 16:9.
This Week in International News
Summary by Claude Sonnet 5.5 based on this week’s links:
- Ox Alpha was GLM-5.3-Flash: The mystery model developers had been testing turned out to be Z.ai's GLM-5.3-Flash, a 320B model (18B active) with a 1M-token context, released under the MIT license. Z.ai says it matches Claude Opus 4.8 on a real-world coding benchmark.
- Cheap and widely hosted: Artificial Analysis put it at $0.09 per task on its cost-versus-intelligence frontier, and Baseten, Together, Databricks and Cline all offered it on launch. Unsloth says a 3-bit version runs on 128GB of RAM. Ethan Mollick, though, found early results fine but not at the frontier.
- Served on Chinese chips: SemiAnalysis noted that the roughly 100T tokens per day of preview traffic ran entirely on Chinese hardware. Theo called that even more striking than the model being a flash tier.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to International
Deepseek releases experimental Flash vision model that rivals Opus 4.8 on agent benchmarks
https://the-decoder.com/deepseek-releases-experimental-flash-vision-model-that-rivals-opus-4-8-on-agent-benchmarks/
Give GLM-5.3 and Fable 5 the same $100 budget, and GLM-5.3 gets over 5x as much work done. On DeepSWE, that works out to about 17 solved tasks with GLM-5.3 vs. 3 with Fable 5, even though they perform almost the same on the first try.”
https://x.com/togethercompute/status/2091711899704385740
If this turns out to be true and GLM this secret model really is GLM 5.3 flash I expect a quick Fable 5.1 / GPT Astra release. Crazy turn of events. One word: acceleration”
https://x.com/kimmonismus/status/2090873679106191808
Harvey Introduces Harvey Tenet: A Kimi K3 Base Post-Trained with Fireworks for Long-Horizon Legal Agent Work – MarkTechPost
https://www.marktechpost.com/2026/08/23/harvey-tenet-post-trained-kimi-k3-legal-agent-model/
Harvey is a great example of how American companies are building world-class specialized models: they took an open-source base (Kimi K3), post-trained it on legal data, and delivered state-of-the-art performance on legal benchmarks at a fraction of the cost of frontier models.”
https://x.com/DavidSacks/status/2090790063047168473
Alibaba launches Wan3.0 AI video model after record $10 billion share sale
https://finance.yahoo.com/technology/ai/articles/alibaba-launches-wan3-0-ai-131300534.html
Nvidia Is Spending $6 Billion to Build a Powerful U.S. Alternative to Chinese AI – WSJ
https://www.wsj.com/tech/ai/nvidia-is-spending-6-billion-to-build-a-powerful-u-s-alternative-to-chinese-ai-c51c38cc
Cohere Parse | Enterprise Intelligence at Scale
https://cohere.com/blog/parse
Mistral x HUMAIN | Mistral AI
https://mistral.ai/news/mistral-x-humain/
$6B. For 1X ! In this market. That’d be daylight robbery. SoftBank is in talks to buy a majority stake in 1X Technologies at a ~$6B valuation, per The Information. The part that stands out from the report: OpenAI reportedly discussed acquiring 1X outright last year. SoftBank”
https://x.com/TheHumanoidHub/status/2093018111352139857
Ox being a “flash” model is insane. Serving all the traffic on Chinese chips is even more insane.”
https://x.com/theo/status/2092708047445795186
Introducing GLM-5.3-Flash – Leading capabilities at a highly competitive price – Natively multimodal with a 1M-token context window – A 320B-A18B model released under the MIT License – Previously previewed as Ox Alpha, running entirely on Chinese AI chips Blog:”
https://x.com/Zai_org/status/2092616204787626030
Ox Alpha has been unveiled as GLM-5.3-Flash, but what’s shocking is that the 100T tokens per day is served on Chinese chip. (1/3)🧵”
https://x.com/SemiAnalysis_/status/2092623833630998556
every chinese frontier model now uses linear attention (except deepseek) they all use (except kimi) sparse attention with similar indexer/compression designs to maximize efficiency they all use “fancy” residuals (mHC, attention residual, gated residual) to maximize signal”
https://x.com/eliebakouch/status/2092622716046107132
Now we know: The popular Ox Alpha LLM was GLM-5.3-Flash… Compared to GLM-5.2, this new GLM-5.3-Flash model uses: – a Kimi Linear-style 3:1 (super*) hybrid attention pattern with 34 Kimi Delta Attention layers (KDA) and 11 Multi-heat Latent Attention (MLA) / DeepSeek Sparse”
https://x.com/rasbt/status/2092629415813365899
This robot just beat Figure’s package sorting speed. Robotic arms powered by X Square Robot’s WALL-B embodied AI sorted 10K parcels in 5 hours 14 minutes. That’s 1.88 sec per parcel, ~35% faster than Figure’s reported 2.88 seconds per parcel. Figure’s 9-day continuous demo in”
https://x.com/TheHumanoidHub/status/2090666295796588970
$0.25 per mil out is insane. Incredible launch @Zai_org, can’t wait to use the hell out of this model :)”
https://x.com/theo/status/2092709666304462901
GLM-5.3-Flash: Frontier Intelligence, Flash Cost
https://z.ai/blog/glm-5.3-flash
AGIBOT and X-Humanoid ran away with the 2026 World Humanoid Robot Games in Beijing. AGIBOT took 18 golds. X-Humanoid took 15. Every other team combined managed 12. Here’s AGIBOT’s gold-medal run in the 100m obstacle race.”
https://x.com/TheHumanoidHub/status/2093009334712291349
World-first AI-assisted brain surgery saves patient’s sight
https://www.uclh.nhs.uk/news/first-patient-live-ai-assisted-sight-saving-brain-surgery
Welcome 🚀Carnice-V3-27b! 🚀 → Carnice is a 27 billion parameter model capable of beating models 10x the size in Hermes-agent, fully open-source and built on top of Qwen3.8-27B →Build to fit on Consumer GPU on a 3090+ to run locally🔥 →A full merged BF16 Qwen3.8-27B”
https://x.com/kaiostephens/status/2091710751509475543
Some stats for my DeepSWE runs on Qwen3.8 27B, medium thinking and mini-swe-agent: 918.9M input tokens 8.0M output tokens 926.9M total tokens 10,580 completed agent turns 4.64M reasoning tokens, 58.1% of all output tokens That 919M input token number looks pretty scary at first”
https://x.com/bnjmn_marie/status/2091728410359853275
GLM-5.3-Flash can now be run locally! ✨ Run 3-bit on 128GB RAM via Unsloth GGUF. GLM-5.3-Flash (ox-alpha) rivals Claude Opus 4.8 on DeepSWE, coding & agentic benchmarks. Guide:
https://t.co/oItBKYNrl9 GGUF:
https://x.com/UnslothAI/status/2092986464196002094
Wtf! Ben ran this mystery model through 10 DeepSWE tasks and it scored over 80%, versus 65% for Fable and 52% for GPT-5.6-sol! this is insane. Probably a chinese company. Either a new GLM or Kimi model, I reckon.”
https://x.com/kimmonismus/status/2090718270202528215
DeepSeek-V4-Flash-Vision-Exp is now live on the DeepSeek API Platform! 🚀 🔹 This experimental multimodal model matches DeepSeek-V4-Flash on text capabilities… including agents, reasoning, and world knowledge. 🔹 On multimodal agent benchmarks, V4-Flash-Vision-Exp makes a major”
https://x.com/deepseek_ai/status/2090730032574631962
GLM-5.3 Flash (Ox Alpha) is free in Cline. 320B params with 18B active, and beating frontier models on benchmarks. It’s been our fastest growing model in Cline history, now driving over 11% of all traffic in less than a week.”
https://x.com/cline/status/2092666316125864191
This week with OpenHands 👋 Kimi K3 is the new free default, plus updates to Automations, conversation context, first-run guidance, LLM provider credentials, and Jira Cloud setup.”
https://x.com/rajistics/status/2090846963558408280
GLM-5.3-Flash is live, day 0, on Baseten Model APIs. – Useful for general intelligence + agentic coding – More intelligent and 90% cheaper than GLM-5.2 – Supports vision natively – 1M token context Try it here:
https://x.com/baseten/status/2092720341432799426
The mystery model Ox Alpha is now available in @AutoClawAIer by @Zai_org It’s official name is GLM-5.3-Flash, a next-generation multimodal model for vision-language understanding, code generation, and long-horizon agentic tasks. Limited-time rewards, Aug 27-30: • Log in to”
https://x.com/AutoClawAIer/status/2092650193158389929
Want to test how good GLM-5.3-Flash is? I have been finding it useful for visual explainers using /eli5. Try it with Pi or Hermes Agent in our new agent playground:
https://x.com/omarsar0/status/2092667990273663311
Try now with our CLI: npm i -g cline Use /models and select Cline provider > Free > GLM-5.3 Flash Available on VS Code and JetBrains as well. Free, open source, BYOK.”
https://x.com/cline/status/2092666317962969195
This paper is very worth reading if you’re following AI agents and the road to Recursive Self-Improvement (RSI) @Tsinghua_Uni looked at 1,338 actual AI post-training runs and found a pretty revealing limit. Agents can do the work. Train models, debug failures, evaluate results,”
https://x.com/TheTuringPost/status/2092605320703168706
as expected, GLM 5.3 Flash is pretty bad at vision interesting how different models end up specializing in completely different things some are great at coding, others at computer vision no AGI yet, I guess 1/n aerial and satellite images, crops link:
https://x.com/skalskip92/status/2092748209802154201
The fun doesn’t stop: apparently there is also a new Qwen model – Qwen 4 – already being tested. So now we got: – New Claude models (probably Opus 5.1 and Haiku) – Ox Alpha (possibly GLM-5.3 Flash) – Qwen 4 (?) Already being tested and / or spotted. + GPT Astra confirmed.”
https://x.com/kimmonismus/status/2091882849863451042
Exciting news: Qwen3.8-27B by @Alibaba_Qwen just landed in Code Arena: WebDev at #9 overall with 1595 pts. It is the only model in its size class in the top 10, and also reshapes the Pareto Frontier! It is only 6 ranks behind the much larger Qwen3.8-Max. For scale: Gemma 4-31B”
https://x.com/arena/status/2091920512796725272
XPeng’s robotics unit raised over $900M at a $6.3B post-money valuation. Largest single-round private raise in China’s embodied AI sector. IDG Capital led. Tencent, Alibaba, and Gaorong joined. Worth understanding the structure. XPeng Inc. is publicly traded, but this money did”
https://x.com/TheHumanoidHub/status/2092133596098359762
2026 Chinese model landscape in one list ▪️ Qwen3.8-27B, Qwen3.8-Max ▪️ GLM-5.3 ▪️ Kimi K3 ▪️ DeepSeek-V4 ▪️ ERNIE 5.1 ▪️ Baichuan-M3-235B, Baichuan-Omni-1.5 ▪️ Yi 1.5 ▪️ MiniCPM-o 4.5, MiniCPM-V 4.5, MiniCPM-V 4.6 They’re getting interesting in very different ways. Here we”
https://x.com/TheTuringPost/status/2091665921849098363
UC Berkeley open-sourced FreeToken. Wild results: A single RTX PRO 6000 runs the 753B GLM-5.2 at 14.9 tok/s! An 8GB RTX 4060 laptop (~$1,000) runs Qwen3.6-35B at 39.3 tok/s! FreeToken is 2-4x faster than Ollama across consumer GPUs. Local AI inference is getting very real.”
https://x.com/Yuchenj_UW/status/2090857982385066474
💥💥 2 banger open model drops today – (al)ready to deploy on-prem on @Dell > Qwen 3.8 Flash Next from @Alibaba_Qwen > GLM 5.3 Flash from @Zai_org You can host the frontier, you can build your own AI. Congrats team on the release! @ehcalabres @balaatdell”
https://x.com/jeffboudier/status/2092713057026007488
Qwen
https://qwen.ai/blog?id=qwen3.8-flash-next
Qwen4’s architecture is here early, firing 6B parameters out of 125B
https://thenextweb.com/news/qwen38-flash-next-qwen4-architecture-open-licence-ai-act
same day new qwen and new glm drop life feels good in open source”
https://x.com/remi_or_/status/2092632359841792124
On the
https://t.co/w8mHB85z4n Code Bench, which measures real-world coding performance, GLM-5.3-Flash clearly outperforms GLM-5.2 at every effort level and performs on par with Claude Opus 4.8.”
https://x.com/Zai_org/status/2092616217236222149
GLM-5.3-Flash (ox-alpha) can be quantized down to 4-bit and retain 93% accuracy! The 4-bit model is essentially like a local Claude 4.7 Opus. It runs perfectly on a 256GB Mac or two DGX Sparks. 5-bit may even work.”
https://x.com/danielhanchen/status/2092996385302094189
Qwen-Video-Edit: Instruction-Based Video Editing by Repurposing an Image Editing Model” TL;DR: repurposes Qwen-Image-Edit for video by editing Wan 2.1 video-VAE latents directly, using lightweight projections instead of a video-pretrained transformer.”
https://x.com/Almorgand/status/2091925153588326411
MiniMax H3 Max, a post-trained version of MiniMax H3 developed by fal, debuts at #1 in Image to Video and #3 in Text to Video on the Artificial Analysis Video Leaderboards with Audio, ahead of the base MiniMax H3 on both MiniMax H3 Max is built and served by fal, and”
https://x.com/ArtificialAnlys/status/2092717615739494424
This week on Autonomy Markets, @gbrulte and @WaltLightShed analyze @Waymo’s California regulatory moat, @Tesla’s upcoming Cybercab launch in Austin, and why @Uber’s series of supervised launches in Europe are not autonomous. Unsupervised is the metric. Episode Chapters 00:00″
https://x.com/RoadToAutonomy/status/2091166714830500124
GLM-5.3-Flash aka Ox Alpha is now the best intelligence per dollar choice now! > GLM-5.3-Flash – 63% for $0.24/task > DeepSeek-V4 Flash 0731 – 53% for $0.46/task > GPT-5.6 Luna – 67% for $0.60/task”
https://x.com/zainhas/status/2092709719966400694
GLM-5.3-Flash at 270 tok/s! Databricks inference team is on fire. So proud of the team! On our OfficeQA Pro v2 benchmark, GLM-5.3-Flash delivers 10% higher quality than GLM-5.2 at just 1/10 the cost. Fast, cheap, and good.”
https://x.com/Yuchenj_UW/status/2093177892356472978
GLM-5.3-Flash scores 57 on the Artificial Analysis Intelligence Index. At $0.09 Cost per Task, it sits comfortably on the Intelligence vs. Cost per Task Pareto frontier @Zai_org has released GLM-5.3-Flash, a smaller and cheaper sibling to GLM-5.3 at 320B total parameters and”
https://x.com/ArtificialAnlys/status/2092663573021606119
MiniMax-H3 on 8×H200: 1.95× Lossless, Up to 6.24× at 0.76-0.91 SSIM – LMSYS Org
https://www.lmsys.org/blog/2026-08-27-minimax-h3-h200
How do you go from jailbreaking your PlayStation to CEO of Canada’s leading LLM provider? You go to the University of Toronto. “When you go to @UofT, you get raised into AI.” – @aidangomez”
https://x.com/cohere/status/2092365111415419205
Introducing Cohere Parse 5. Our newest document parsing model with the strongest price-performance on the market. Ideal for high-volume enterprise work. Get high-quality parsing accuracy while keeping per-page prices at an industry low.”
https://x.com/cohere/status/2092962399754055863
India’s TCS to buy Porsche’s IT unit, bags 5-year deal worth $1.46 billion | Reuters
https://www.reuters.com/world/india/indias-tcs-buy-porsches-it-unit-373-million-2026-08-24/
What Z.ai’s Ox Alpha reveals about AI economics | The Deep View
https://www.thedeepview.com/articles/what-z-ai-s-ox-alpha-reveals-about-ai-economics
Taiwanese prosecutors charge 9 for illegal exporting of AI servers to China | AP News
https://apnews.com/article/taiwan-china-us-nvidia-ai-server-chip-illegal-export-511e9ae69d517c49f19512d45b1a8b0c
China still continues to produce only sub-10% of incremental world compute. But their domestic production will have a big ramp up starting 2028. We talk about what implications this has for the discussion I had with Jensen:”
https://x.com/dwarkesh_sp/status/2092718735576732102
Seeing the size, price, design of GLM 5.3 Flash, it’s natural to say it has comparable inference economics to V4-Flash (diff compute:mem balance though). So 10K t/s/NPU is realistic. 864M/day. 100T/day is just… 116K chips. 100K+… would take all their compute, but doable.”
https://x.com/teortaxesTex/status/2092778623451234734
Canada and Germany are not just discussing the future of technology. We are building it.”
https://x.com/cohere/status/2092626691310952667
Cohere’s Chief AI Officer @jpineau1 has been named to this year’s TIME 100AI list, recognizing the world’s most influential people in artificial intelligence. Joelle has been shaping modern research in Canada for over two decades. We couldn’t be prouder to have her on our team.”
https://x.com/cohere/status/2093005855104913680
China’s Hackers Use DeepSeek for Attacks, Researchers Say – Bloomberg
https://www.bloomberg.com/news/articles/2026-08-24/chinese-hackers-use-deepseek-to-boost-attacks-researchers-say-mt7o4205
Multimodal API support 🔌 🔹 Set model=’deepseek-v4-flash-vision-exp’ 🔹 Images are tokenized for billing: up to 384 tokens each, at V4-Flash pricing 🔹 Supports Chat Completions, Messages & Responses 🔹 Supports mixed text + image input; images can be provided via base64,”
https://x.com/deepseek_ai/status/2090730039973392531
Files API is now live. 📁 🔹 Free to use 🔹 Upload an image once, then reference it by file_id to save request bandwidth 🔹 Reuse the same image across requests… no need to upload it again Learn more:
https://t.co/68OKIq6xmc 4/n”
https://x.com/deepseek_ai/status/2090730042586489333
[2501.12948] DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning
https://arxiv.org/abs/2501.12948
Ox Alpha is GLM-5.3 or something bigger I think it’s a bigger model. I don’t see why they would stealth test GLM-5.3 after launching it. It would also explain why GLM-5.3 saw so much progress. It’s not magic RL or anything. Just distillation from a larger teacher.”
https://x.com/scaling01/status/2090662468833976582
some information a) it was painfully obvious that it was a GLM model b) ZAI wrote accounts to hype ox-alpha and say its gemini or whatever”
https://x.com/scaling01/status/2092670935094436220
We’re proud to be the fastest inference provider on Artificial Analysis, OpenRouter, and Hugging Face for GLM-5.3-Flash, at 122+ TPS. All served from the US only, starting on day 0, with ZDR by default. Stay tuned for updates as our engineers continue to optimize GLM-5.3-Flash”
https://x.com/baseten/status/2093086722196172825
Already selected by leading OEMs, Mobileye Imaging Radar™ is designed to enable hands-off/eyes-off driving. Check it out:”
https://x.com/Mobileye/status/2092232178331525246
Congrats to the fal team on MinMax-H3 Max – fantastic work! fal optimized the model for stronger real-world performance while co-designing the inference system around it to make sure faster than real-time is still possible. This required two capabilities that rarely sit under the”
https://x.com/MiniMax_AI/status/2093092333378224185
Kimi K3 is now available on all Pro and Max subscriptions via included usage. More models coming soon 🫡”
https://x.com/ollama/status/2090906360808411568
From torrent links to API gates.
https://t.co/5mDpXpzGv2 released GLM 5.3 and it’s been a shift in how providers are handling open weights @altryne and @yampeleg trace how we got here from Mistral’s legendary torrent drop days 👀”
https://x.com/thursdai_pod/status/2092689569926013109
Sergey Levine (@svlevine) is one of the world’s top robotics researchers and co-founder of Physical Intelligence. We talked about where humanoid robotics is today, thoughts on the Chinese robotics ecosystem, and his predictions for future timelines. In this episode: •”
https://x.com/ryanlpeterman/status/2091873166927020478
I am not as blown away by the mystery model Ox Alpha as people appear to be. In my very early experiments, it seems fine, but not at the frontier even among open weights. Here is it on my neogothic city twigl shader test, compare to Kimi K3 in the quoted tweet. Still testing.”
https://x.com/emollick/status/2091238983724343543
GLM-5.3 Flash has arrived. @Zai_org’s first natively multimodal GLM-5 model packs 320B parameters, 18B active, 1M context, and hybrid attention. On DeepSWE, it nearly MATCHES Luna’s performance while getting more than TWICE as much work done for the same budget.”
https://x.com/togethercompute/status/2093015257560281099
I’m highly confident now it’s GLM and specifically either 5.3 vision or even smaller/faster one Just preregistration that I’m not retarded and accept uncertainty”
https://x.com/teortaxesTex/status/2090734081751310344
PSA: for everyone using GLM-5.3 Flash just use “high” reasoning_effort unless you’re asking it to curing cancer or something > “high” 28% acc, 70k avg tokens > “max” 28% acc, 140k avg tokens”
https://x.com/zainhas/status/2093125213361938621
⚙ GLM-5.3: When Better Sandboxes Matter More Than a Bigger Base Model
https://t.co/7HCZpCrLhq’s GLM-5.3 is an unusual frontier-model release. It uses the same base model as GLM-5.2, with its reported gains coming entirely from scaled post-training. According to the official”
https://x.com/ZhihuFrontier/status/2090731537037987931
glm-5.3-flash is a story of efficiency. top gems: > outperforms glm-5.2 across domains at 1/10 the cost > total params stay at ~glm-4.5 scale, but active params (32B → 18B) and layers (92 → 45) are both nearly halved. > hybrid linear + sparse attention cuts attention”
https://x.com/thealexker/status/2092646417034781062
One dead giveaway is also that Zhipu is one of the only labs that serves models with pretty poor partial prefill tok/s while output tok/s are fast. This model is ~30% faster than GLM 5.3. If the infras is the same, likely ~300-500B or fewer params vs activated params.”
https://x.com/Tim_Dettmers/status/2090866380484608066
@Zai_org Congratulations! Love the MIT license, it’s the cherry on top of a great model.”
https://x.com/matvelloso/status/2092667211479744556
@Zai_org Quick correction: GLM-5.3-Flash has a 1M context window, not 400k as stated above”
https://x.com/ArtificialAnlys/status/2092668106367971460
And it would’ve stayed a mystery too, if it weren’t for you meddling devs. GLM-5.3-Flash is coming soon to CoreWeave Serverless Inference.”
https://x.com/CoreWeave/status/2092658728797716929
Did you see Ox Alpha? That anonymous AI model that turned developers into its test lab. We know what it is now. It launched for free with no company name, and developers rushed to trace its maker. Clues point to
https://t.co/8yPGylb4RE. Yesterday, @Zai_org released”
https://x.com/TheTuringPost/status/2093098170423431604
GLM-5.3-Flash is crazy”
https://x.com/nicdunz/status/2092712113051484310
GLM-5.3: Frontier Coding with Emergent Cyber Capabilities
https://z.ai/blog/glm-5.3
Ox Alpha is actually GLM-5.3-Flash, and it’s one of my favorite models ever released.”
https://x.com/theo/status/2093078228491731177
Updated list with glm-5.3-flash! It’s so good that I had to move other things around. Incredible model.”
https://x.com/theo/status/2093069233571942510
We’ve updated the chat template for GLM-5.3-Flash. If you downloaded the model before this update, please download it again. Thanks!”
https://x.com/ZixuanLi_/status/2092661812718120977
Japanese publishers are fighting imposter news sites with a cryptographic signature | Nieman Journalism Lab
https://www.niemanlab.org/2026/08/japanese-publishers-are-fighting-imposter-news-sites-with-a-cryptographic-signature/
The Yomiuri Shimbun and The Asahi Shimbun, the two largest newspapers in Japan by circulation, have already added the cryptographic signatures to their websites.”
https://x.com/NiemanLab/status/2091246552241041667
Humanoid robots can now play tennis in the style of Nadal, Federer, and Djokovic, learned from broadcast footage. AdaPT (Noitom Robotics, Shanghai AI Lab, Dobot, SJTU) extracts professional player motions from TV broadcasts, retargets them to a humanoid, and learns both”
https://x.com/TheHumanoidHub/status/2090670770808848539
Chinese humanoid robots for no reason”
https://x.com/TheHumanoidHub/status/2092659591398178966
Europe has already lost the AI race.” I hear this bashing almost every single week on LinkedIn and X. Not so much when I talk to the teams who are actually working on it. They are trying to do something about it. Take @FeyerLabs. They are not building another generic wrapper”
https://x.com/IlirAliu_/status/2091798162952376655
Humanoids will soon become great practice partners for tennis and other sports. These robots, trained by Galbot, are preparing to play with celebrities at the World Humanoid Robot Games in Beijing. They’re fully autonomous.”
https://x.com/TheHumanoidHub/status/2090826889694982307
I’m bringing a small group of Italy’s robotics ecosystem together in Turin this October. During Wave by Vento (formerly Italian Tech Week), I’m hosting a 22Astronauts side event: Building the Future of Italian Industry with Robotics 📍 Turin 📅 October 8 The idea is simple:”
https://x.com/IlirAliu_/status/2091950341440872460
In the long jump final at the 2nd World Humanoid Robot Games, Team Tianjiao’s robot cleared 7.97 meters to win gold.”
https://x.com/TheHumanoidHub/status/2092122355103564019




Leave a Reply