Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for Audio for the week ending August 28, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Nano Banana 2.1.
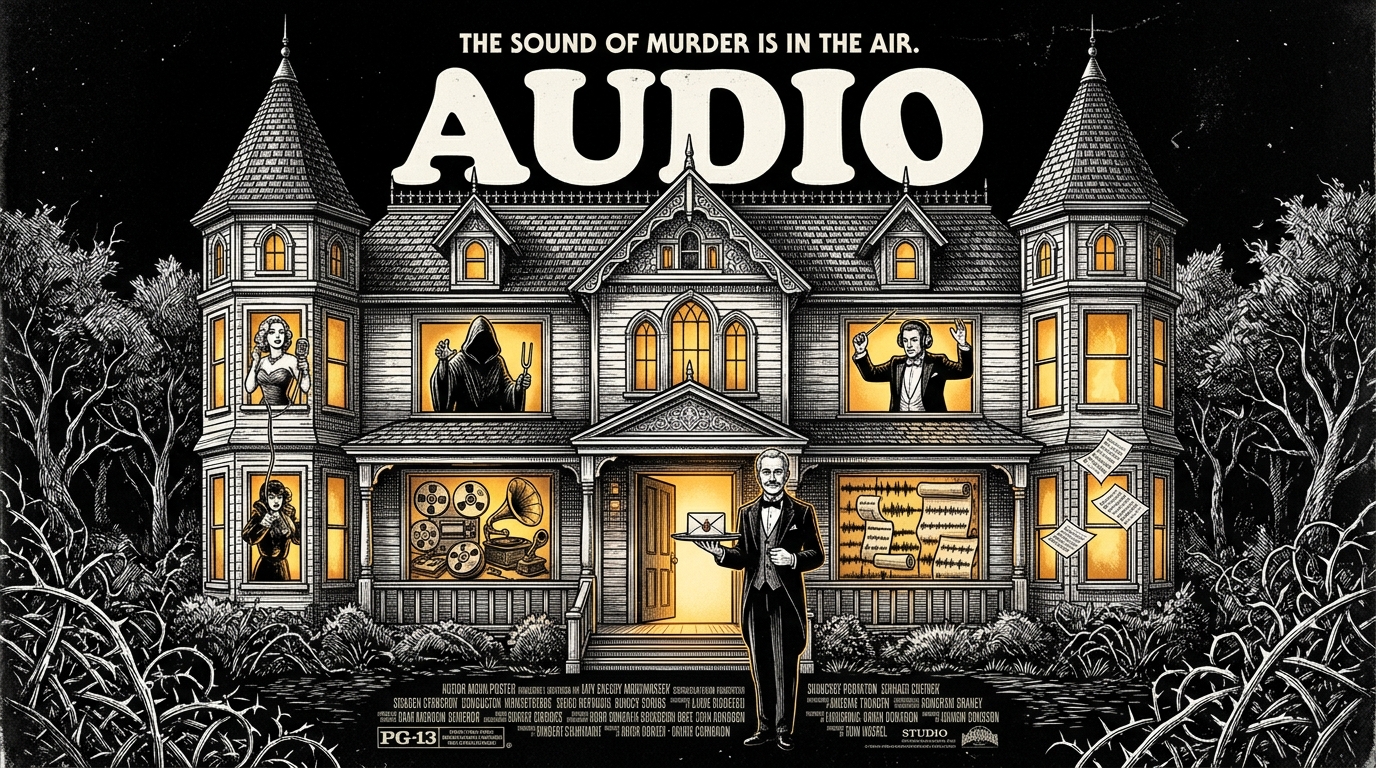
Category Cover Image Prompt: A wide 16:9 mid-1980s murder-mystery movie poster of a broad three-story Victorian mansion rendered in stark black-and-white pen-and-ink engraving with dense crosshatching on pure black, turrets at each end and fat rounded white title lettering reading 'Audio' above the roofline; warm amber windows reveal costumed suspects including a glamorous diva holding a vintage ribbon microphone, a tuxedoed conductor with studio headphones, and a cloaked figure brandishing a tuning fork, alongside windows crowded with reel-to-reel tapes, phonograph horns, waveform scrolls, and one window with a sheet of music tumbling mid-air. In the center open doorway stands an upright silver-haired butler in his sixties with a pencil mustache, black tailcoat, white gloves and a silver tray bearing an envelope sealed with a tiny treble-clef wax stamp, campy spooky theatrical lighting, symmetrical frontal composition.
This Week in Audio News
Summary by Claude Sonnet 5.5 based on this week’s links:
The clear story this week was Google's launch of Gemini 3.5 Transcribe, its new speech-to-text model, covered by Google, Sundar Pichai, Logan Kilpatrick, and Phil Schmid. Google says it handles 85+ languages, strips filler words like "um" and "ah", handles self-corrections, and supports custom vocabulary and multi-speaker identification. A live streaming version is aimed at agent interfaces. Schmid cited 2.6% word error rate for regular transcription and 4.0% for streaming. Artificial Analysis independently put the standard model at #5 on its AA-WER ranking and said the live version reaches 4.0% at 0.40 seconds after speech ends.
Two smaller items round it out. Hugging Face published a post on measuring benchmark optimization in speech recognition, a useful caveat when reading leaderboard numbers like these. Separately, Bilawal Sidhu's open-source God's Eye View adds a voice mode to a real-data 3D map, so you can ask what is happening in an area while looking at it.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to Audio
Asked God’s Eye View to explain why there’s so much military activity in this area — all using voice, while it sees what I’m seeing on the 3D map. Turns out Fort Rucker is a hot spot for helicopter training. So I jumped into cockpit view to track one of the choppers live in the”
https://x.com/bilawalsidhu/status/2092334246044074237
God’s Eye View V1 is open source. It feels like a spy simulator in your browser — except the underlying data is real, and you can talk to the planet too. Track planes, ships, satellites, traffic cameras, and critical infrastructure. Use voice mode to ask what’s happening,”
https://x.com/bilawalsidhu/status/2092011243074945433
Dr. Dre and Jimmy Iovine Think A.I. Is Good for Music – The New York Times
https://www.nytimes.com/2026/08/23/business/jimmy-iovine-dr-dre-beats-usc.html
Gemini 3.5 Transcribe is our latest speech-to-text model for precise and intelligent transcriptions. 🧵”
https://x.com/GoogleDeepMind/status/2092659221477077101
Today we’re introducing Gemini 3.5 Transcribe, our latest transcription model built for incredibly precise, smart dictation across your favorite apps and devices. Remember when traditional speech-to-text meant shouting over background noise, constantly hitting backspace to fix”
https://x.com/GoogleAI/status/2092660089509314735
Introducing Gemini 3.5 Transcribe
https://blog.google/innovation-and-ai/models-and-research/gemini-models/gemini-3-5-transcribe/
Today, we’re launching Gemini 3.5 Transcribe, our new speech-to-text model with sub-second streaming and intelligent post-processing for agent interfaces. 2.6% WER on non-streaming and 4.0% on streaming. Supports 85+ languages, cleans up conversational disfluencies (“um”, “ah”,”
https://x.com/_philschmid/status/2092659659866030112
Mixedbread is retrieval infrastructure for AI agents to find the right evidence across text, PDFs, tables, images, audio, and videos. We process millions of documents and searches every week. Our control plane runs on @planetscale Metal. → 0.05 ms p99 for our busiest”
https://x.com/mixedbreadai/status/2092654670988628223
AR guitar tutor! I’ve wanted something like this for so long. Check out this prototype by Allen Van Wert. Rocksmith is cool and all but this feels like the future. Makes me curious if others are building something like this? Should use monocular video & audio and work with”
https://x.com/bilawalsidhu/status/2092973390751473946
Humanoid AI models are hungry for diverse egocentric data with high-quality hand pose annotations. Ropedia’s HOMIE Gen2 targets that demand. A 380g headset that captures 360° from four cameras plus four-channel spatial audio, and outputs depth maps, camera poses, 21 hand and”
https://x.com/TheHumanoidHub/status/2092824006823227740
Google has released Gemini 3.5 Transcribe, ranking #5 on AA-WER at 2.6%, alongside Gemini 3.5 Transcribe Live, achieving 4.0% AA-WER Streaming at 0.40s after speech end @GoogleAI’s Gemini 3.5 Transcribe release comprises two API offerings: Gemini 3.5 Transcribe Live for”
https://x.com/ArtificialAnlys/status/2092697329933643881
Measuring benchmark optimization in speech recognition
https://huggingface.co/blog/asr-benchmark-optimization
MiniMax H3 Max, a post-trained version of MiniMax H3 developed by fal, debuts at #1 in Image to Video and #3 in Text to Video on the Artificial Analysis Video Leaderboards with Audio, ahead of the base MiniMax H3 on both MiniMax H3 Max is built and served by fal, and”
https://x.com/ArtificialAnlys/status/2092717615739494424
1/7 What does America’s AI future look like … and is Washington ready for it? This week at Stanford HAI, three of tech and policy’s prominent voices joined congressional staffers to discuss.”
https://x.com/StanfordHAI/status/2093122823548264887
Introducing Gemini 3.5 Transcribe, our new speech to text model with smart transcription, function calling, more precise transcription (lower WER), custom vocabulary support, multi-speaker identification, and support for over 85 languages! Also with realtime streaming support!”
https://x.com/OfficialLoganK/status/2092660925509890397
Say hello to Gemini 3.5 Transcribe! – Build apps that understand user speech / intent, even w/ multiple speakers! – Auto-detection of 85+ languages out of the box – Custom vocab adaptation for specialized jargon… SGTM:) API available now in @GoogleAIStudio and Gemini”
https://x.com/sundarpichai/status/2092659467284517088
We’re introducing Gemini 3.5 Transcribe, our most precise speech-to-text model yet 🔊 It turns audio into precise transcription in 85+ languages, removing filler words like “ums” and “ahs” while handling self-corrections and capturing your intent so you can get things done using”
https://x.com/Google/status/2092659278632894576
Sopro V2: private, fast, on-device text-to-speech · Halo Research
https://research.haloneuro.ai/posts/sopro-v2
What makes human intelligence fundamentally irreplaceable by AI? Stanford HAI Founding Director @drfeifei joins the @hubermanlab podcast to discuss how AI can extend human capabilities … and why your intuition and unique experiences are something no machine can replicate:”
https://x.com/StanfordHAI/status/2090909450991481031
Outgoing presenter of BBC Radio 4’s Today programme Amol Rajan has warned on a politics podcast that the BBC is destined to “get smaller at an accelerating rate””
https://x.com/pressgazette/status/2092908777938833507
In my ~14 months at @OpenAI, one of the most surprising and genuinely wonderful things about it, has been the full leadership support for full-duplex models (gpt-live series), even when it seemed deeply improbable that they would work. And yet, if they did work, it was obvious”
https://x.com/kundan2510/status/2091713860528984451
Large language models are trained on millions of authors … but converge on a single, homogeneous voice. A group of psychologists and computer scientists developed PsychAdapter to reintroduce human variation into AI-generated text, opening new possibilities for therapy training”
https://x.com/StanfordHAI/status/2092028830471119010




Leave a Reply