Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for Chips and Hardware for the week ending August 21, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
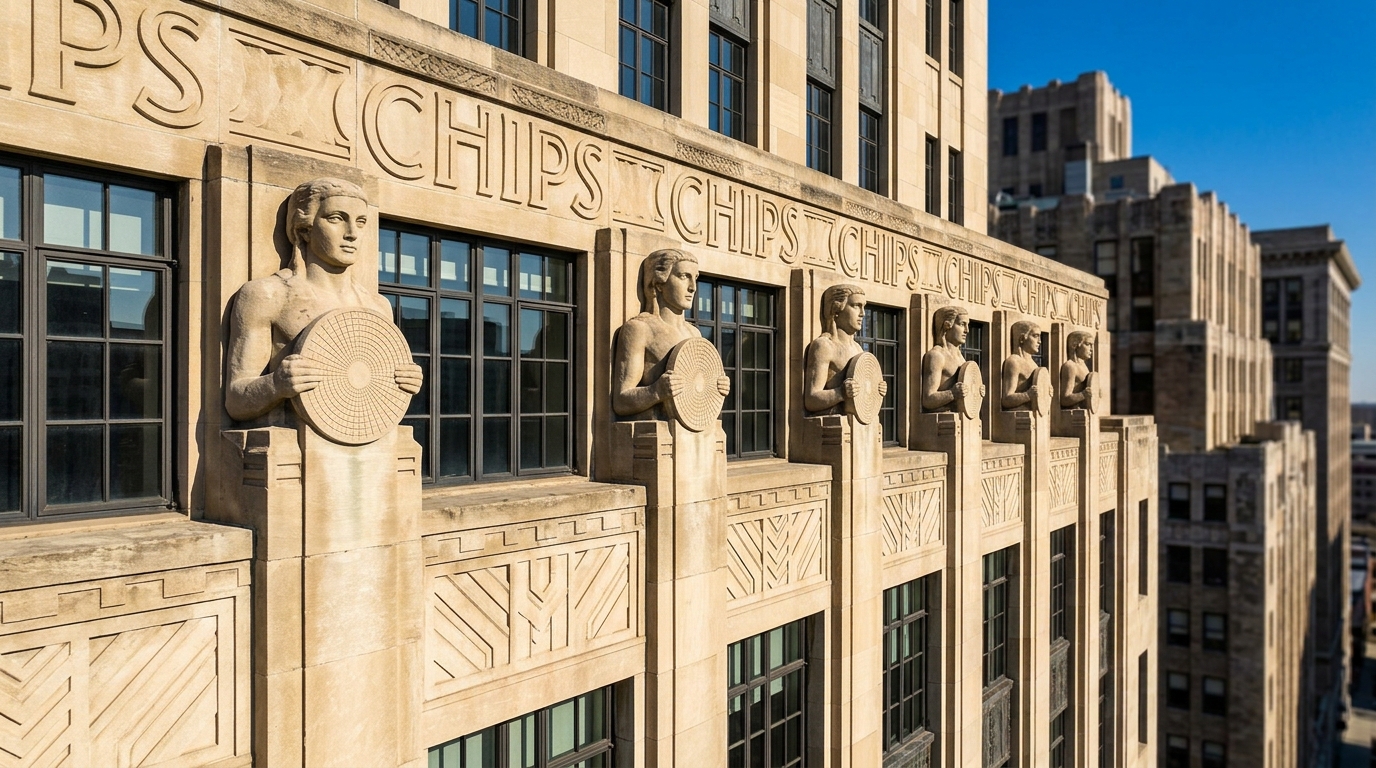
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Nano Banana 2.1.
Category Cover Image Prompt: Realistic architectural photograph of a 1929 Detroit Art Deco limestone skyscraper on a bright sunny day with deep blue sky, showing a setback with a repeating row of identical stylized herms carved from honey-cream Indiana limestone emerging from vertical piers between dark steel-framed windows, each herm holding a large circular stone wafer at its chest incised with a fine radial grid pattern, and shallow Deco chevron-and-keyline circuit reliefs on the piers below. A carved frieze band across the setback reads CHIPS in deep incised Art Deco capitals, with crisp raking sunlight casting sharp shadows in the carving, neighboring buildings receding behind, perspective-corrected verticals.
This Week in Chips and Hardware News
Summary by Claude Sonnet 5.5 based on this week’s links:
- Nvidia's money is the new moat: CNBC framed Nvidia's edge as shifting from chips to capital. Bloomberg reported Nvidia may invest up to $1 billion in Poolside, and Groq's $350 million raise came after its Nvidia deal.
- OpenAI's giant Nvidia commitments: Mark Chen announced 4+ GW of Nvidia capacity, and a post described an 8 GW Ohio campus built by SB Energy under a 20-year lease, hosting only Nvidia compute. OpenAI also said its first Vera Rubin racks are now running its training stack.
- Rivals keep pushing: Cerebras unveiled the CS-4, which a commenter said nearly doubled inference performance on the same 5nm wafer. Tom's Hardware reported Google tapped AMD to help design a next-generation TPU, and Modular said Qualcomm's data center accelerators now work with its platform.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to Chips and Hardware
Groq Raises $350 Million at $3.5 Billion Valuation
https://www.implicator.ai/groq-350-million-3-5-billion-valuation-after-nvidia-deal/
Nvidia to Invest Up to $1 Billion in AI Startup Poolside – Bloomberg
https://www.bloomberg.com/news/articles/2025-10-30/nvidia-to-invest-up-to-1-billion-in-ai-startup-poolside
Nvidia’s AI moat is shifting from chips to capital
https://www.cnbc.com/2026/08/18/nvidias-ai-moat-is-shifting-from-chips-to-capital.html
We’re excited to go big with NVIDIA and sign up for 4+ GW of capacity. This is the scale frontier training demands!”
https://x.com/markchen90/status/2089366892024893445
OpenAI has entered an agreement to secure approximately 8 GW (!) of AI capacity in Ohio, one of its largest infrastructure commitments yet. SB Energy will build, own, and operate the PORTS-Pike data center under a 20-year lease. The campus will exclusively host NVIDIA compute”
https://x.com/kimmonismus/status/2089371190276092299
excited to work together on this. thank you jensen!”
https://x.com/sama/status/2089758522678657212
excited to be working with @NVIDIAAI on bringing SkillEvaluator to ClawHub! our goal is to make it easy for your Claw to discover the best skills, not just based on vibes but on quantitative proof having evals that show a clear “skill lift”, eg how much the skill actually”
https://x.com/Pat_Erichsen/status/2090142910499205145
Ollama has the best performance for deepseek v4 flash on average. For local only, you can try qwen3.8 that is optimized: Apple Silicon: ollama run qwen3.8:27b-mlx NVIDIA: ollama run qwen3.8:27b”
https://x.com/ollama/status/2089454609765146744
Qwen3.8 vs Qwen3.6 vs Gemma 4: 24GB GPU Test
https://kingy.ai/blog/qwen3-8-27b-vs-qwen3-6-27b-vs-gemma-4-31b/
huge milestone in our partnership with NVIDIA”
https://x.com/gdb/status/2090515992506147198
AMD Instinct Coder: TCO calculator
https://www.spectrocloud.com/amd-instinct-coder-tco
Cerebras just announced their new AI accelerator CS-4″
https://x.com/scaling01/status/2089872780397285670
Every time a new AI accelerator enters the market, developers face the same question: how much of our stack do we have to rewrite? Modular’s unified compute platform is making that answer clear: none. Qualcomm Technologies’ data center AI accelerators are now integrated into the”
https://x.com/Modular/status/2089778003136196974
Game over for token costs: AMD Instinct Coder powered by Spectro Cloud
https://www.spectrocloud.com/freeplay
Teaching Everyone to Fish for Tokens – by Nathan Lambert
https://www.interconnects.ai/p/teaching-everyone-to-fish-for-tokens
This is seriously impressive: Cerebras just unveiled CS-4, and nearly doubled its AI inference performance without moving to a new process node. Same gigantic 5nm wafer. Same 4 trillion transistors. Same 900,000 AI cores. Instead, Cerebras redesigned the power delivery and”
https://x.com/kimmonismus/status/2090468333476860347
Google reportedly taps AMD to design next-generation TPU … hybrid AI ASIC could integrate on-package CPU cores for reinforcement learning | Tom’s Hardware
https://www.tomshardware.com/tech-industry/artificial-intelligence/google-reportedly-taps-amd-to-design-next-generation-tpu-hybrid-ai-asic-could-integrate-on-package-cpu-cores-for-reinforcement-learning
I’m a big fan of smaller MoE models, and NVIDIA’s Nemotron 3.5 lightning is a great release in this space… NVIDIA is expanding the suite / offering of Nemotron models to be quite comprehensive. Now, Nemotron includes a smaller MoE model (30B parameters, 3B active), which”
https://x.com/cwolferesearch/status/2089419256354033911
We just released TensorRT Model Connect in Public Preview. You can take a supported @huggingface model to end-to-end TensorRT inference in just two commands. No intermediate ONNX export, and the resulting bundle can run through native C++ APIs. We also built the entire project”
https://x.com/NVIDIAAI/status/2089750360869233059
GLM-5.3: How Chinese labs keep stride with the frontier
https://www.interconnects.ai/p/glm-53-how-chinese-labs-keep-stride
(60) The State of Model Routing … NVIDIA, Cognition, OpenRouter – YouTube
https://www.youtube.com/watch?v=QHBjufYK8TA&t=209s
A milestone for our infrastructure: our first NVIDIA Vera Rubin racks are here and now running our training stack. This is an important step as we expand compute that powers OpenAI’s next generation of frontier AI pre-training.”
https://x.com/udayruddarraju/status/2090343188393246973
Seeing a hype wave around GEN-1.5, and rightfully so. Lots of respect to Pete & Andy for executing so well. The secret is in the naturally repetitive motions in human-collected data. There’re 2 main sources for such repetitions: (1) Symmetric patterns. Sorting, tidying, and”
https://x.com/DrJimFan/status/2090465981240086992
Leave a Reply