Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for Audio for the week ending August 21, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Nano Banana 2.1.
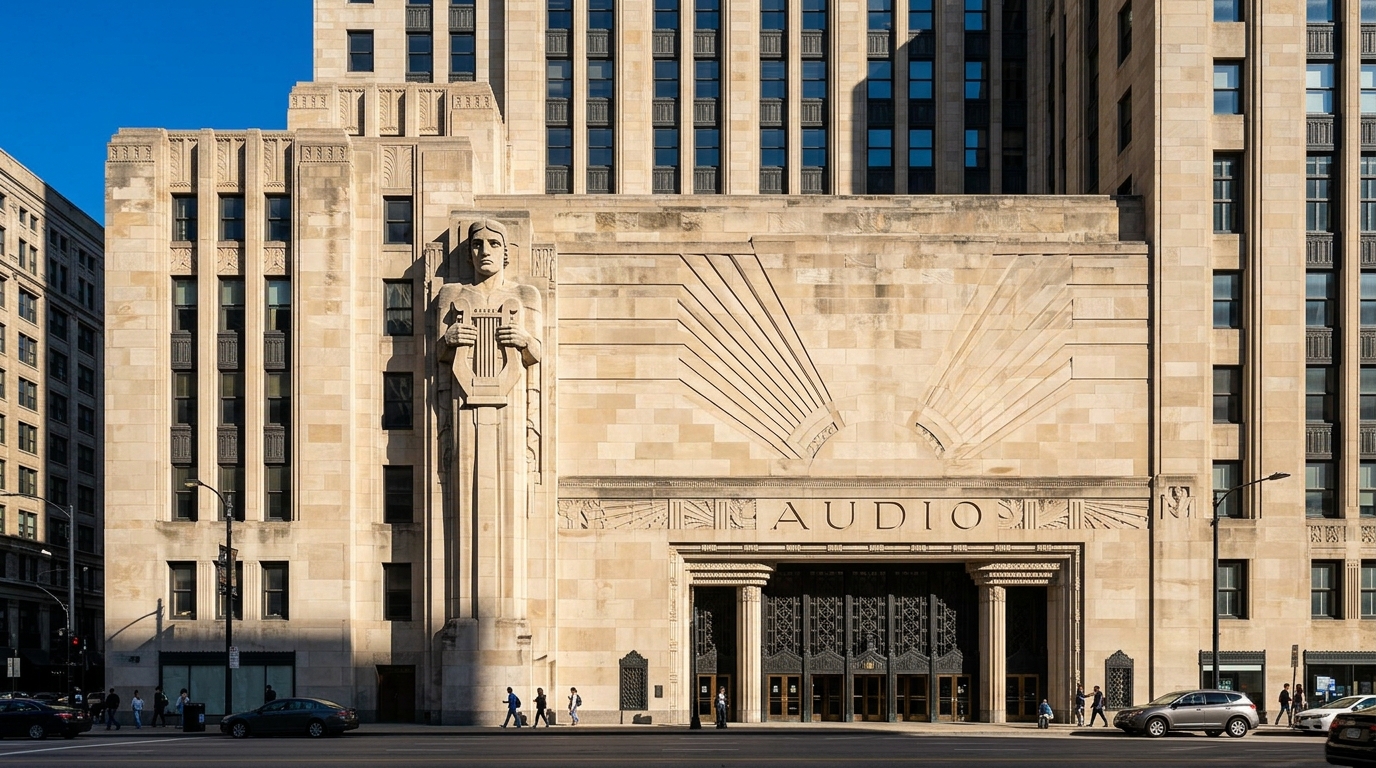
Category Cover Image Prompt: Realistic bright sunlit architectural photograph of a 1929 Chicago Art Deco limestone skyscraper, medium wide view from across the street, with a stylized engaged herm carved from honey-cream Indiana limestone emerging from a pier at a lower setback, holding a geometric Deco lyre against its chest while symmetrical carved sound rays fan outward in concentric chevrons across the ashlar wall, the word AUDIO incised in large Art Deco capitals on a frieze band above the entrance, dark steel-framed windows, deep blue sky, crisp raking shadows, perspective-corrected verticals.
This Week in Audio News
Summary by Claude Sonnet 5.5 based on this week’s links:
- Cartesia tops the speech leaderboards: Cartesia announced Sonic-3.6, a text-to-speech model covering 44 languages that arrives three months after Sonic-3.5. Artificial Analysis reported it took #1 on both its Provider Voice and Controlled Voice Speech Arena leaderboards.
- Audio generation moves into creative suites: Adobe Firefly now generates music, speech, and sound effects alongside its other creative tools in one place. Pika also published a post about its own audio models.
- Audio for video and AI labeling: One developer described feeding existing audio into MiniMax H3 instead of generating it, and was surprised by how good the lipsync and movement looked. Separately, Apple Music plans to launch labels for AI tracks later this year.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to Audio
On Dwarkesh Patel’s Podcast With Ryan Greenblatt
https://thezvi.substack.com/p/on-dwarkesh-patels-podcast-with-ryan
1/ muse spark 1.2 is a very strong multimodal model… it can do visual coding, robotics planning, and audio-visual understanding that all come together through agentic tools.”
https://x.com/alexandr_wang/status/2090485261629354352
Cartesia’s Sonic 3.6 takes the #1 spot on both the Provider Voice and Controlled Voice Artificial Analysis Speech Arena leaderboards, surpassing Speechify AI’s Simba 3.2 and Alibaba’s Qwen-Audio-3.0-TTS-Plus, with Sonic 3.5 holding #2 on Controlled Voice Sonic 3.6 is the latest”
https://x.com/ArtificialAnlys/status/2089400880688976062
Apple Music to Launch AI Song Labels Later This Year
https://www.hollywoodreporter.com/music/music-industry-news/apple-music-to-launch-labels-on-ai-tracks-1236677791/
Adobe Firefly expands its creative AI studio: generate music, speech, and sound effects in one place
https://blog.adobe.com/en/publish/2026/08/20/adobe-firefly-expands-its-creative-ai-studio-generate-music-speech-and-sound-effects-in-one-place
Cartesia | Real-time TTS API with AI laughter and emotion
https://www.cartesia.ai/sonic
Introducing Sonic-3.6: our most lifelike TTS yet, and another step change in naturalness across 44 languages. Just three months after our Sonic-3.5 launch, we’ve made fundamental model improvements based on feedback from the teams building on Sonic. We’re #1 on @ArtificialAnlys”
https://x.com/cartesia/status/2089401199967559932
MiniMax H3 image+audio to video feed an audio into h3 instead of generating it. i was testing this flow, got shocked with how good the lipsync and movement is implemented it on the i2v version in diffusers, made a demo for it. what do you think? 🔊 ▶️
https://x.com/multimodalart/status/2089418659370357191
Muse Spark 1.2 supports a broad range of multimodal tasks, from turning visuals into working code to translating perception into physical action. It also brings robust audio-visual understanding to enable video-heavy workflows common in real-world enterprise use. Today, we’re”
https://x.com/AIatMeta/status/2090485743034716420
superwhisper/s1-mini · Hugging Face
https://huggingface.co/superwhisper/s1-mini
Retrieve more, rerank, get better results. That’s what most of us expect from search, but it turns out to be wrong! 🤯 I’m SUPER EXCITED to publish the 141st episode of the Weaviate Podcast with Mathew Jacob (@mat_jacob1002)! Mathew led the work behind “Drowning in Documents
https://x.com/CShorten30/status/2089359280503681146
Everything You Want to Hear | Pika Blog
https://experiment.pika.art/blog/pika-audio-models
Leave a Reply