Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for Alibaba for the week ending August 21, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Nano Banana 2.1.
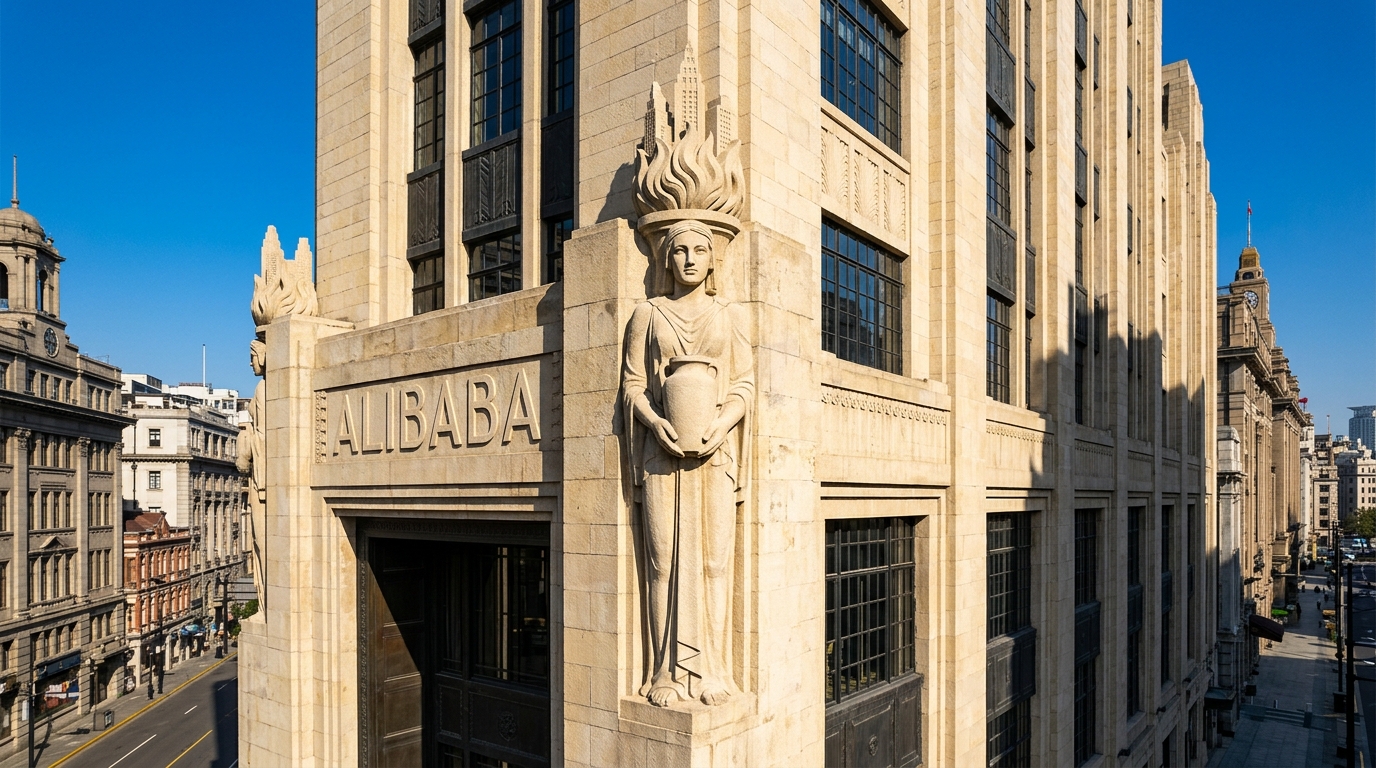
Category Cover Image Prompt: Realistic architectural photograph of a 1930s Art Deco limestone skyscraper in Shanghai Bund style on a bright sunny day with clear deep blue sky, a stylized frontal herm figure carved from the same honey-cream limestone emerging from a corner pier above the main entrance, cradling a tall open stone jar from which carved Deco flames and tiny stepped skyscrapers rise, dark steel-framed windows and setbacks receding behind, crisp raking sunlight casting sharp shadows across simplified geometric drapery. The name ALIBABA incised in large Art Deco capitals on a limestone frieze band above the entrance, perspective-corrected verticals, neighboring 1920s buildings visible in the background.
This Week in Alibaba News
Summary by Claude Sonnet 5.5 based on this week’s links:
- A 27B model people can run at home: Qwen3.8-27B was the story. Cline said it became its top local model within four days, and Artificial Analysis rankings placed it near much larger models. One user reported it running on an RTX 5090 with Codex and calling it "quite smart". Unsloth also released 1-bit GGUF versions, which it says run on 8GB RAM and keep about 77% of the accuracy.
- Real-world results are mixed: Ethan Mollick said it is nowhere near the other models listed for complex agentic tasks and urged people to run their own tests. A separate user reported that a one-shot fluid simulation prompt produced a black screen after an hour, where Opus 4.5 worked in a minute. Simon Willison called it excellent but prone to overthinking.
- Local tooling and safety concerns: Ollama and an MLX build make it easy to run on Apple Silicon and NVIDIA hardware, and DFlash 2 reportedly hits 70 tok/s on an M5 Max MacBook Pro. An uncensored MLX version also appeared, and even its creators warn it can supply malware and weapons instructions.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to Alibaba
Qwen 3.8 27B is #6 among open-weight models on the Vals Index v2 and is #1 on Harvey’s Legal Agent Benchmark among open weights.”
https://x.com/ValsAI/status/2089836844842435040
Qwen 27B is really good local model but, when you use it, it is immediately absolutely and obviously nowhere near as good as the other models listed here for agentic tasks, and especially for the kinds of complex tasks that GDPval-AA proports to measure Do your own benchmarking!”
https://x.com/emollick/status/2089914722464223706
Qwen3.8-27B ranks #7 on Artificial Analysis’ Agentic Index at only 27B parameters, a fraction of the size (and cost) of the other six. Train and deploy it all on one platform with the Baseten Loops SDK:”
https://x.com/baseten/status/2089749674265551077
Qwen3.8-27b is surprisingly usable with codex on my rtx5090! ~200k context with nvfp4 – *very* steerable with skills and plugins – quite smart! great for frontend, basic debugging, and image I don’t trust it (yet) to run in yolo mode – but *very* impressed by how capable it is”
https://x.com/rishdotblog/status/2089458516092399889
Watching a team of bots split up a large game project based entirely on their own experience and specialties with little input from me is pretty crazy (and just a bit creepy) to watch. I made a short video on group chats in the Hermes Desktop App Bot Mode: – Qwen Bot mentions”
https://x.com/tonbistudio/status/2089226021749030999
A “refusal-removed” version of Qwen3.8-27B can now run locally on Apple Silicon. Even its creators warn that it can provide malware, fraud and weapons instructions on demand. It was released as an MLX build in 2, 4, 6 and 8-bit versions. The uploader claims its 4/6/8-bit tests”
https://x.com/kimmonismus/status/2089763435865088508
literally just tried to let qwen3.8 27b one shot a fluid simulation webapp it thought for 40k tokens, took around 1 hour to generate and it’s just black and doesn’t work meanwhile Opus 4.5 just oneshots it in a minute and works wonderfully exact same prompt”
https://x.com/scaling01/status/2089784644400976254
Ollama has the best performance for deepseek v4 flash on average. For local only, you can try qwen3.8 that is optimized: Apple Silicon: ollama run qwen3.8:27b-mlx NVIDIA: ollama run qwen3.8:27b”
https://x.com/ollama/status/2089454609765146744
Cartesia’s Sonic 3.6 takes the #1 spot on both the Provider Voice and Controlled Voice Artificial Analysis Speech Arena leaderboards, surpassing Speechify AI’s Simba 3.2 and Alibaba’s Qwen-Audio-3.0-TTS-Plus, with Sonic 3.5 holding #2 on Controlled Voice Sonic 3.6 is the latest”
https://x.com/ArtificialAnlys/status/2089400880688976062
Qwen3.8 vs Qwen3.6 vs Gemma 4: 24GB GPU Test
https://kingy.ai/blog/qwen3-8-27b-vs-qwen3-6-27b-vs-gemma-4-31b/
Artificial Analysis Intelligence Index puts Qwen3.8-27B at DeepSeek V4-Pro and GPT 5.6 Luna performance. This is the first time a local model has scored frontier model capability. We weren’t expecting this pace of local progress anywhere near this soon.”
https://x.com/cline/status/2089425906569977896
Qwen3.8-27B is now the #1 local model in Cline after just 4 days. This ends a *4 month* streak by the previous winner Qwen2.5-Coder-7B which has been the top local model since April.”
https://x.com/cline/status/2089825294677143973
We’re releasing new Qwen3.8-27B GGUFs with 10% higher accuracy. Unsloth Dynamic V3 outperforms others by >10% on Div-300, KLD & more benchmarks. We also release 1-bit quants that retain 77% accuracy. Run on 8GB RAM. Blog:
https://t.co/tHsBexyh2K GGUF:
https://x.com/UnslothAI/status/2090103470015828184
4 days to the top.🏆Thank you to every builder who pushed Qwen3.8-27B to #1 on Cline! @cline”
https://x.com/Alibaba_Qwen/status/2089919106522976337
GLM-5.3 (Max) by @Zai_org has shifted the Pareto frontier for Code Arena: WebDev! GLM-5.3 (Max) would sit at #2 among open models (upon open weights release, and #8 overall) with 1597 pts in the Code Arena: WebDev. At $3.65/M, GLM-5.3 (Max) is on par with Qwen3.8 (Max)”
https://x.com/arena/status/2090581559262798055
Qwen 27B is the “DeepSeek moment” for open source. It matches the closed-source state-of-the-art from just a few months ago and runs on an RTX 5090. Without exaggeration, it’s a game changer.”
https://x.com/kimmonismus/status/2089740575830409700
orcarouter/Qwen3.8-27B-Uncensored-MLX · Hugging Face
https://huggingface.co/orcarouter/Qwen3.8-27B-Uncensored-MLX
turns out Qwen3.8-Max can do instance segmentation you send the image plus a class list and ask for JSON (box + closed polygon per object, both in 0-1000 coordinates) we scale those vertices to pixel space and rasterize them into instance masks”
https://x.com/skalskip92/status/2089422495631687759
Qwen3.8 27B as intelligent as Luna Max yoo”
https://x.com/populartourist/status/2089415259199029345/photo/1
We also released 1-bit Qwen3.8-27B quants which run on 8GB RAM. They retain ~77% of accuracy compared to BF16. We originally didn’t want to release them but were shocked that they worked extremely well on our internal testing!”
https://x.com/danielhanchen/status/2090119165055324518
DFlash 2 is here! Qwen3.8-27B at 70 tok/s on an M5 Max MacBook Pro. ⚡ Up to 4.6× the speed of autoregressive decoding, with the same output. This is the next generation of DFlash, seeded at Z Lab and upgraded at Inco AI. Get one more accepted token on every pass, for free!”
https://x.com/zhijianliu_/status/2089836737132650504
3000000000 downloads! Can you count the zeros at a glance? 😎 Thank you all for the incredible love. Let’s keep growing together! 🌱”
https://x.com/Alibaba_Qwen/status/2088881015855182122
Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things
https://simonwillison.net/2026/Aug/16/qwen-38-27b/
We can now RL large MoEs with 0 train-infer mismatch! And doing so can improve performance (pictured task: teach Qwen3.6-35B-A3B to play Wordle). Everything is open-source and we did a bunch of ablations. 🧵”
https://x.com/PandaAshwinee/status/2089396727048749528
Leave a Reply