Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for AGI for the week ending August 21, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
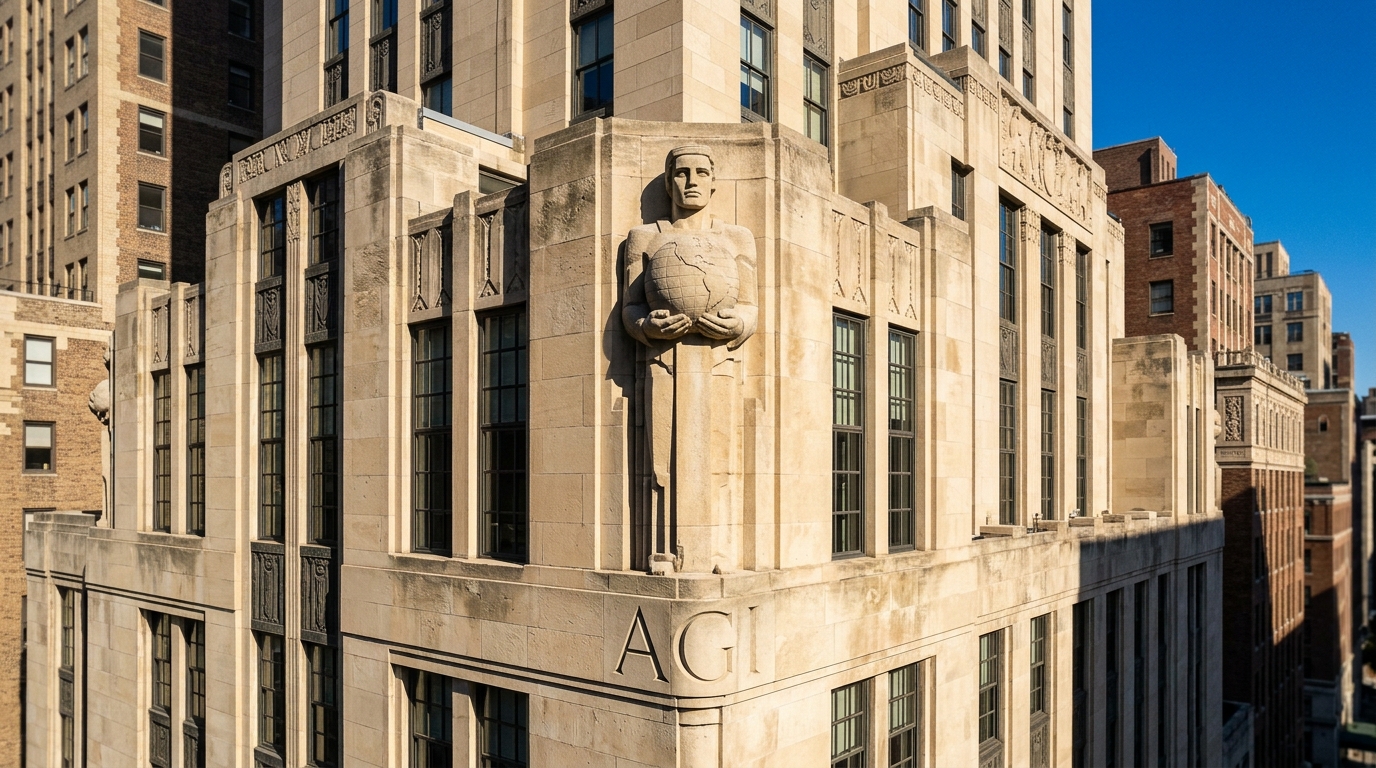
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Nano Banana 2.1.
Category Cover Image Prompt: Bright sunlit architectural photograph of a 1929 Manhattan Art Deco limestone skyscraper seen from across the street, with a single monumental stylized herm emerging from the central pier at a high setback, holding a simplified carved stone globe against its chest, flanked by narrow dark steel-framed windows and receding neighboring buildings against a deep blue sky, the word AGI incised in large Art Deco capitals into the limestone frieze band directly below the figure, crisp raking shadows across honey-cream Indiana limestone, perspective-corrected verticals, realistic architectural photography.
This Week in AGI News
Summary by Claude Sonnet 5.5 based on this week’s links:
- Self-improving agents face a reality check: A paper highlighted by DAIR.AI re-tested memory-based self-improving agents with multiple runs and shuffled task orders, and both made the gains look weaker. Meanwhile Chroma launched Foundation, a research preview that builds memory from agent sessions, and the Ornith-1.5 open models were pitched on self-improving training.
- ARC-AGI keeps rewarding efficiency: ARC Prize reported Gemini 3.7 Flash at 84.6% on ARC-AGI-2 for $0.25 per task. OpenAI said GPT-5.6 Sol rose from 13.3% to 38.3% on ARC-AGI-3 with retained reasoning and compaction, using roughly 6x fewer output tokens.
- Arguing over how seriously to take the rhetoric: Ethan Mollick questioned whether Stripe's singularity language is just marketing, then argued AI lab CEOs believed in labor replacement and existential risk before their companies were valuable. Separately, Andrew Yang proposed $15K for families as AI transforms the US economy.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to AGI
On Dwarkesh Patel’s Podcast With Ryan Greenblatt
https://thezvi.substack.com/p/on-dwarkesh-patels-podcast-with-ryan
Andrew Yang proposes $15K for families as AI transforms US economy
https://www.scrippsnews.com/politics/andrew-yang-proposes-15k-for-families-as-ai-transforms-us-economy
Either the Singularity is now a marketing term or else Stripe believes we are at a point “in the history of the race beyond which human affairs, as we know them, could not continue”? Kind of makes forward-looking financial statements useless. * Von Neumann’s original phrasing”
https://x.com/emollick/status/2090271010452881713
I’ve been looking forward to today for 3 years Today we’re announcing Foundation – Chroma’s solution to memory Our research preview of this technology builds self-improving memory from your agent sessions. Try it out at
https://x.com/jeffreyhuber/status/2090466566743974191
Ornith-1.5 is out and it serves in vLLM today. Congrats @ornith_ on a self-improving, MIT-licensed family from 9B to 397B, SOTA among open models on coding and agentic tasks. Already serving in vLLM: vllm serve ornith-ai/Ornith-1.5-9B”
https://x.com/vllm_project/status/2090243605147586955
Finally a good paper testing whether memory-based self-improving agents actually improve. The re-evaluation adds two things prior work skipped, multiple runs to measure variance and randomly shuffled task orders. Both hurt. Agent evaluation is already noisy on multi-step”
https://x.com/dair_ai/status/2090559561128407336
(60) WF2026: Autoresearch & Keynotes ft. Anthropic, Google DeepMind, Amazon AGI, Sonar, Arena, Recursive – YouTube
https://www.youtube.com/watch?v=4sX_He5c4sI
Aloha! 🌺Introducing Ornith-1.5, a family of open-source LLMs spanning 9B Dense, 35B MoE, and 397B MoE, trained with self-improving strategies. It achieves state-of-the-art performance among open-source models of comparable size and delivers performance comparable to Claude Opus”
https://x.com/ornith_/status/2090074077084127302
Gemini 3.7 Flash from @Google on ARC-AGI (Verified): – ARC-AGI-2: 84.6%, $0.25/task – ARC-AGI-1: 95.5%, $0.12/task Gemini 3.7 Flash stands out for its low cost and high scores on ARC-AGI-1 and ARC-AGI-2 relative to other frontier models.”
https://x.com/arcprize/status/2090500144550539327
great initiative (RSI benchmark) from @ScaleAILabs and @mhrezaeics”
https://x.com/alexandr_wang/status/2089759883914822033
With retained reasoning and compaction, GPT-5.6 Sol improved from 13.3% to 38.3% on ARC-AGI-3 while using roughly 6x fewer output tokens.”
https://x.com/OpenAIDevs/status/2089374232040132764
Yes, the CEOs of the AI Labs talked about building AI that would replace all labor & could pose an existential risk because, as far as I could tell, they believed it to be true long before their companies were valuable. The fact that they stopped talking about risk is the PR part”
https://x.com/emollick/status/2090593783779860928
Leave a Reply