Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for Images for the week ending August 14, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
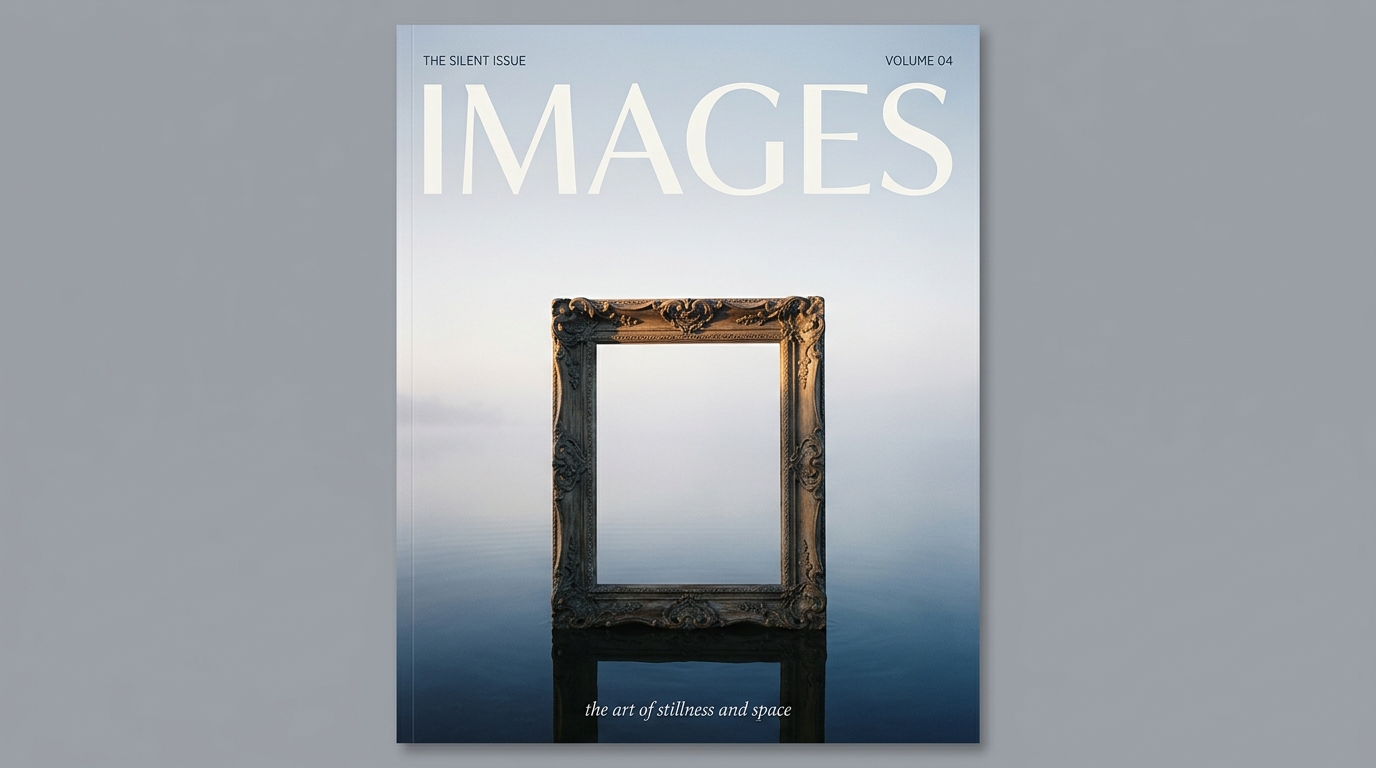
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Nano Banana 2.1.
Category Cover Image Prompt: Photorealistic magazine cover of a single ornate empty picture frame standing upright on glassy still water at early dawn, its interior filled only with pale misty sky, vast negative space of soft white and deep indigo mist, one delicate thread of warm gold light along the frame's upper edge, bold clean title text 'Images' set large in the open sky, minimalist fine-art composition, quiet symmetry, long-exposure calm.
This Week in Images News
Summary by Claude Sonnet 5.5 based on this week’s links:
- Photos and video pinned to real places: Bilawal Sidhu showed a way to turn any iPhone video, like his clip of a mama deer and her fawn, into a 3D hologram anchored where it was filmed. He is also working on locating every attributed photo taken at TED, and revisited how reconstructing the world in 3D from internet photos has progressed since Photosynth in 2008.
- Image model leaderboard moves: Microsoft AI says MAI-Image-2.6 launched at No. 2 on Arena's text-to-image ranking, ahead of Google, Meta and xAI. xAI separately released Imagine Image 2.0, offered in Grok's Quality Mode.
- Video generation tooling: Google introduced Gemini Omni Flash, the first model in its Omni family, which creates and edits video from text, image, video or audio references. Lightricks' LTX-2.5 landed in Hugging Face Diffusers, generating video and 48 kHz sound together.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to Images
What if every video you ever shot could turn into a permanent 3D hologram in the exact place it happened? I did it with photos first. Now I can do it with any video. Here’s a mama deer and her baby deer, filmed with my iphone a few days ago — now floating as geo anchored”
https://x.com/bilawalsidhu/status/2087285954218279307
What if a robot could simulate the physical world from a single image. [📍Bookmark Paper & GitHub for later] PointWorld-1B from Stanford and NVIDIA is a large 3D world model that predicts how an entire scene will move, given RGB-D input and robot actions. The key idea is”
https://x.com/IlirAliu_/status/2086151375084265842
Progress update: figuring out the 3D location of every photo taken at TED with attribution. It’s starting to feel magical — makes me wonder what experiences are possible if we could do this for every live event ever.”
https://x.com/bilawalsidhu/status/2086116653071216892
Reconstructing the world in 3D from random internet photos is a deep rabbit hole. In 2008, Photosynth proved that 3D reconstruction of smaller monuments was possible. The next year, “Building Rome in a Day” proved it could be done for entire cities. Since then, there’s been a”
https://x.com/bilawalsidhu/status/2087677694112628771
We recently introduced Gemini Omni Flash, our first model in the new Omni family. With Omni, you can easily create and edit high-quality videos from text, image, video or audio references. We recently gave developers access to it, and since then, we’ve seen builders all over the”
https://x.com/Google/status/2086814383582118356
MAI-Image-2.6 launches at No. 2 on Arena ahead of Google, Meta and xAI | Microsoft AI
https://microsoft.ai/news/mai-image-2-6-launches-at-no-2-on-arena-ahead-of-google-meta-and-xai/
MAI-Image-2.6 is now the #2 text-to-image model in the world – beating out Nano Banana, Meta, and Grok! Fantastic moment for the team who’ve been hill climbing relentlessly. Try it out now on Arena!”
https://x.com/mustafasuleyman/status/2086944832258236781
Imagine Image 2.0 | SpaceXAI
https://x.ai/news/grok-imagine-image-2
xAI launches Imagine Image 2.0 in Grok Quality Mode
https://www.testingcatalog.com/xai-launches-imagine-image-2-0-in-grok-quality-mode/
Introducing Unsloth Desktop 🦥 The first desktop app to run and train models locally. • Open-source. Runs on Mac, Windows and Linux • Supports MLX, diffusion image/video, audio, GGUF • Connect Claude Code and Codex to local LLMs • 50% more accurate, self-healing tool calls +”
https://x.com/UnslothAI/status/2087177146662072546
Deepgram Flux TTS: Conversation-Aware Text-to-Speech
https://deepgram.com/product/text-to-speech/flux
Introducing @DeepgramAI Flux TTS, a text-to-speech model built for live conversation. Voice AI is moving from demos to real customer calls, and the bar there is different. Text-to-speech needs to be able to handle the nuances of how we speak. Can it handle interruptions? A”
https://x.com/deepgramscott/status/2087533416849838386
I’m leaving Meta to start a new company. Building the TBD Lab alongside Mark @finkd and Alex @alexandr_wang has been deeply inspiring and fulfilling. I’m proud of what our multimodal team accomplished across Muse Spark, Voice Mode, Muse Image, and Muse Video, and even prouder of”
https://x.com/jiahuiyu/status/2087936732939616299?s=20
LTX-2.5 from @Lightricks is now in 🤗 Diffusers. A few cool details: > makes video + 48 kHz sound together > can pick the clip length from your prompt > uses a 2-pass mode for better quality > can render in tiles to save memory > re-compresses input images to better match”
https://x.com/RisingSayak/status/2087457946770850274
Leave a Reply