Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for Chips and Hardware for the week ending August 14, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
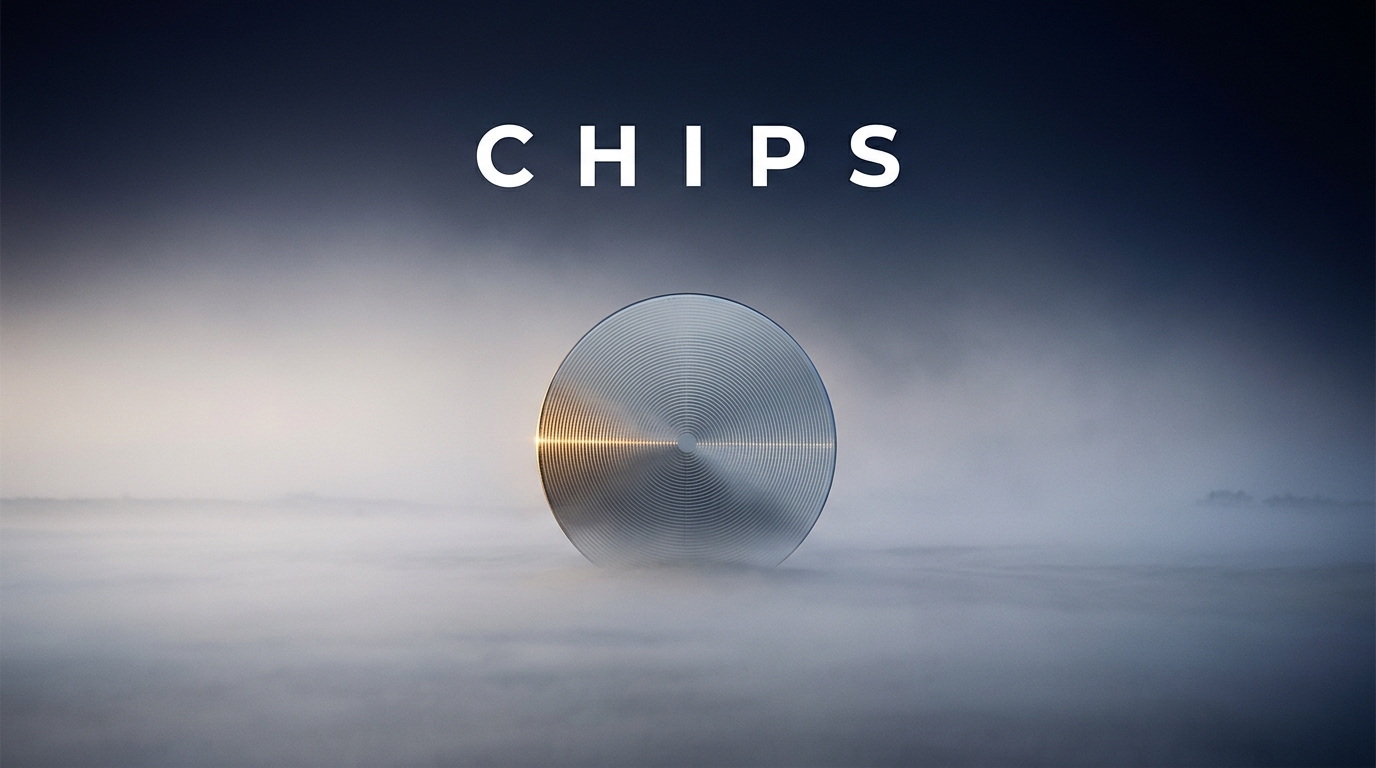
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Nano Banana 2.1.
Category Cover Image Prompt: A single circular silicon wafer standing upright and perfectly centered in vast pale dawn mist, its mirrored surface showing fine concentric circuitry catching one thin thread of warm gold light, deep cosmic indigo fading at the frame edges, photorealistic magazine-cover minimalist still life with soft diffused light and the bold title word Chips set cleanly in the empty sky above.
This Week in Chips and Hardware News
Summary by Claude Sonnet 5.5 based on this week’s links:
- Nemotron 3.5 Lightning took over the week: NVIDIA's open 30B model, with 3B active parameters, was pitched as a fast, cheap engine for always-on agents. Providers like Baseten, Together AI, Ollama and vLLM shipped it on day one, and Artificial Analysis said it roughly matches gpt-oss-120b at about a quarter of the total parameters.
- Inference tuning on NVIDIA hardware: Several posts were about squeezing more out of existing GPUs. Prime Intellect released Blackwell-optimized kernels for MoE inference, and vLLM showed Azure Blob paths for loading weights and caching KV data, with NVIDIA's Dynamo ModelExpress loader up to 7.3x faster than the default.
- Supply and cost pressure: Tom's Hardware reported NVIDIA is testing lower-memory Rubin Ultra configs, as small as 192 GB, because of the memory shortage. Epoch AI estimated a dollar buys about 49% more AI compute each year, a doubling every 21 months.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to Chips and Hardware
One day after Meta released Muse Glimmer, NVIDIA launched Nemotron 3.5 Lightning and NeMo Switchyard, showing a different approach to local agentic AI. Really cool. Lightning is a 30B MoE with only 3B active parameters, distilled from Nemotron 3 Ultra and designed for the”
https://x.com/kimmonismus/status/2087179573477650881
NVIDIA Nemotron 3.5 Lightning Delivers Fast, Accurate Specialized Task Execution for Long-Running Agents | NVIDIA Technical Blog
https://developer.nvidia.com/blog/nvidia-nemotron-3-5-lightning-delivers-fast-accurate-specialized-task-execution-for-long-running-agents/
What if a robot could simulate the physical world from a single image. [📍Bookmark Paper & GitHub for later] PointWorld-1B from Stanford and NVIDIA is a large 3D world model that predicts how an entire scene will move, given RGB-D input and robot actions. The key idea is”
https://x.com/IlirAliu_/status/2086151375084265842
WorldTrace: Addressable Memory for Video World Models
https://research.nvidia.com/labs/sil/projects/WorldTrace/
How much more AI compute does a dollar buy each year? About 49%, or a doubling every 21 months, based on the chips actually bought each quarter from 2023 through 2025.”
https://x.com/EpochAIResearch/status/2088007790296256589
NVIDIA Nemotron 3.5 Lighting is available on Ollama! It’s a 30B model made for always-on agents. All local. Claude Code ollama launch claude –model nemotron-3.5-lightning Hermes Agent ollama launch hermes –model nemotron-3.5-lightning OpenClaw ollama launch openclaw”
https://x.com/ollama/status/2087208006455111779
Nemotron 3.5 Lightning’s agentic capabilities are a step change for the Nemotron family’s small models. Its GDPval-AA v2 Elo of 824 surpasses both Nemotron 3 Super and gpt-oss-120b, while its Terminal-Bench v2.1 score of 24% is >3x Nemotron 3 Nano’s 7% and almost matches”
https://x.com/ArtificialAnlys/status/2087163522212045033
2-bit NVIDIA Nemotron 3.5 Lightning ran tool calls nonstop for 10 minutes on just 22GB of VRAM. 🤯 It cited 80+ websites, executed code & searched for 10 real-world locations. Run and train via Unsloth Desktop. GGUF:
https://t.co/PAr0nqR1CN Guide:
https://x.com/UnslothAI/status/2087598047589196052
⚡ Run Nemotron 3.5 Lightning on vLLM today! Up to 4× higher throughput and 30% faster task completion… ideal for always-on agents. With vLLM’s OpenAI-compatible API, you can drop it into your agent stack and adapt it to your tools and workflows. Also great to see the model”
https://x.com/vllm_project/status/2087217150813729122
Introducing NVIDIA Nemotron 3.5 Lightning⚡ An open 30B MoE model with 3B active parameters, built for always-on agents to complete high-volume, specialized tasks faster. It delivers up to 4x the output speed of similar-sized models.”
https://x.com/NVIDIAAI/status/2087162151995629926
Lightning strikes for continuous and long-run agents! Nemotron 3.5 Lightning is smart, fast, efficient and open.”
https://x.com/JensenHuang/status/2087184542050496763
NVIDIA Nemotron 3.5 Lightning is live on Baseten day 0! This is the fastest open model in its class, built for long-running agents. Compared to similar-sized open models, it offers: – 4x higher throughput – 50% lower cost – 63.4% fewer output tokens in production testing – 30B”
https://x.com/baseten/status/2087173719873446192
NVIDIA Nemotron 3.5 Lightning is now live on Together AI. The fastest open model in its class is built for always-on agents that need to complete high-volume, specialized work quickly.”
https://x.com/togethercompute/status/2087163477404041345
Nemotron 3.5 Lightning available to all developers on the Perplexity Agent API. Input: $0.0115 per 1M tokens Output: $0.17 per 1M tokens”
https://x.com/AravSrinivas/status/2087352727923998941
What is the RL environment to make an AI as good at politics as Lyndon Johnson, or as good at building a space launch business as Elon Musk? You can’t easily containerize such domains, and so how would even a superintelligence trained in a datacenter be competitive against”
https://x.com/dwarkesh_sp/status/2087564079695282305
We post-trained @NVIDIAAI Nemotron 3.5 Lightning on Legal Agent Bench with @trajectorylabs. Here’s what we found: 1) Post-training improved agent performance from 0% to 8.3% on held-out LAB tasks, beating both Opus 4.6 and the much larger post-trained Nemotron 3 Ultra. 2)”
https://x.com/harvey/status/2087166789876945338
🎉 Congrats to @Alibaba_Qwen on Qwen3.8-2.4T-A95B, one of the largest open-weight models released to date. 2.4T params, 95B active, 512 experts. Day-0 support in vLLM, verified on @NVIDIA and @AMD hardware. A ready-made 4-bit checkpoint per vendor, both out of the box:”
https://x.com/vllm_project/status/2087571359413281049
Nvidia Is Speedrunning the Creation of a Synthetic Hyperscaler
https://taekim.substack.com/p/nvidia-is-speedrunning-the-creation
Together AI is teaming up with @IBM and @nvidia to bring enterprise-grade AI inference to IBM Cloud. A dedicated NVIDIA B300 cluster. Spectrum-X networking. First of its kind on IBM Cloud, powered by Together’s production ready inference platform.”
https://x.com/togethercompute/status/2087200403150807073
For the same model, output speed can vary by over 15x depending on the inference provider. We’re unpacking why those differences exist and what they mean in practice on Wednesday, August 12 in San Francisco Hear directly from Artificial Analysis and leading inference providers”
https://x.com/ArtificialAnlys/status/2086958697444696113
Power 2026 by Neel Somani – Electricity Pricing in the Age of AI
https://power2026.ai/
this week in open source: – Muse-Glimmer-30B – LTX 2.5 – Nemotron 3.5-Lightning – Ling3.0-tiny – Qwen3.8-2.4T – LFM2.5-VL-3B – Wan2.2-Animate-2 – Cohere North-Micro-Vision and there’s more coming 🤭”
https://x.com/multimodalart/status/2087576052457513234
Bell Labs might be one of THE most incredible examples of what happens if you put science, engineering and capital together for a very long period of time. Their goal was to improve the American telephone network. But what came out was a mixture of MIT, DeepMind, NVIDIA, and a”
https://x.com/IlirAliu_/status/2087600503064543383
NVIDIA has just released the first Nemotron 3.5 model: Nemotron 3.5 Lightning, a highly efficient small open weights model with performance similar to gpt-oss-120b at around a quarter of the total parameters Nemotron 3.5 Lightning is the successor to @nvidia Nemotron 3 Nano 30B”
https://x.com/ArtificialAnlys/status/2087163514037408085
As always, NVIDIA Nemotron 3.5 Lightning is open and customizable. This includes weights, data and recipes. Available now on @huggingface 🤗 →”
https://x.com/NVIDIAAI/status/2087173733823680855
nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4 · Hugging Face
https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-NVFP4
excited to be releasing open weights for muse glimmer today, a 30b model that runs on a single consumer gpu, with open weights for a version of muse spark 1.2 coming soon. two very different models, both headed into people’s hands, with more to come.”
https://x.com/alexandr_wang/status/2086755368596902004
Microsoft Plans Maia 300 AI Chip Unveiling in September, Report Says
https://insideai.news/news/ai-hardware-infrastructure/microsoft-plans-maia-300-ai-chip-unveiling-in-september-report-says/7446/
Then serving. KV is expensive to compute and competes for HBM you want for batch size. Through vLLM’s KV connector, @lmcache parks blocks in Azure Blob over @NVIDIA Dynamo’s NIXL. A hit is a fetch, not a recompute. The gap grows with prompt length. 🔗”
https://x.com/vllm_project/status/2087543024213737527#m
vLLM’s model loader and KV connector both have an @Azure Blob path now: weights in, KV out. @Microsoft and @NVIDIAAI shipped a recipe for each. Nothing serves until weights land in HBM. Dynamo ModelExpress plugs into the loader, up to 7.3x faster than the default on H100/A100.”
https://x.com/vllm_project/status/2087543021844017182
Nvidia reportedly testing lower memory configs of Rubin Ultra as memory shortage bites back … designs tested include as little as 192 GB and step back to HBM4 [Updated] | Tom’s Hardware
https://www.tomshardware.com/pc-components/gpus/nvidia-reportedly-testing-lower-memory-configs-of-rubin-ultra-as-memory-shortage-bites-back-designs-tested-include-as-little-as-192-gb-and-step-back-to-hbm4
Nvidia’s Switchyard router reshuffles AI models mid-task, cutting task costs to a third in its own tests | VentureBeat
https://venturebeat.com/orchestration/nvidias-switchyard-router-reshuffles-ai-models-mid-task-cutting-task-costs-to-a-third-in-its-own-tests
Shattering NVIDIA’s Monopoly: 20x Speedup on d-Matrix’s Chip”
https://x.com/JvNixon/status/2087224880169439390
Introducing Prime Flash MoE – a set of Blackwell-optimized CUDA kernels for MoE inference. Fuses routing-aware GEMMs, SwiGLU, quantization & reductions without materializing intermediates. BF16 + MXFP8 paths, benchmarked on B200s.”
https://x.com/PrimeIntellect/status/2087969614156247504
Ultra-High Interactivity on NVIDIA GPUs? TileRT InferenceX Can TileRT software on NVIDIA GPU compete with Cerebras, Groq LPU, SambaNova? Batch Size 1, Disaggregated engine, High throughput prefill engine, High interactivity decode engine”
https://x.com/SemiAnalysis_/status/2086697535549440370
These machines don’t look like they build the future of AI. But they do. What you are seeing is not an industrial robot just move. It is part of the process that makes the world’s most advanced chips possible. TRUMPF laser systems are used to manufacture key components for”
https://x.com/IlirAliu_/status/2086360929302679702
Big Tech should have either kept calling them server farms (agricultural, quaint) or started calling them supercomputing facilities (futuristic, exciting). Data centers (why my data? why is it centralized?) was the worst possible choice.”
https://x.com/emollick/status/2086634601552781387
Leave a Reply