Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for Chips and Hardware for the week ending July 24, 2026.
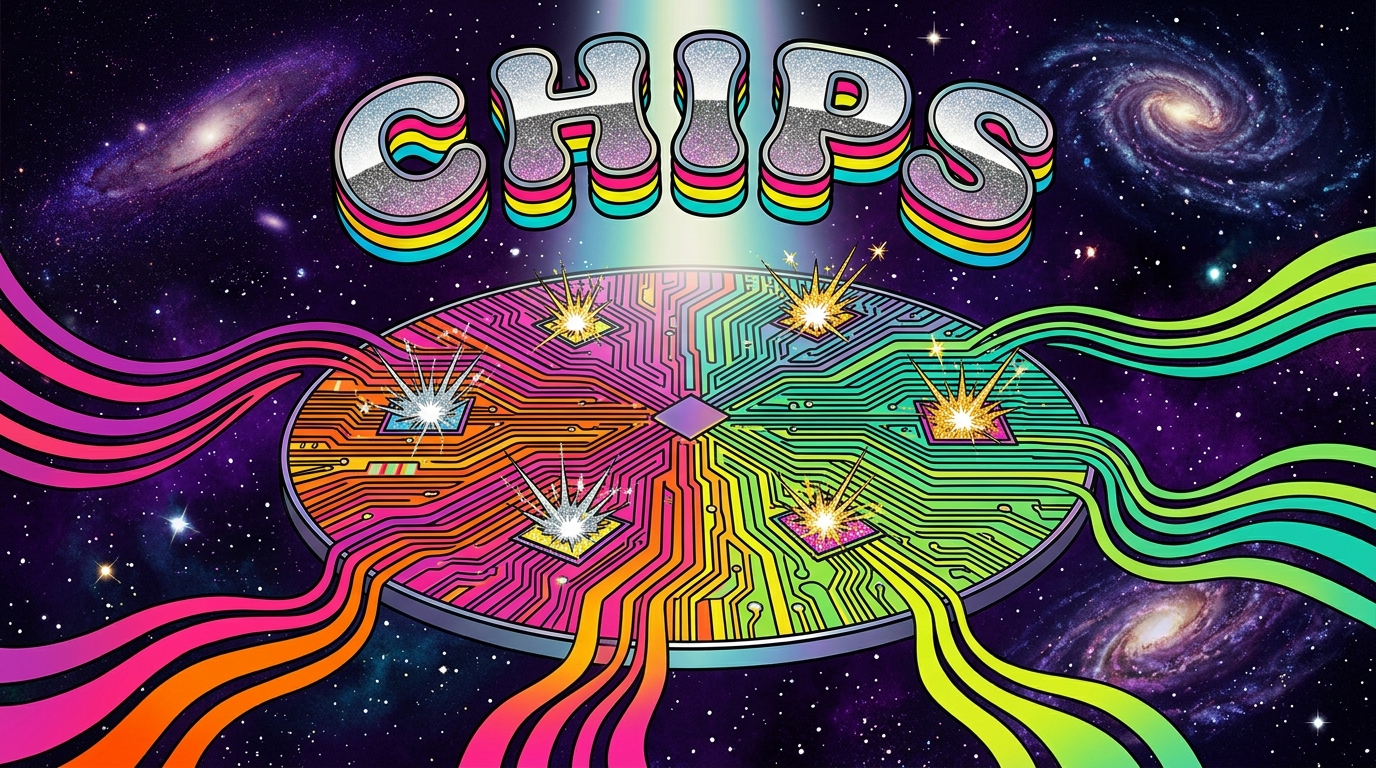
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Gemini 3.1 Flash Image Preview.
Category cover image prompt:
A single giant circular silicon wafer hovering like a glowing mothership in deep cosmic purple-black space, its microchip circuit traces flowing outward as saturated rainbow ribbons in hot magenta, electric orange, acid yellow, lime green, and turquoise, with chrome and gold sparkle starbursts popping from its die, lit by a beam from above in 1970s psychedelic Afrofuturist poster style. The word CHIPS arcs boldly across the top in fat rounded funk bubble letters with chrome and glitter fill and stacked multicolor drop shadows, dominating the composition with clear negative space and no other text or logos anywhere.
This Week in Chips and Hardware News
Here’s a quick AI-generated summary by Claude Sonnet 5.5, based on the headlines and excerpts accompanying this week’s links:
- Challengers to Nvidia: AMD had a busy week: an Anthropic deal for up to 2 gigawatts of MI450 GPUs, Microsoft signing on to its Helios rack system, and an inference tie-up with Cerebras. Alibaba also open-sourced its AI chip software stack, aimed at Nvidia's CUDA lock-in.
- China goes domestic: Z.AI finished a 1-gigawatt data center built entirely on Chinese-made chips, per Bloomberg and Yahoo Finance. Separately, DeepSeek's claim about training on Huawei chips reportedly got its benchmarks, along with some doubters.
- Compute is the bottleneck: Kimi K3 sold out after hitting a GPU limit, and one analysis argues a GPU-hour is not a commodity if you need four of them. Google, meanwhile, is reportedly working on a new chip to make Gemini cheaper to run.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to Chips and Hardware
Thinking Machines Lab’s Inkling scores an Elo of 836 on on our agentic knowledge work benchmark AA-Briefcase, ahead of DeepSeek V4 Flash but below leading open weights models including Nemotron 3 Ultra and GLM-5.2 Our new agentic knowledge work benchmark, AA-Briefcase, tests”
https://x.com/ArtificialAnlys/status/2080036845161730284
AMD and Anthropic Announce Strategic Partnership to Deploy Up to 2 Gigawatts of AMD Instinct MI450 Series GPUs :: Advanced Micro Devices, Inc. (AMD)
https://ir.amd.com/news-events/press-releases/detail/1292/amd-and-anthropic-announce-strategic-partnership-to-deploy-up-to-2-gigawatts-of-amd-instinct-mi450-series-gpus
The new 4-step Cosmos 3 Super models generate images and video up to 25x faster than the originals, and still rank among the best open-weight models on @ArtificialAnlys. 🥇 #1 for image-to-video (no audio) 🥈 #2 for text-to-image Try them on @huggingface:”
https://x.com/NVIDIAAI/status/2079949373069197658
NVIDIA’s Cosmos3 Edge is out! it watches videos streams & understands the mechanics/physics in them 🔥 it can reason in words, images, or next action prediction. physical AI reasoning, on the edge. try it on @huggingface (or on your edge device) ▶️
https://x.com/HuggingApps/status/2079923165157859362
Introducing Cosmos 3 Edge
https://huggingface.co/blog/nvidia/cosmos3edge
Google is working on a new AI chip designed to make Gemini more efficient | TechCrunch
https://techcrunch.com/2026/07/20/google-is-working-on-a-new-ai-chip-designed-to-make-gemini-more-efficient/
Google Plans New ‘Frozen’ Chip to Run Its AI Models Much More Efficiently … The Information
https://www.theinformation.com/articles/google-plans-new-frozen-chip-run-ai-models-efficiently
The State of Simulation for Physical AI: An Overview
https://huggingface.co/blog/nvidia/state-of-simulation-for-physical-ai
MAI-Voice-2-Flash launches today! Flash is 2x faster than MAI-Voice-2 and 32% cheaper, at $15 per 1M characters. MAI-Voice-2-Flash is also in public preview and powers Dynamics 365 Contact Center, our enterprise platform for call center agents, and reduces GPU costs up to 89%.”
https://x.com/mustafasuleyman/status/2080336147256127960
Every engineer needs a devbox, tailor-made for the task at hand. Devin is no different. With Outposts, Devin’s work can run in the fast-booting, elastic, GPU-backed sandboxes you’re used to.”
https://x.com/modal/status/2079670707852652775
Must-read papers of the week ▪️ Harness Handbook: Making Evolving Agent Harnesses Readable, Navigable, and Editable ▪️ SearchOS-V1 ▪️ KnowAct-GUIClaw ▪️ LongStraw: Long-Context RL Beyond 2M Tokens under a Fixed GPU Budget ▪️ SEED: Self-Evolving On-Policy Distillation for Agentic”
https://x.com/TheTuringPost/status/2079385322933354619
Today we are releasing Laguna S 2.1. At 118B total parameters, with 8B active per token, it does the work of models several times its size on agentic coding. It is remarkably persistent across long-horizon tasks. And it is small enough to run on a single NVIDIA DGX Spark. It is”
https://x.com/eisokant/status/2079612416967491952
Devin Outposts are now available on NVIDIA Brev. Write and profile kernels, run experiments, serve and fine-tune OSS models, and test against real hardware. Try it out:”
https://x.com/NVIDIAAI/status/2079630151206506525
OpenResearch from @askalphaxiv runs experiments on your own code and compute Each experiment gets an isolated worktree, @wandb backed runs, and a graph showing how the research branches and progresses /reproduce-paper <paper URL or title> on <compute>”
https://x.com/_ScottCondron/status/2079881045764149397
Alibaba open-sources its AI chip software stack at WAIC, targeting Nvidia’s CUDA lock-in
https://thenextweb.com/news/alibaba-t-head-sail-open-source-nvidia-cuda-alternative
My morning ritual: coffee, then watch our robot assemble stuff. The model isn’t fast, but it measures every grasp, obsesses over every alignment, and handles every piece like an heirloom. Watching is therapeutic, even meditative. Simple pleasure from the execution of a task well”
https://x.com/DrJimFan/status/2078150032575082616
Update: the 1.5x limits promo just got quietly extended to Aug 19 (page updated an hour ago lol). Good move – this stops the 20 (now 10x) and 5 (now 2.5x) plans from becoming the 6.67x and 1.67x plans for another month. Someone found anthropic some compute.”
https://x.com/bilawalsidhu/status/2078532647974744522
DeepSeek’s Huawei-Chip Training Claim Gets Its Benchmarks
https://www.implicator.ai/deepseeks-huawei-chip-training-claim-finally-gets-its-benchmarks-and-its-doubters/
Why the first GPU financiers are turning to inference chips in a $400 million deal | TechCrunch
https://techcrunch.com/2026/07/17/why-the-first-gpu-financiers-are-turning-to-inference-chips-in-a-400-million-deal/
TSMC is accelerating Arizona fab buildout to capitalize on AI demand: CFO
https://www.cnbc.com/2026/07/20/tsmc-arizona-fab-capacity-ai-chip-demand.html
AMD Helios: Microsoft signs on to rack AI system that rivals Nvidia
https://www.cnbc.com/2026/07/20/amd-helios-microsoft-ai-nvidia.html
I am confused about the belief that if open weights eventually dominate it will lead to the collapse of AI. If the Labs lose (which is not happening now), it isn’t because AI was useless: compute is still the barrier & compute providers will capture the value rather than Labs.”
https://x.com/emollick/status/2078274765475709035
Industrial robotics is not only a hardware story. A lot of adoption depends on what happens around the robot: how it is programmed, simulated, commissioned, maintained and scaled across more than one application. That is why operating systems for robots matter more than they”
https://x.com/IlirAliu_/status/2079113182581326156
A GPU-Hour Isn’t a Commodity If You Need Four of Them
https://davefriedman.substack.com/p/a-gpu-hour-isnt-a-commodity-if-you
AMD and Cerebras Launch AI Inference Solution
https://www.cerebras.ai/press-release/amd-and-cerebras-announce-industry-leading-ultra-low-latency-and-high-throughput-ai-inference
Nobody knows what a used GPU cluster is worth
https://ciphertalk.substack.com/p/nobody-knows-what-a-used-gpu-cluster
Intel (INTC) earnings report Q2 2026
https://www.cnbc.com/2026/07/23/intel-intc-earnings-report-q2-2026.html?taid=6a6274f310d75400018f0789
Save this if you work with local AI 10 Small Language Models (SLMs) you should know in 2026 ▪️ GPT-5.4 mini and nano ▪️ Gemma 4 ▪️ Ministral 3 ▪️ Nemotron 3 Nano ▪️ Microsoft Phi-4 ▪️ Tiny Aya ▪️ IBM Granite 4.1 ▪️ Qwen3 small models ▪️ SmolLM3 ▪️ North Mini Code We put”
https://x.com/TheTuringPost/status/2078818495220126122
Kimi K3 hit a GPU limit That’s why we saw its sellout that says a lot about where the real bottlenecks are Model capability (yesterday) → Compute/GPUs (today) → Permission (next?)”
https://x.com/TheTuringPost/status/2079727735530815953
Jensen Huang: “I think the technology is ready and it could be useful, so I really do hope somebody in Japan creates the world’s most lovable humanoid robot again.” News from Japan this week: amid soaring memory prices, NVIDIA introduced smaller Jetson Thor modules. New Jetson”
https://x.com/TheHumanoidHub/status/2078289582420803693
China’s Z.AI Completes 1-Gigawatt AI Data Center Using Only Chinese-Made Chips
https://finance.yahoo.com/technology/ai/articles/chinas-z-ai-completes-1-205515769.html
Z.AI to Use Only Chinese AI Chips at New Giant Data Center – Bloomberg
https://www.bloomberg.com/news/articles/2026-07-20/z-ai-completes-giant-data-center-with-chinese-chips-to-train-ai
Another great open model! Congrats to the team @poolsideai”
https://x.com/ctnzr/status/2079697233843568825
Gigatoken is absurdly fast! Thanks to Marcel, I will (hopefully) never have to wait for tokenization again. It turns out that even mature components like tokenizers have order-of-magnitude improvements left if you get close to the hardware and write state machines.”
https://x.com/tatsu_hashimoto/status/2079666241099477344


Leave a Reply