Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for Audio for the week ending July 24, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
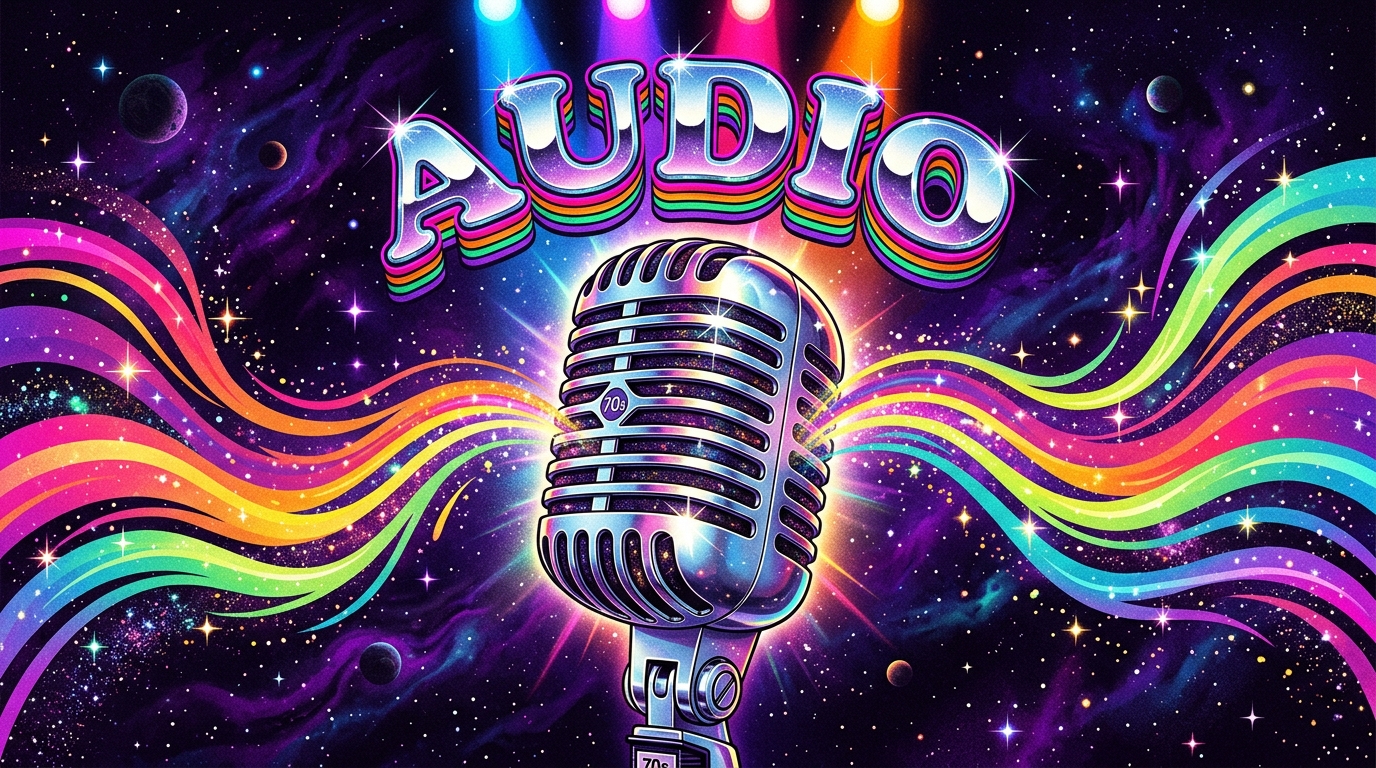
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Gemini 3.1 Flash Image Preview.
Category cover image prompt:
A giant chrome 1970s vocal microphone floating in deep cosmic purple-black space, glowing like a mothership with rainbow ribbons of sound rippling outward from its grille in saturated magenta, orange, yellow, lime, turquoise, and violet waves punctuated by starburst sparkles, with the word AUDIO arcing above in fat bubble chrome letters with stacked multicolor drop shadows and glitter sparkle, Afrofuturist psychedelic funk concert poster style, one clear central subject, strong negative space, vivid stage lighting from above.
This Week in Audio News
Here’s a quick AI-generated summary by Claude Sonnet 5.5, based on the headlines and excerpts accompanying this week’s links:
- Voice moves into coding agents: OpenAI put ChatGPT Voice in the desktop app, powered by GPT-Live, so you can direct agents in ChatGPT Work or Codex by speaking. A Codex developer described talking to it mid-task to check progress, interrupt, or start another thread.
- Claude's voice mode gets an upgrade: Anthropic says voice mode now runs on Claude's more capable models, reaches connected tools mid-conversation, and supports many more languages. Karpathy separately described using /voice for long rambling sessions to give an LLM more context than he would bother to type.
- Speech models keep getting cheaper and finer-grained: Microsoft's MAI-Voice-2-Flash is 2x faster and 32% cheaper than its predecessor, at $15 per 1M characters. Alibaba's Qwen-Audio-3.0-TTS adds inline tags like [whisper] and [laughs] to steer delivery, and WordVoice TTS offers per-word control of duration, loudness and pitch.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to Audio
ChatGPT Voice is now in the desktop app. Control your computer and direct multiple agents running in ChatGPT Work or Codex, using just your voice. It’s powered by GPT-Live, so it can speak, listen, and coordinate work in the app at the same time. Rolling out globally today”
https://x.com/OpenAI/status/2080378182469857576
ChatGPT Voice is now in the desktop app. Control your computer and direct multiple agents running in ChatGPT Work or Codex, using just your voice. It’s powered by GPT-Live, so it can speak, listen, and coordinate work in the app at the same time. Rolling out globally today”
https://x.com/OpenAI/status/2080378182469857576?s=20
voice controlling chatgpt work and codex agents at the same time one of those features that changes how you think software should work”
https://x.com/whoiskatrin/status/2080383603024785629
Claude’s Voice Mode Just Got Smarter
https://www.engadget.com/2221938/claude-voice-mode-just-got-smarter/
Voice mode now runs on Claude’s more capable models and reaches the tools you’ve connected mid-conversation. Talk through the hard problems out loud, in many more languages.”
https://x.com/claudeai/status/2080376094939603366
The new 4-step Cosmos 3 Super models generate images and video up to 25x faster than the originals, and still rank among the best open-weight models on @ArtificialAnlys. 🥇 #1 for image-to-video (no audio) 🥈 #2 for text-to-image Try them on @huggingface:”
https://x.com/NVIDIAAI/status/2079949373069197658
FLUX 3: Multimodal Video, Image & Audio | Black Forest Labs
https://bfl.ai/blog/flux-3
MAI-Voice-2-Flash launches today! Flash is 2x faster than MAI-Voice-2 and 32% cheaper, at $15 per 1M characters. MAI-Voice-2-Flash is also in public preview and powers Dynamics 365 Contact Center, our enterprise platform for call center agents, and reduces GPU costs up to 89%.”
https://x.com/mustafasuleyman/status/2080336147256127960
Agentic coding goes hands-free as OpenAI brings GPT-Live’s full duplex voice control to Codex and ChatGPT on the desktop | VentureBeat
https://venturebeat.com/orchestration/agentic-coding-goes-hands-free-as-openai-brings-gpt-lives-full-duplex-voice-control-to-codex-and-chatgpt-on-the-desktop
voice in Codex is pretty wild! you can now literally talk to Codex while it works – kick off tasks, check progress, interrupt it, change direction, or start another thread without going back to typing feels especially useful when you’re figuring things out as you build excited”
https://x.com/reach_vb/status/2080385130145759575
Introducing the Qwen-Audio-3.0-TTS. Our latest text-to-speech model, in two flavors: • Flash: real-time interaction • Plus: high-quality generation What’s new: • Fine-grained inline tags-steer [whisper], [angry], [breaths] & [laughs] • Free-style natural-language”
https://x.com/Alibaba_Qwen/status/2080270065547809133
We (@bshlgrs and I) recorded a podcast about the OpenAI / Hugging Face incident. We discuss: – What we actually know. – How surprising the incident was. – What the incident does (and doesn’t) tell us about misalignment risk. – Why control measures didn’t catch or prevent this.”
https://x.com/RyanGreenblatt/status/2080348061726089220
One pattern I find useful for working with LLMs is a nice long ramble session. Sometimes the LLM needs more bits to understand what you’re trying to achieve, but you’re too lazy to type them. In these cases I like to lean back, switch to /voice and just ramble for like 10″
https://x.com/karpathy/status/2079610838143623371
Show this to researchers, PhD students, factory managers, heads of automation, and VCs investing in robotics and physical AI. I’m expanding my newsletter, and I need their voice in it. Can you do this for my dear beloved algorithm? If you’re working on something in robotics,”
https://x.com/IlirAliu_/status/2078178418500190356
Introducing FLUX 3. One multi-modal model for Image, Video, Audio and Action-Prediction. Creations are truer to life in every kind of style. FLUX 3 Video is now available in early access (link below). Jointly trained in one unified architecture, our model can be extended to”
https://x.com/bfl_ai/status/2080308988961554582
Introducing MAI-Image-2.5-Pro and MAI-Voice-2-Flash | Microsoft AI
https://microsoft.ai/news/introducing-mai-image-2-5-pro-and-mai-voice-2-flash/
A Chinese company just revealed this autonomous robot toilet It literally drives itself to you when you summon it by voice or remote What a time to be alive”
https://x.com/rowancheung/status/2079230632534933961
Humanoid motion planning has a brutal reality check: A plan can look good in an LLM or search tree and still be physically impossible for the robot. 🎧🎙️That is exactly why I’m excited for tomorrow’s podcast episode with Majid Khadiv. His group just published FARO, a framework”
https://x.com/IlirAliu_/status/2079989774928974235
I’m really confused. OpenAI employees posted so many cryptic hype posts today as if GPT-6 was being launched. And then it’s just voice mode and new folders in the codex? I’m really confused. Or am I missing something?”
https://x.com/kimmonismus/status/2080382455240860066
voice makes you feel just how unnatural it is to type”
https://x.com/gdb/status/2080414383352529085
WordVoice TTS ships what I’ve always wanted: a TTS system with per word control you can let the system auto-pilot (based on CosyVoice3) or control every word with duration, loudness, pitch or tone works with cloned or pre-set voices ▶️ on spaces
https://x.com/HuggingApps/status/2080330151775072537


Leave a Reply