Every week, I organize 400 to 700 links into roughly 60 categories as part of my ongoing effort to learn about AI. This is my personal notebook, which I enjoy sharing with friends… a hobby and a labor of love, rather than a commercial publication or product.
If you arrived here through a search or shared link, this page collects the links I found for Multimodal for the week ending July 31, 2026.
As part of my learning process, I like to automate the category covers. It gives me a chance to learn Python and APIs.
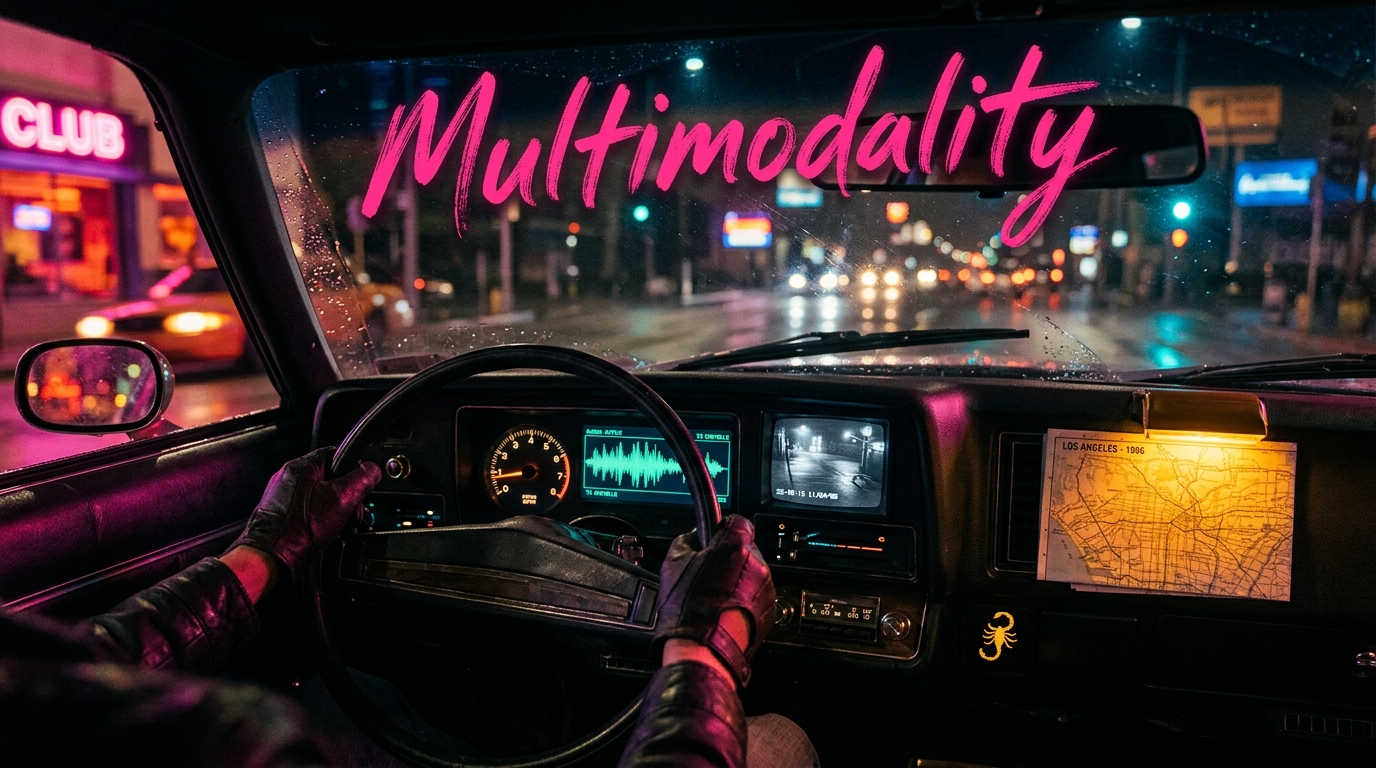
This week’s cover prompt was written using Claude Opus 4.7, and the image was generated using Gemini 3.1 Flash Image Preview.
Category Cover Image Prompt: Cinematic 1980s neo-noir interior view of a 1973 Chevelle dashboard at night, anonymous gloved hands on the steering wheel, instrument cluster blending an analog tachometer, a glowing teal audio waveform screen, a tiny CRT showing a grainy surveillance feed, a folded paper map lit by sodium-vapor amber, and a thermal-hued side mirror reflection, a small golden-yellow enamel scorpion pin on the dash, hot magenta pink and amber light, wet asphalt visible through the windshield, 35mm anamorphic grain with soft halation, the title Multimodality scrawled in hot magenta-pink handwritten brush script in the upper third.
This Week in Multimodal News
Summary by Claude Sonnet 5.5 based on this week’s links:
- Inkling-Small lands everywhere: Thinking Machines released Inkling-Small, a 276B model with 12B active parameters and native image and audio input. It shipped with same-day support in vLLM and Modal, plus an Unsloth GGUF that runs locally on 128GB RAM.
- World models for robots: World Labs and SceniX shared early results on building simulated worlds to train and evaluate robots, aimed at robotics' data shortage. Reka's WorldModelGym leaderboard tests whether a model can pick the action that leads to the best outcome, not just generate realistic video.
- Humanoid control and video prediction: Google DeepMind says Gemini Robotics 2 can control a humanoid's whole body, from walking to five-fingered manipulation. Separately, Mimic's FLUX-mimic argues robot control reduces to video prediction, built on Black Forest Labs' FLUX 3 video model.
This summary was generated by Claude Sonnet 5.5 to help you explore the links below. Rest assured, I select, organize, and check the links by hand in Google Sheets, and write the introduction and personal commentary in The Main Newsletters myself each week as a labor of love.
This week's links related to Multimodal
🎉 Congrats to @thinkymachines on Inkling-Small– live with Day 0 vLLM support! 276B total parameters with 12B active, native text, image, and audio input, and a 1M-token context window. Open weights, built for agentic and tool-use systems, coding assistants, and RAG. Running”
https://x.com/vllm_project/status/2082890823667237027
Deeply proud of what the SceniX team has built and excited to take it forward at @theworldlabs. Our real-to-sim-to-real platform enables scalable robot training and evaluation in worlds aligned with reality. This is an important milestone, and only the beginning. 🌎🤖”
https://x.com/YunzhuLiYZ/status/2082139032398492089
Slowing down AI is a ultimately wishful thinking The genie is out of the bottle The most importan competition ever with potentially immeasurable benefits to the winner will not suddenly have people stop and sing kumbaya While many lab employees have signed, many more havent.”
https://x.com/dylan522p/status/2082321388736581641
When SceniX joined World Labs, we said spatial intelligence was never only about perceiving and generating virtual and physical worlds, but also interacting with them. Today, we’re sharing early results from that vision: building worlds that train robots. 🌎🤖↓”
https://x.com/drfeifei/status/2082137335052075298
OpenAI has released GPT Transcribe: a Speech to Text model scoring 3.31% on AA-WER (#9), improving 0.7 p.p. over its predecessor GPT-4o Transcribe while lowering price 25% to $4.50 per 1,000 minutes of audio GPT Transcribe is OpenAI’s latest non-streaming (batch) speech”
https://x.com/ArtificialAnlys/status/2082285338509418727
You can now run Inkling-Small, a new 276B model by Thinking Machines. Inkling-Small is the strongest open model for its size and runs local on 128GB RAM. Apache-2.0 Licensed, it has image, audio + 1M context support. Guide:
https://t.co/mwyyMtrtA9 GGUF:
https://x.com/UnslothAI/status/2082899798047563984
Day 0 support for Inkling-Small on Modal. – 276B parameter MoE with 12B active – 1M context – Variable thinking effort – Native image & audio understanding – NVFP4 checkpoint fits on a single @NVIDIAAI B300 Great to work with @thinkymachines and @sgl_project on this one.”
https://x.com/modal/status/2082896815716712726
just to clarify: Gemma 4 models have been downloaded 300M+ times, the Gemma open model series as a whole has been downloaded an incredible 900M+ times!!”
https://x.com/demishassabis/status/2081075346208600103?s=20
Really cool: Google DeepMind says Gemini Robotics 2 can control a humanoid’s entire body, from walking and crouching to manipulating objects with five-fingered hands. The system combines three models: Gemini Robotics 2 converts vision and instructions into movement. -ER 2 plans”
https://x.com/kimmonismus/status/2082879395149074629
My conversation with Kanishka Rao, who went from working on particle physics at CERN to driving robotics at @GoogleDeepMind. We get into the Gemini Robotics 2 release, trending training recipes in the industry, physical AGI, world models, and more. 1:00 Intro 1:47 Does AI’s”
https://x.com/TheHumanoidHub/status/2082852800011395232
I think most people, when talking about open weights models, don’t deeply believe in the vision of AGI/ASI that lab insiders believe in. Like they don’t expect AI to really present grave semi-autonomous biosecurity or other similar risks. Whether it is right or not, no one knows,”
https://x.com/emollick/status/2081185596488241507
Agents that understand their environment (i.e., agentic world models) are both higher performing and more efficient at inference time. After reading many recent papers on world modeling for language agents, the main finding is that incorporating a world modeling objective into”
https://x.com/cwolferesearch/status/2082159833625788591
Here’s how we can progressively build from supervised training to RL, agentic RL, and finally a unified RL + world modeling objective… Each of the steps mentioned above is outlined in greater detail below. An implementation of each step in PyTorch is provided in the attached”
https://x.com/cwolferesearch/status/2080744109690507316
Today we’re opening the WorldModelGym leaderboard 📊 Most world model evals ask one question: does the generated video look real? WMGym asks a different one. Give a model a menu of possible actions, can it correctly predict which one actually leads to the best outcome?🎯 We”
https://x.com/RekaAILabs/status/2082089778514944023
We are releasing WorldDiT, a unified architecture for robotics world modeling and control. On the LIBERO benchmark, it performs the best among all publicly released methods that do not need a VLM to generate actions. Its size and performance sit on the reported Pareto frontier.”
https://x.com/bageldotcom/status/2082179134336512366
Video prediction beats VLAs at robot control Swiss robotics company Mimic unveiled FLUX-mimic, a Video-Action Model built on Black Forest Labs’ new FLUX 3 video model. The thesis: control reduces to video prediction. A generative video model already learns physics, semantics,”
https://x.com/TheHumanoidHub/status/2080687343783362827
World Labs CEO Dr. Fei-Fei Li & SceniX Co-Founder Yunzhu Li on the data bottleneck in robotics and how world models help: “The lack of data in training, the lack of data in evaluation, this is very, very different from language models, where data is abundant on the internet.
https://x.com/a16z/status/2082146986523046216
Like Inkling, it’s natively multimodal. It’s encoder-free, with audio and images processed jointly with text. It nearly matches Inkling across multimodal evals, and it can use Python to crop, zoom, and inspect images while reasoning over documents and charts.”
https://x.com/thinkymachines/status/2082885874845725106
Your robot policy doesn’t need 7B parameters. Train it on a standard high-end gaming GPU: Patch Policy is showing that robot control policies can achieve strong performance using dense patch features from a frozen pretrained ViT vision backbone fed into a small transformer,”
https://x.com/IlirAliu_/status/2080562657782816805
Gemini Live API overview | Gemini API | Google AI for Developers
https://ai.google.dev/gemini-api/docs/live-api?linkId=63011869
Glad to see Google sharing data on how Gemini is being used. Especially interesting is that the usefulness of multimodal AI for manual labor may be greater than expected.
https://x.com/emollick/status/2080511836491747657
Google DeepMind’s Kanishka Rao on the biggest blind spot in today’s robots: they’re all vision-based with no sense of touch. He thinks vision-only dexterity works, until it hits a wall.”
https://x.com/TheHumanoidHub/status/2082884792476180531
Microsoft just dropped Mage-VL 4B on Hugging Face an efficient codec-native streaming VLM that describes live events as they happen, and you can prompt it for the moment you care about. e.g.: when the train arrives 🚂, when there’s a goal ⚽ ▶️ on spaces
https://x.com/HuggingApps/status/2081698703262265520
Releasing the model weights and technical report of Kimi K3. Kimi K3 is our most capable model: a 2.8T MoE model with native visual understanding and a 1M-token context window. New model architecture: 2.5x the intelligence per unit of compute, not just more params. Alongside”
https://x.com/Kimi_Moonshot/status/2081760186235289764
Mage … A Lightweight, Research-Friendly Multimodal Model Family
https://microsoft.github.io/Mage/
That work will change around AI is inevitable, but the way work changes is not. I think firms with a lack of imagination will see AI as an opportunity to cut people, but firms with the vision to expand human roles & make them better with AI will thrive.”
https://x.com/emollick/status/2082502289898508640
Interesting, instead of initializing the vision encoder with pretrained weights, the vision encoder is now jointly trained from scratch along with the rest of the model. This apparently improves training stability.”
https://x.com/iScienceLuvr/status/2081771730763473121


Leave a Reply