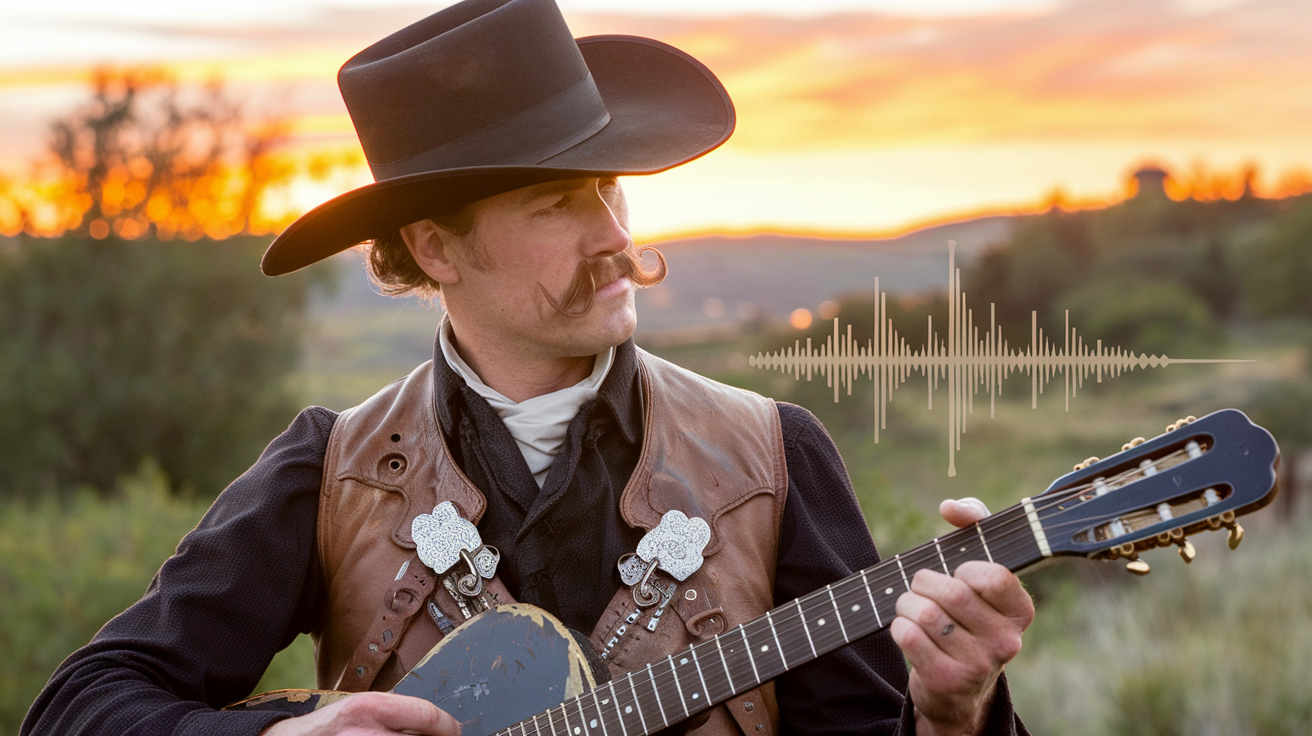
“So cool. Drop your chatgpt image generations into @hedra_labs and bring them to life! All you need to provide is an image of the character + audio file of the dialogue.” / X https://x.com/bilawalsidhu/status/1905394558726193474
“MiniMax released Speech-02, a new text-to-speech AI model It can generate ultra-realistic speech in over 30 languages, helping teams create audiobooks and podcasts Users can get up to 200k characters in a single input https://x.com/rowancheung/status/1907304683795775845
Zyphra https://www.zyphra.com/post/beta-release-of-zonos-v0-1
OmniTalker: Real-Time Text-Driven Talking Head Generation with In-Context Audio-Visual Style Replication https://humanaigc.github.io/omnitalker/
MiniMax Audio: Create lifelike speech https://www.minimax.io/audio
“The new OpenAI realtime transcription API now supports WebRTC connections, which allows you to easily connect a MediaStream or <audio> element to the API. Just made a quick demo to show this off – try it out at https://x.com/juberti/status/1906864981951598858
“Crazy that GPT-2 is still pulling in over 22M downloads in the last 30 days on @huggingface—plus strong activity from Whisper and CLIP-ViT! https://x.com/fdaudens/status/1906807591537148410
“Alibaba dropped Qwen2.5-Omni-7B, a new multimodal AI —Processes across text, audio, image, and video in real-time —Text and speech outputs —Strong speech understanding, outperforms specialized audio models —Can run on phones, laptops —Open-source https://x.com/rowancheung/status/1905130218433450119
Brain-to-voice neuroprosthesis restores naturalistic speech – Berkeley Engineering https://engineering.berkeley.edu/news/2025/03/brain-to-voice-neuroprosthesis-restores-naturalistic-speech/
“Introducing TTSTSTT, a breakthrough new AI model architecture. Unlike prior LLM architectures trained entirely on text tokens, Text To Speech To Speech To Text (TTSTSTT) models are trained to perform reasoning entirely within the auditory domain, but also have conversions to text https://x.com/juberti/status/1907180245687669160
[2502.03382] High-Fidelity Simultaneous Speech-To-Speech Translation https://arxiv.org/abs/2502.03382



