“ChatGPT’s new Projects feature can organize your AI clutter | TechRadar”
https://www.techradar.com/computing/artificial-intelligence/chatgpts-new-projects-feature-can-organize-your-ai-clutter
“New verified ARC-AGI-Pub SoTA! @OpenAI o3 has scored a breakthrough 75.7% on the ARC-AGI Semi-Private Evaluation. And a high-compute o3 configuration (not eligible for ARC-AGI-Pub) scored 87.5% on the Semi-Private Eval. 1/4
https://x.com/arcprize/status/1870169260850573333
“Breaking news! Alec Radford departs OpenAI! As one of their star researchers, he was first author on GPT, GPT-2, CLIP, and Whisper papers.
https://x.com/iScienceLuvr/status/1869852854728700166
OpenAI o3 and o3-mini—12 Days of OpenAI: Day 12 – YouTube
“o3-mini is here! Together with @shengjia_zhao, @_kevinlu, @max_a_schwarzer, @ericmitchellai, @brian_zq, @sandersted and many others, we trained this efficient reasoning model, maximally compressing the intelligence from big brothers o1 / o3. The model is very good in hard
https://x.com/ren_hongyu/status/1870208580135100750
“Excited to train o3-mini with @ren_hongyu @_kevinlu and others, a blindingly fast model with amazing reasoning / code / math performance.
https://x.com/shengjia_zhao/status/1870176031610667223
“@OpenAI You can sign up to help red team o3 and o3-mini here:
https://x.com/polynoamial/status/1870175700222628164
“Google DeepMind announced a strategic partnership with Apptronik, an Austin-based humanoid robotics company The partnership will leverage Google DeepMind’s AI expertise, including their Gemini models, to enhance robot capabilities in real-world environments
https://x.com/adcock_brett/status/1870877962251260290
OpenAI trained o1 and o3 to ‘think’ about its safety policy | TechCrunch
“This is real – the OpenAI website already has references to “O3 Mini Safety Testing Call” form
https://x.com/btibor91/status/1870022347349987532
Early access for safety testing | OpenAI
https://openai.com/index/early-access-for-safety-testing/
“Along with the o3 announcement OpenAI also dropped a cute little paper: “Deliberative Alignment: Reasoning Enables Safer Language Models” The paper introduces a new training approach for LLMs called “Deliberative Alignment.” This method teaches the model safety specifications
https://x.com/scaling01/status/1870177841687777685
“Chain-of-thought reasoning provides a natural avenue for improving model safety. Today we are publishing a paper on how we train the “o” series of models to think carefully through unsafe prompts:
https://x.com/Eric_Wallace_/status/1870176920706658692
“if you are a safety researcher, please consider applying to help test o3-mini and o3. excited to get these out for general availability soon. extremely proud of all of openai for the work and ingenuity that went into creating these models; they are great.” / X
https://x.com/sama/status/1870176283851903152
“OpenAI’s o3 is absolutely incredible, and I am so excited about it, but its nowhere near to AGI. “early data points suggest that the upcoming ARC-AGI-2 benchmark will still pose a significant challenge to o3, potentially reducing its score to under 30% even at high compute
https://x.com/rohanpaul_ai/status/1870575885696598152
“Independent evaluations of OpenAI’s o3 suggest that it passed benchmarks that were previously considered far out of reach for AI including achieving a score on ARC-AGI that was associated with actually achieving AGI (though the creators of the benchmark don’t think it o3 is AGI)” / X
https://x.com/emollick/status/1870172935064818045
“OpenAI announced ‘o3’, the next iteration of o1 that surpasses it across all benchmarks Pretty incredible to see o3 topping 85% on the ARC-AGI benchmark It’s currently only available in preview to safety and security researchers
https://x.com/adcock_brett/status/1870877753081217359
“🧭 As o3 tackles ARC-AGI’s Semi-Private Evaluation, here’s what this benchmark is about: Created by @fchollet, it tests AI’s ability to solve puzzles it’s never seen before—using only basic human priors like geometry & counting. It strips away language & cultural knowledge.
https://x.com/fdaudens/status/1870539776610472002
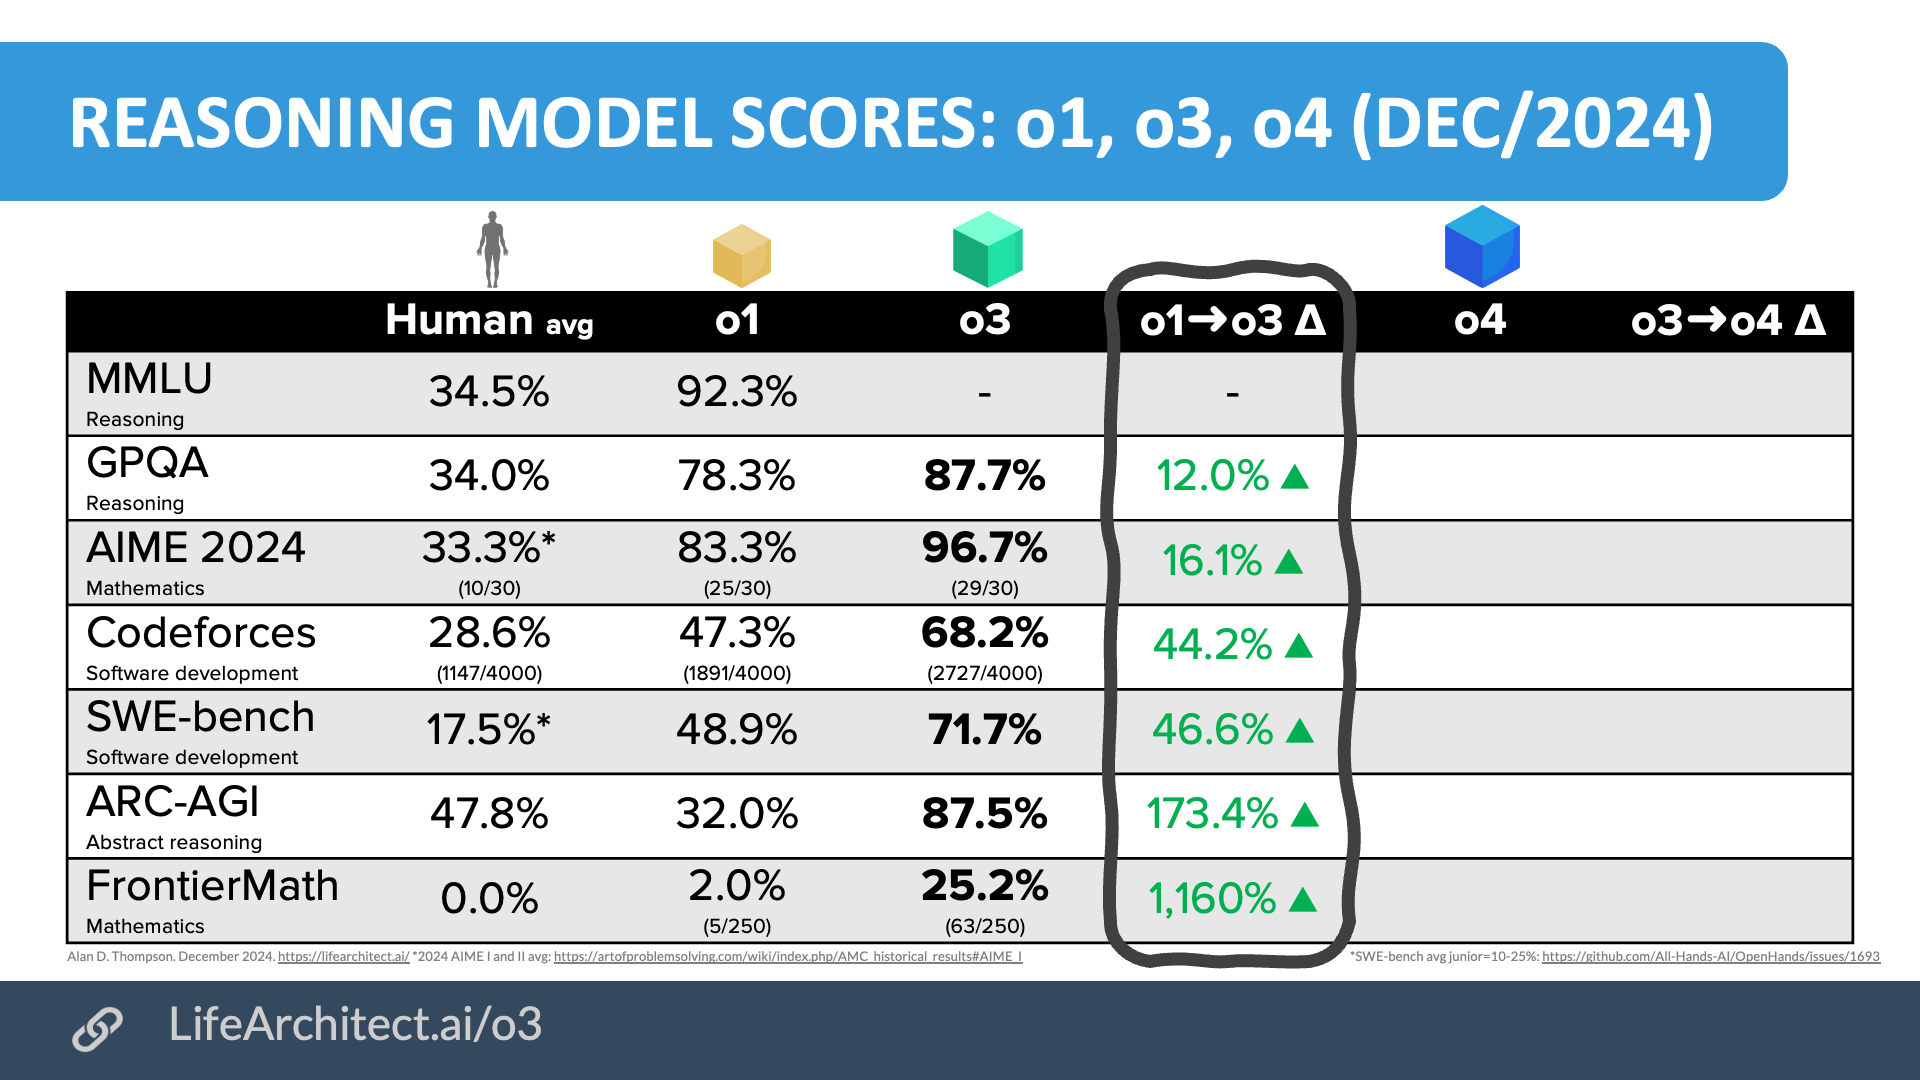
“imo the improvements on FrontierMath are even more impressive than ARG-AGI. Jump from 2% to 25% Terence Tao said the dataset should “resist AIs for several years at least” and “These are extremely challenging. I think that in the near term basically the only way to solve them,” / X
https://x.com/dmdohan/status/1870176374625054880
“@DavidSHolz Think most benchmarks are necessary not sufficient Beating ARC-AGI doesn’t mean you actually have AGI, but it would be surprising to have an AGI that couldn’t do it. Though FrontierMath is hard enough that we could have an AGI that doesn’t solve it, not sure here.” / X
https://x.com/dmdohan/status/1870182433020314004
“Today OpenAI announced o3, its next-gen reasoning model. We’ve worked with OpenAI to test it on ARC-AGI, and we believe it represents a significant breakthrough in getting AI to adapt to novel tasks. It scores 75.7% on the semi-private eval in low-compute mode (for $20 per task
https://x.com/fchollet/status/1870169764762710376
[AINews] o3 solves AIME, GPQA, Codeforces, makes 11 years of progress in ARC-AGI and 25% in FrontierMath • Buttondown
https://buttondown.com/ainews/archive/ainews-o3-solves-aime-gpqa-codeforces-makes-11/
“NEW: OpenAI just announced ‘o3’, a breakthrough AI model that significantly surpasses all previous models in benchmarks. —On ARC-AGI: o3 more than triples o1’s score on low compute and surpasses a score of 87% —On EpochAI’s Frontier Math: o3 set a new record, solving 25.2% of
https://x.com/rowancheung/status/1870169402248945822
“ARC-AGI scores for past five years of OpenAI models (updated w/ release dates)
https://x.com/goodside/status/1870243391814152544
OpenAI o3 Breakthrough High Score on ARC-AGI-Pub
https://arcprize.org/blog/oai-o3-pub-breakthrough
“New verified ARC-AGI-Pub SoTA! @OpenAI o3 has scored a breakthrough 75.7% on the ARC-AGI Semi-Private Evaluation. And a high-compute o3 configuration (not eligible for ARC-AGI-Pub) scored 87.5% on the Semi-Private Eval. 1/4
https://x.com/arcprize/status/1870169260850573333
“FrontierMath, the newly released Math-Benchmark is so hard that even GPT-4 solves less than 2% of problems 60+ Pro Mathematicians including by Math Professors crafted these problems and they are not in any training data. OpenAI o3 did 25% on THIS. 🔧 FrontierMath details: →
https://x.com/rohanpaul_ai/status/1871138447253238057
12 Days of OpenAI | OpenAI
https://openai.com/12-days/
“The thing about o3 is that my fellow academics were literally just starting to test o1 on hard problems in their field. It showed a lot or promise. Lots of interesting discussions about how to validate and incorporate it into academic work. Then o3 is announced & it is obsolete” / X
https://x.com/emollick/status/1870562305160937677
OpenAI’s Next Big AI Effort, GPT-5, Is Behind Schedule and Crazy Expensive – WSJ
https://www.wsj.com/tech/ai/openai-gpt5-orion-delays-639e7693
“Evals on 03 Model from OpenAI. More than 20% better than o1 models. On real-world software tasks.
https://x.com/rohanpaul_ai/status/1870170553304404363
Live blog: the 12th day of OpenAI—“Early evals for OpenAI o3”
https://simonwillison.net/2024/Dec/20/live-blog-the-12th-day-of-openai/
Work with Apps—12 Days of OpenAI: Day 11 – YouTube
“OpenAI board member @adamdangelo doesn’t want you to see this
https://x.com/tolgabilge_/status/1870904304049217725?s=46
Pre-Deployment Evaluation of OpenAI’s o1 Model | NIST
https://www.nist.gov/news-events/news/2024/12/pre-deployment-evaluation-openais-o1-model
Deliberative alignment: reasoning enables safer language models | OpenAI
https://openai.com/index/deliberative-alignment/
“Today, we shared evals for an early version of the next model in our o-model reasoning series: OpenAI o3
https://x.com/OpenAI/status/1870186518230511844
“OpenAI o3 does 71.7% on SWE-Bench verified!! And 2727 on Codeforces! Unbelievable.
https://x.com/deedydas/status/1870168289705414968
OpenAI cofounder Ilya Sutskever predicts the end of AI pre-training – The Verge
https://www.theverge.com/2024/12/13/24320811/what-ilya-sutskever-sees-openai-model-data-training
(2) o1 Turns Pro – by Zvi Mowshowitz
https://thezvi.substack.com/p/o1-turns-pro
ChatGPT now understands real-time video, seven months after OpenAI first demoed it | TechCrunch
ChatGPT now understands real-time video, seven months after OpenAI first demoed it
“OpenAI is prepping the next generation of its o1 reasoning model. But, due to a potential copyright/trademark conflict with British telecommunications firm O2, OpenAI has considered calling the next update “o3” and skipping “o2.” More here w/ @amir:
https://x.com/steph_palazzolo/status/1869919189240254781?s=46
“And that’s why OpenAI CFO Sarah Friar was saying a few days back about a possible $2000/month subscription. Thousands of Companies will still save significant payroll cost vs hiring a Graduate Engineer.
https://x.com/rohanpaul_ai/status/1870760234228347017
“Big OpenAI personnel news w/ @erinkwoo: Alec Radford, the lead author of OpenAI’s original GPT paper, is leaving to pursue independent research.
https://x.com/steph_palazzolo/status/1869848094009110826
“We verified the o3 results for OpenAI on @arcprize My first thought when I saw the prompt they used to claim their score was… “That’s it?” It was refreshing (impressive) to see the prompt be so simple “Find the common rule that maps an input grid to an output grid”
https://x.com/GregKamradt/status/1870208490096218244
OpenAI expands ChatGPT Canvas to all users | VentureBeat
“OpenAI o3 is 2727 on Codeforces which is equivalent to the #175 best human competitive coder on the planet. This is an absolutely superhuman result for AI and technology at large.
https://x.com/deedydas/status/1870175212328608232
OpenAI outlines new for-profit structure in bid to stay ahead in costly AI race | Reuters
https://www.reuters.com/technology/artificial-intelligence/openai-lays-out-plan-shift-new-for-profit-structure-2024-12-27/
Projects—12 Days of OpenAI: Day 7 – YouTube
What’s in GPT-5? (2024) – Dr Alan D. Thompson – LifeArchitect.ai
“OpenAI announced an expansion of its ChatGPT Search feature The feature is now freely available to all users alongside added voice search capabilities, and improved mobile features Important step towards an agentic future, particularly within Advanced Voice Mode” / X
https://x.com/adcock_brett/status/1870877933490831846
“OpenAI must have had a significant head start in understanding and applying the inference scaling law. One of the recent paper in this regard was “Large Language Monkeys: Scaling Inference Compute with Repeated Sampling” 👨🔧 The paper explores scaling inference compute by
https://x.com/rohanpaul_ai/status/1871132545183781146
“o3 looks too expensive for most use. But for work in academia, finance & many industrial problems, paying hundreds or even thousands of dollars for a successful answer would not be we prohibitive. If it is generally reliable, o3 will have multiple use cases even before costs drop”
https://x.com/emollick/status/1870744609649045633
“Congratulations to everyone who worked on o3 — today is a historic day”
https://x.com/goodside/status/1870213699341885485
“i think the wsj is the overall best us newspaper right now, but they published an article called “The Next Great Leap in AI Is Behind Schedule and Crazy Expensive” many hours after we announced o3?!”
https://x.com/sama/status/1870709421111984135
“fine one clue should have said oh oh oh”
https://x.com/sama/status/1869963879671013774
o3: Stratospheric reasoning – Dr Alan D. Thompson – LifeArchitect.ai
(2) o3: The grand finale of AI in 2024 – by Nathan Lambert
https://www.interconnects.ai/p/openais-o3-the-2024-finale-of-ai